
Blog
Blog
News, resources, and updates about AI Model Comparison
Artificial Analysis Intelligence Index Model Ranking for Developers
A developer-focused reading of the Artificial Analysis Intelligence Index leaderboard, covering aggregate capability, coding performance, cost tradeoffs, production limits, and model selection.
Read More
Agnes 2.5 Pro Alpha vs GPT-5 mini (high): Which Model Should Developers Choose?
A data-led comparison of Agnes 2.5 Pro Alpha and GPT-5 mini (high), covering coding, intelligence, mathematics, speed, pricing, availability, and selection risks.
Read More
Agnes 2.5 Pro Alpha vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Agnes 2.5 Pro Alpha and GPT-5 (high), covering coding performance, cost, latency, API maturity, evidence quality, and deployment risk.
Read More
Agnes 2.5 Pro Alpha vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Agnes 2.5 Pro Alpha and o3, covering measured performance, cost, documentation risk, and production suitability.
Read More
Claude 4.1 Opus (Reasoning) vs GPT-5 (low): Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.1 Opus (Reasoning) and GPT-5 (low), covering benchmark signals, cost, availability, evidence quality, and practical selection criteria.
Read More
Claude 4.1 Opus (Reasoning) vs GPT-5 (medium): Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.1 Opus (Reasoning) and GPT-5 (medium), covering benchmark results, pricing, availability, evidence gaps, and practical selection criteria.
Read More
Claude 4.1 Opus (Reasoning) vs GPT-5 mini (medium): Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.1 Opus (Reasoning) and GPT-5 mini (medium), covering measured quality, pricing, availability, evidence gaps, and deployment risk.
Read More
Claude 4.1 Opus (Reasoning) vs o3-pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.1 Opus (Reasoning) and o3-pro across availability, reasoning evidence, latency, pricing, and deployment risk.
Read More
Claude 4.1 Opus (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.1 Opus (Reasoning) and o3 across measured intelligence, mathematics, speed, cost, availability, and evidence quality.
Read More
Claude 4.5 Haiku (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.5 Haiku (Reasoning) and GPT-5 (high), covering coding, reasoning, speed, pricing, reliability, and model lifecycle risk.
Read More
Claude 4.5 Sonnet (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.5 Sonnet (Reasoning) and GPT-5 (high), covering coding, mathematics, latency, pricing, API stability, and evidence gaps.
Read More
Claude 4.5 Sonnet (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.5 Sonnet (Reasoning) and o3 across intelligence, mathematics, coding evidence, speed, cost, and API availability risk.
Read More
Claude 4.5 Sonnet vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude 4.5 Sonnet Non-reasoning and GPT-5 high across capability, latency, pricing, API status, and practical selection criteria.
Read More
Claude Fable 5 vs Claude Opus 4.8: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and Claude Opus 4.8 across capability, speed, cost, agent behavior, lifecycle, and deployment risk.
Read More
Claude Fable 5 vs Claude Opus 5: Which Model Should Developers Choose?
A source-linked comparison of Claude Fable 5 and Claude Opus 5 for coding agents, production APIs, cost-sensitive workloads, and long-running automation.
Read More
Claude Fable 5 vs Claude Opus 5 Medium: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and Claude Opus 5 Medium across coding quality, output speed, pricing, agent behavior, integration risks, and production fit.
Read More
Claude Fable 5 vs Claude Opus 5 Xhigh: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and Claude Opus 5 across quality, speed, pricing, agent behavior, and integration risk.
Read MoreClaude Fable 5 vs Claude Opus 5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and Claude Opus 5 across quality, speed, cost, agent behavior, controls, and operational risk.
Read More
Claude Fable 5 vs DeepSeek V4 Pro: Which Reasoning Model Should Developers Choose?
Claude Fable 5 leads on measured capability and coding, while DeepSeek V4 Pro offers far lower token pricing and lower response latency.
Read More
Claude Fable 5 vs DeepSeek V4 Pro: Agent Quality or Fast, Low-Cost Generation?
Claude Fable 5 leads on measured capability and agent-oriented controls, while DeepSeek V4 Pro offers much lower token pricing and far lower initial latency, with important version-status uncertainty.
Read More
Claude Fable 5 vs DeepSeek V4 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and DeepSeek V4 Pro across capability, speed, cost, reliability, and production fit.
Read More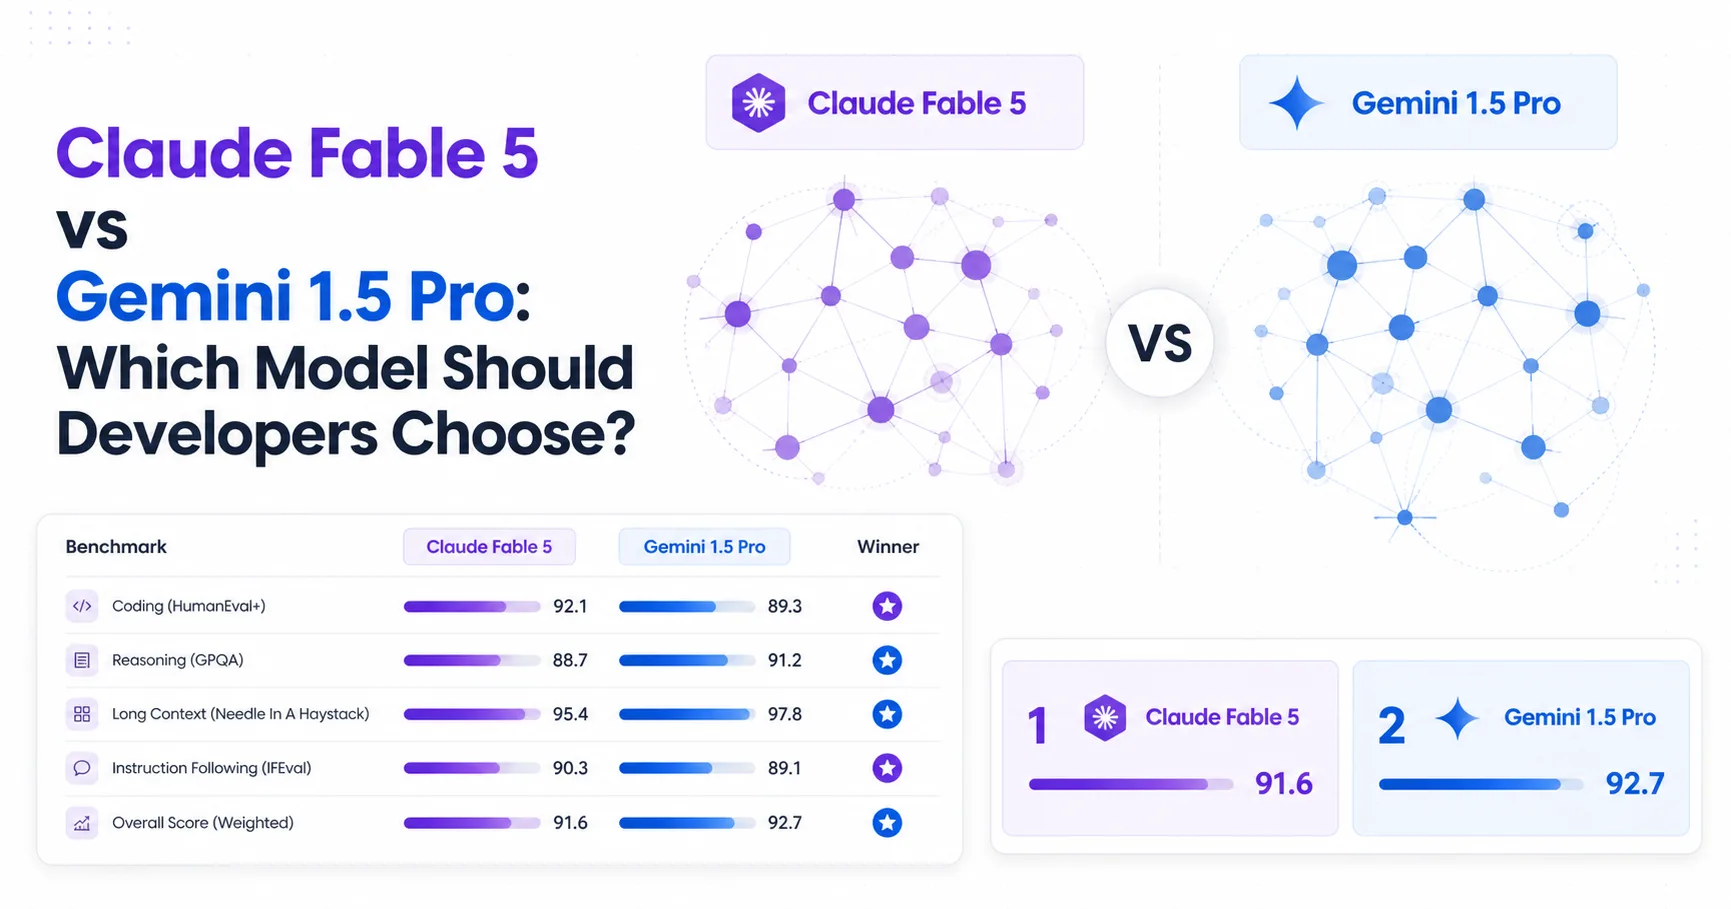
Claude Fable 5 vs Gemini 1.5 Pro: Which Model Should Developers Choose?
Claude Fable 5 offers a clear measured advantage for coding and general intelligence, while Gemini 1.5 Pro remains cheaper but carries substantial availability and compatibility uncertainty.
Read More
Claude Fable 5 vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-4 covering capability evidence, operational risk, speed, pricing, availability, and model-selection trade-offs.
Read More
Claude Fable 5 vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-4o mini across capability, latency, cost, availability, and production risk.
Read More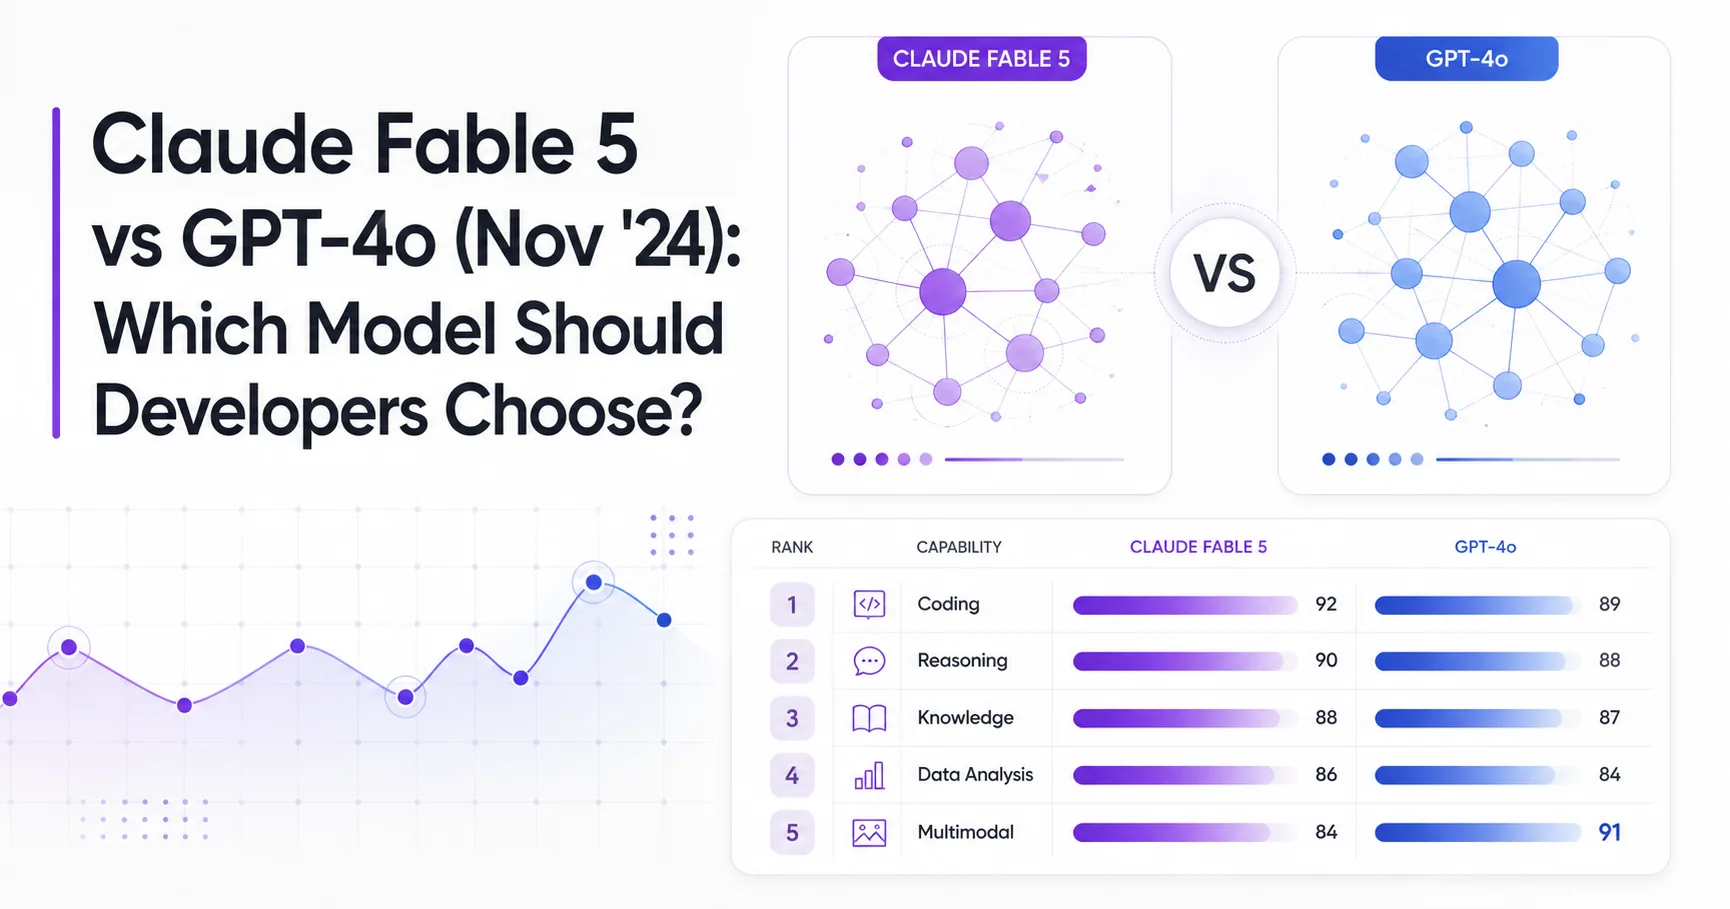
Claude Fable 5 vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-4o (Nov '24), covering capability evidence, speed, pricing, operational risk, and model availability.
Read More
Claude Fable 5 vs GPT-5.5 for Developers: Capability, Cost, and Agent Control
A developer-focused comparison of Claude Fable 5 and GPT-5.5 across capability, speed, cost, agent behavior, and production risk.
Read More
Claude Fable 5 vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-5.6 Sol (high), covering measured quality, speed, cost, agent behavior, and production risks.
Read More
Claude Fable 5 vs GPT-5.6 Sol (xhigh): Which AI Model Should Developers Choose?
A developer-focused comparison of coding quality, analytical breadth, speed, cost, tooling, and production risks for Claude Fable 5 and GPT-5.6 Sol (xhigh).
Read More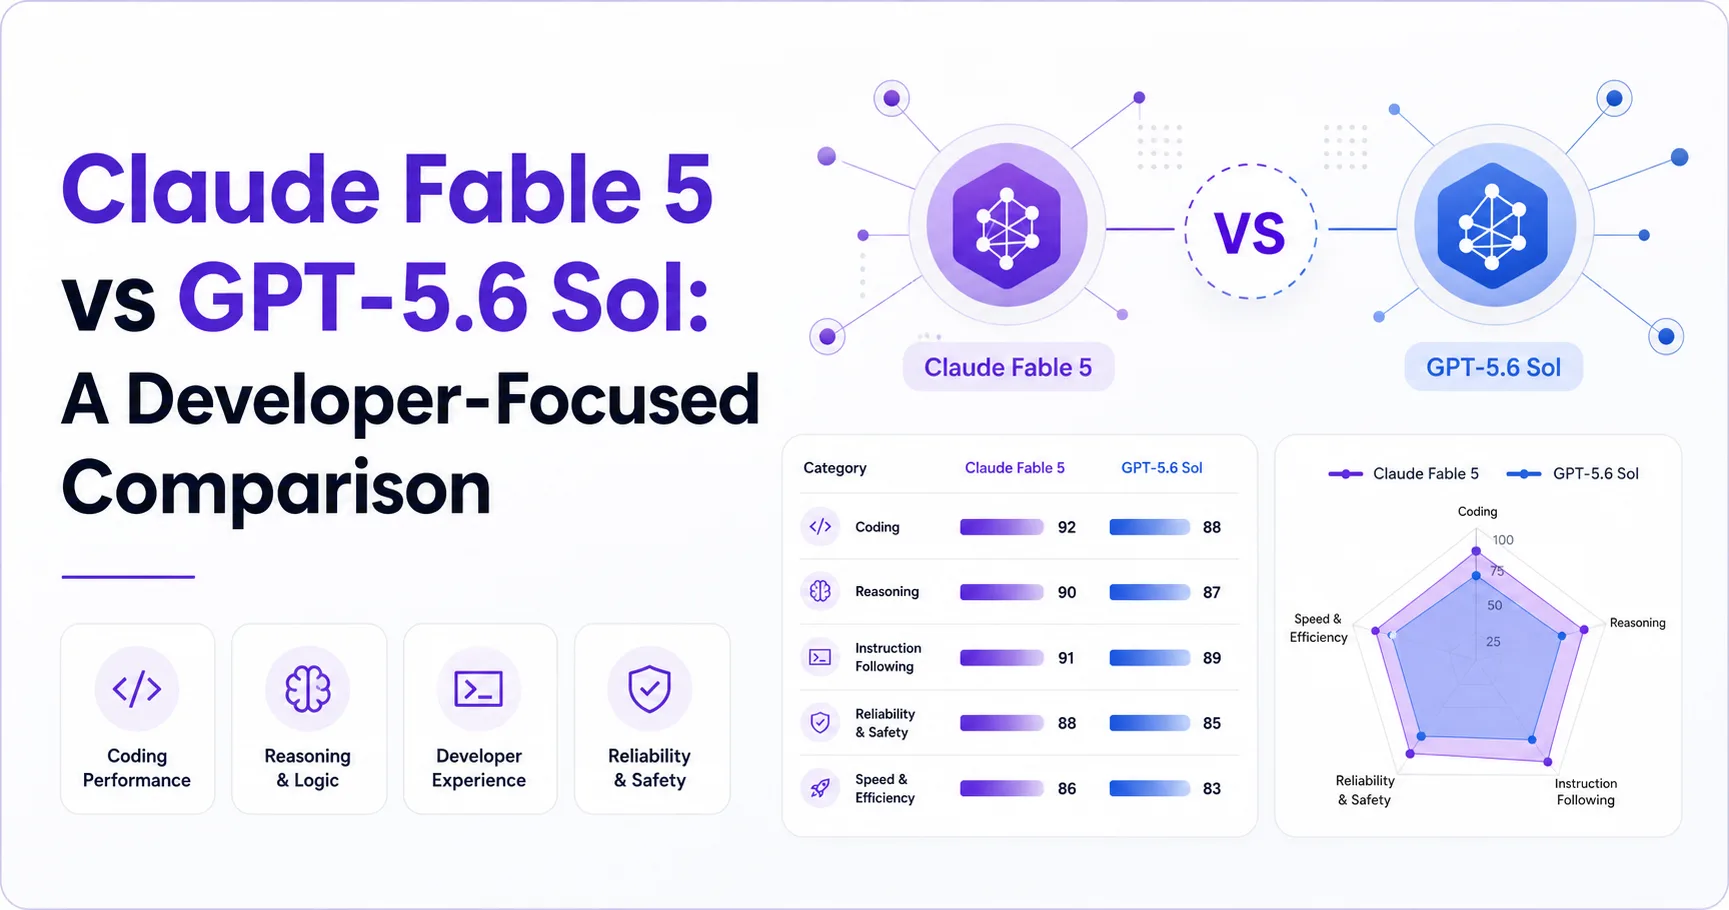
Claude Fable 5 vs GPT-5.6 Sol: A Developer-Focused Comparison
A practical comparison of Claude Fable 5 and GPT-5.6 Sol for coding agents, long-running workflows, cost control, and production deployment.
Read More
Claude Fable 5 vs GPT-5.6 Terra: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-5.6 Terra across intelligence, coding, speed, cost, agent behavior, and production risks.
Read More
Claude Fable 5 vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-5 mini (high), covering capability, cost, speed, reliability, and evidence gaps.
Read More
Claude Fable 5 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-5 nano covering capability evidence, speed, cost, availability, reliability, and practical model selection.
Read More
Claude Fable 5 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and GPT-5 across coding quality, reasoning, speed, cost, API control, and production risk.
Read More
Claude Fable 5 vs Kimi K3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and Kimi K3 across quality, coding, speed, pricing, agent behavior, tooling, and production risk.
Read More
Claude Fable 5 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Fable 5 and o3 across capability evidence, speed, cost, availability, and operational risk.
Read More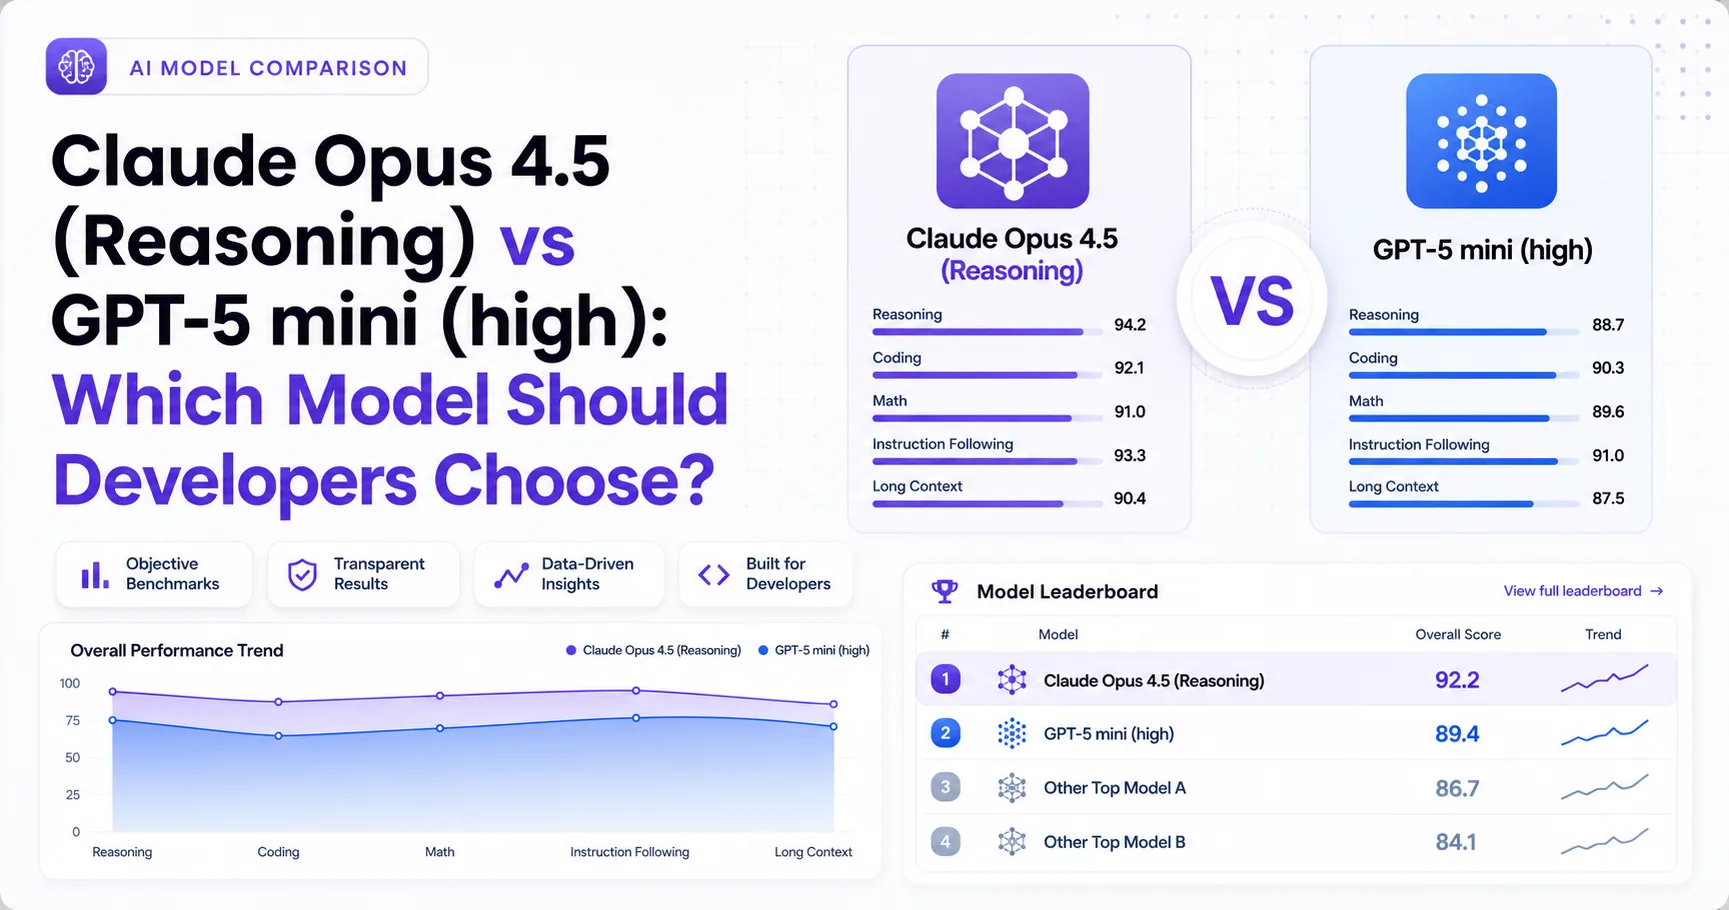
Claude Opus 4.5 (Reasoning) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.5 (Reasoning) and GPT-5 mini (high), covering measured quality, math, coding evidence, latency, pricing, API certainty, and selection risk.
Read More
Claude Opus 4.5 Reasoning vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.5 Reasoning and GPT-5 High across capability signals, coding evidence, latency, pricing, version stability, and deployment risk.
Read More
Claude Opus 4.5 (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.5 (Reasoning) and o3 across intelligence, mathematics, speed, pricing, availability, and deployment risk.
Read MoreClaude Opus 4.5 vs GPT-5: Which API Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.5 and GPT-5 across capability signals, latency, pricing, version stability, and practical API trade-offs.
Read More
Claude Opus 4.5 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.5 and o3 across benchmark results, speed, pricing, availability evidence, and production risk.
Read More
Claude Opus 4.6 Adaptive vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 Adaptive and GPT-5 mini across intelligence, latency, pricing, availability, and evidence quality.
Read More
Claude Opus 4.6 Adaptive vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 Adaptive and GPT-5 nano across intelligence evidence, latency, pricing, availability, and selection risk.
Read More
Claude Opus 4.6 Adaptive vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 Adaptive and GPT-5 High across intelligence, coding evidence, latency, pricing, API readiness, and operational risk.
Read More
Claude Opus 4.6 Adaptive vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 Adaptive and o3 across intelligence, mathematics, latency, output speed, pricing, availability, and evidence quality.
Read More
Claude Opus 4.6 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 and GPT-5 mini across intelligence, cost, latency, availability, and evidence quality.
Read More
Claude Opus 4.6 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 and GPT-5 across intelligence, coding evidence, latency, pricing, API stability, and production risk.
Read More
Claude Opus 4.6 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.6 and o3 covering documented availability, measured performance, cost, speed, and selection risks.
Read More
Claude Opus 4.7 Non-reasoning vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 Non-reasoning High Effort and GPT-5 mini, covering measured intelligence, cost, evidence gaps, and practical selection criteria.
Read More
Claude Opus 4.7 Non-reasoning vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 (Non-reasoning, High Effort) and GPT-5 (high), covering capability signals, pricing, latency, API certainty, and selection risks.
Read More
Claude Opus 4.7 Non-reasoning vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 Non-reasoning and o3 across intelligence, mathematics, speed, cost, API visibility, and selection risk.
Read More
Claude Opus 4.7 vs Gemini 1.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 and Gemini 1.5 Pro, covering capability signals, API availability, pricing, latency, long-context risk, and migration decisions.
Read More
Claude Opus 4.7 vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 and GPT-4o (Nov '24), covering measured intelligence, price, latency, API evidence, operational risk, and model availability uncertainty.
Read More
Claude Opus 4.7 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 and GPT-5 mini across coding quality, reasoning, cost, latency, availability, and operational risk.
Read More
Claude Opus 4.7 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 and GPT-5 nano across intelligence, mathematics, coding evidence, cost, availability, and production risk.
Read More
Claude Opus 4.7 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 and GPT-5 across coding, reasoning, mathematics, latency, pricing, API behavior, and production risk.
Read More
Claude Opus 4.7 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.7 and o3 across intelligence, coding evidence, speed, cost, availability, and production risk.
Read More
Claude Opus 4.8 vs Claude Opus 5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and Claude Opus 5 across capability evidence, speed, pricing, migration risk, and agent reliability.
Read More
Claude Opus 4.8 vs Claude Opus 5 Medium: A Developer Selection Guide
A developer-focused comparison of Claude Opus 4.8 and Claude Opus 5 Medium across intelligence, coding, speed, cost, reliability, and agent workflows.
Read More
Claude Opus 4.8 vs Claude Opus 5 Xhigh: Which Model Should Developers Choose?
A developer-focused comparison of capability, speed evidence, pricing, agent behavior, and integration risk for Claude Opus 4.8 and Claude Opus 5.
Read More
Claude Opus 4.8 vs Claude Opus 5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and Claude Opus 5 covering capability, coding, speed, pricing, reliability, and deployment risk.
Read More
Claude Opus 4.8 vs DeepSeek V4 Pro: Higher Coding Scores or Lower API Cost?
Claude Opus 4.8 leads the available coding and agent evaluations, while DeepSeek V4 Pro costs far less. The key selection risk is DeepSeek's unverified historical version status.
Read More
Claude Opus 4.8 vs DeepSeek V4 Pro: Capability, Cost, and Version Risk
Claude Opus 4.8 leads on the measured capability data, while DeepSeek V4 Pro offers far lower listed token costs and recorded output speed. The decisive trade-off is capability confidence versus operating cost and version certainty.
Read More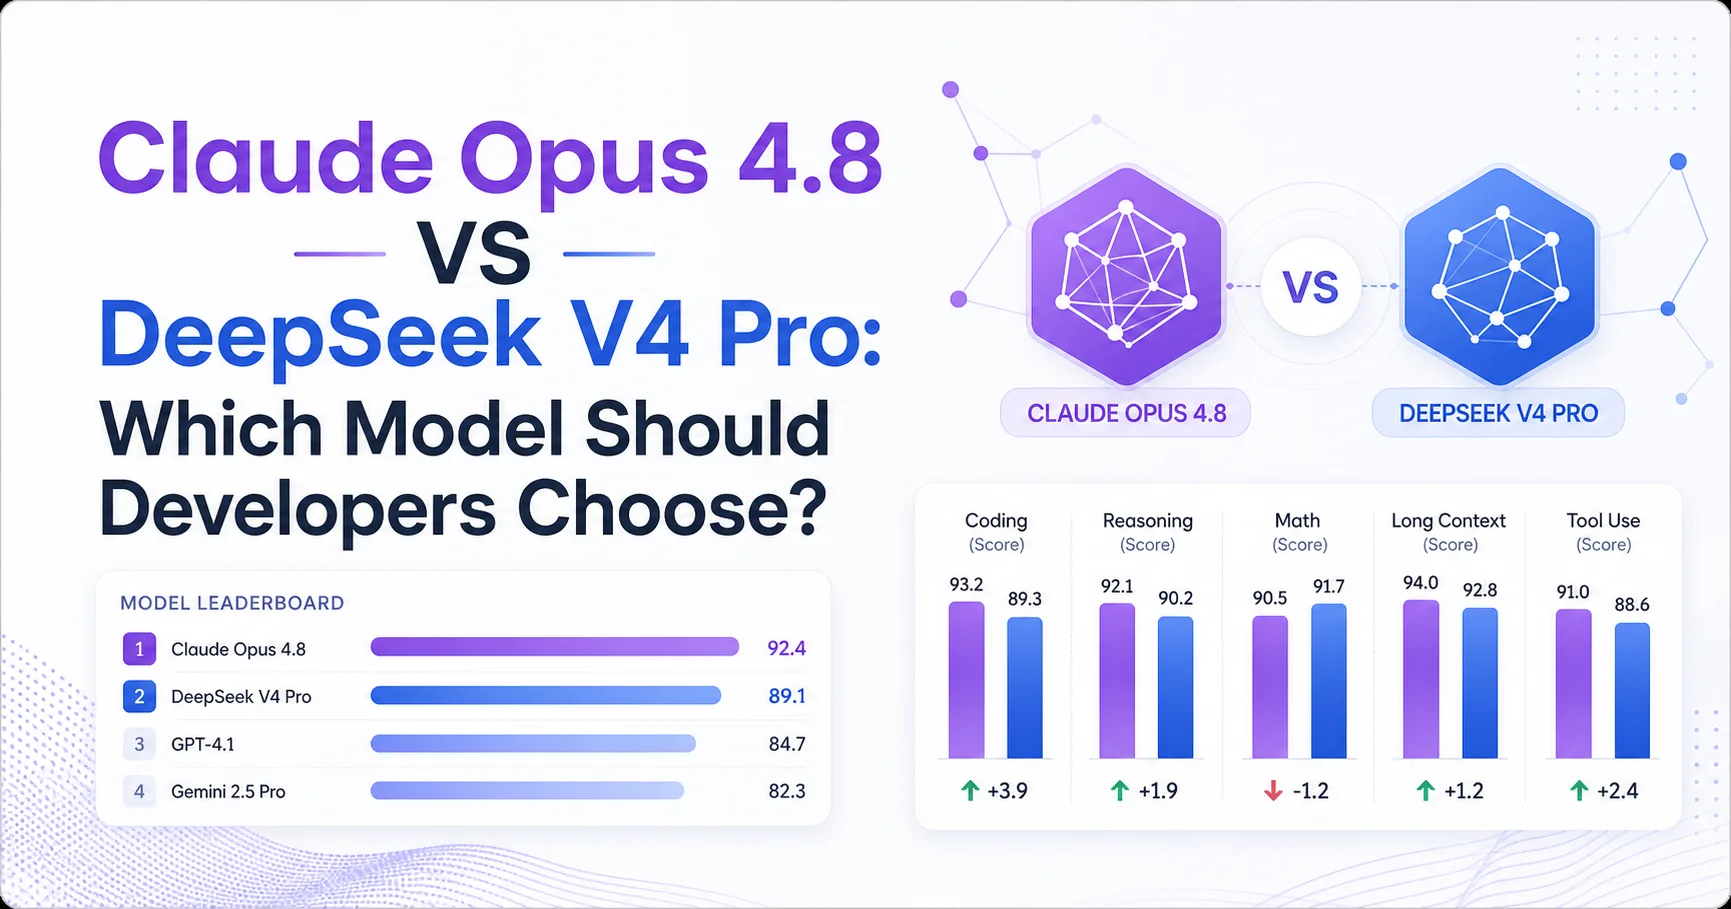
Claude Opus 4.8 vs DeepSeek V4 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and DeepSeek V4 Pro across capability, coding, speed, cost, reliability, and deployment risk.
Read More
Claude Opus 4.8 vs Gemini 1.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and Gemini 1.5 Pro covering capability evidence, operational availability, pricing, workflow risk, and model-selection guidance.
Read MoreClaude Opus 4.8 vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-4 across capability, coding performance, latency, pricing, reliability, and selection risk.
Read More
Claude Opus 4.8 vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-4o (Nov '24), covering capability evidence, cost, availability, workflow risks, and model-selection trade-offs.
Read More
Claude Opus 4.8 vs GPT-5.5: Developer Model Selection Guide
A developer-focused comparison of Claude Opus 4.8 and GPT-5.5 across reasoning, coding, latency, cost, tooling, reliability, and production fit.
Read More
Claude Opus 4.8 vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (high) and Claude Opus 4.8 across coding quality, speed, cost, tooling, and deployment risk.
Read More
Claude Opus 4.8 vs GPT-5.6 Sol (xhigh): A Developer's Model Selection Guide
A developer-focused comparison of Claude Opus 4.8 and GPT-5.6 Sol (xhigh), covering quality, cost, agent workflows, version status, and evidence gaps.
Read More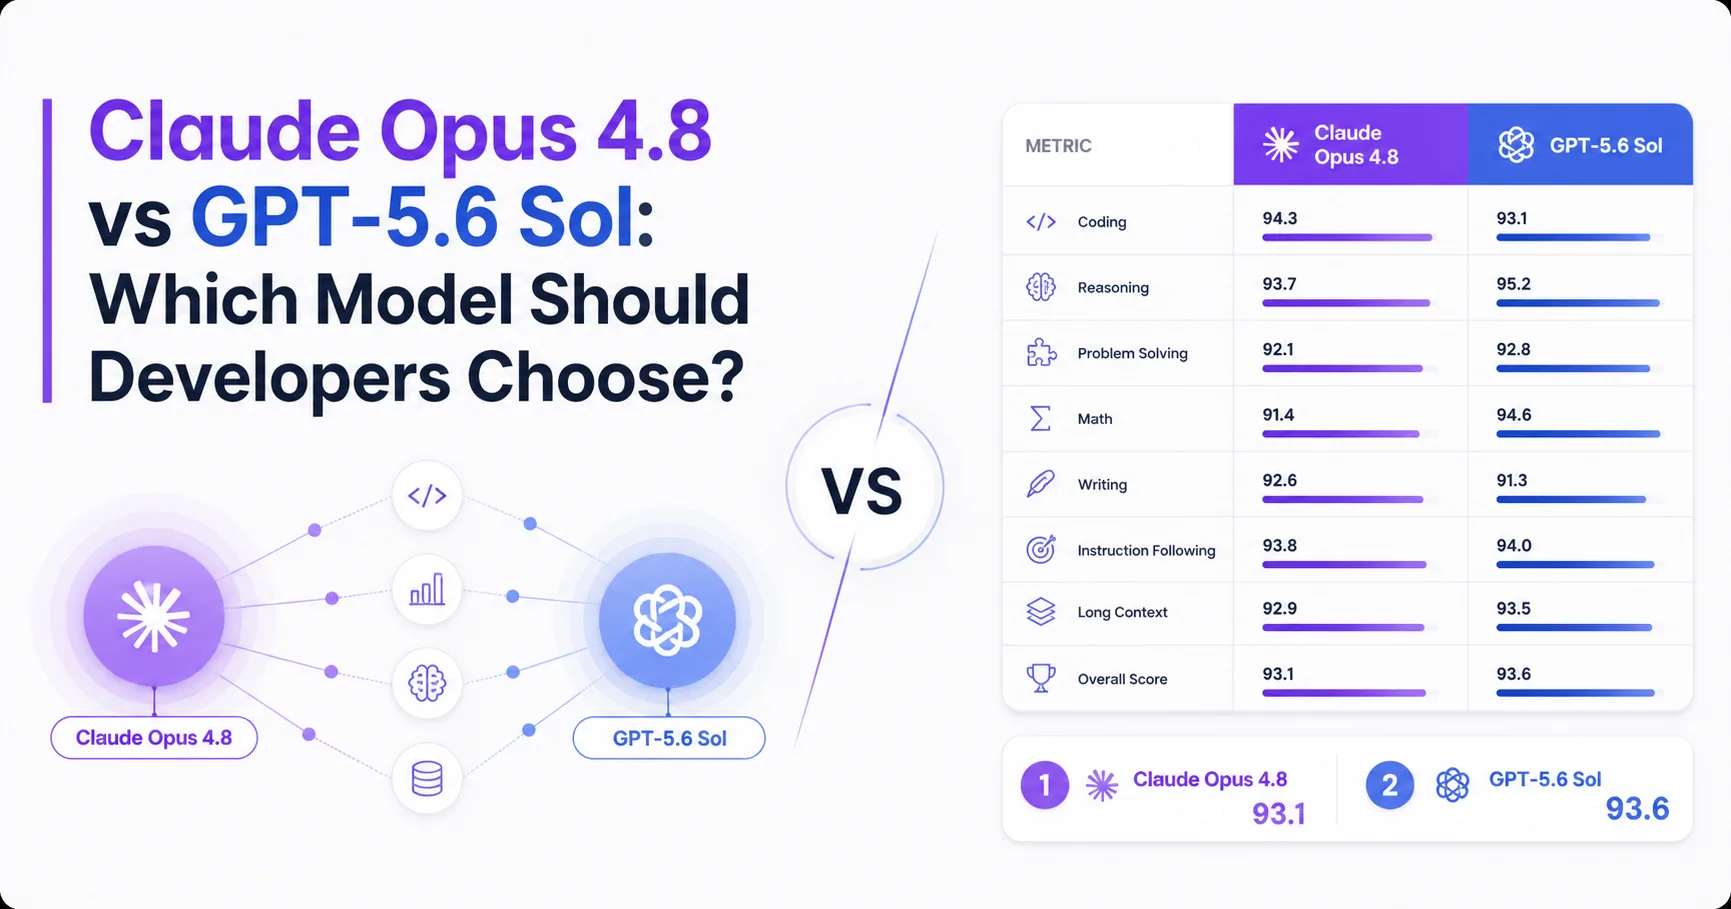
Claude Opus 4.8 vs GPT-5.6 Sol: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-5.6 Sol across performance, cost, tooling, reliability, and production fit.
Read More
Claude Opus 4.8 vs GPT-5.6 Terra: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-5.6 Terra across coding quality, reasoning, speed, cost, agent workflows, and production risks.
Read More
Claude Opus 4.8 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-5 mini across coding, reasoning, mathematics, latency, pricing, availability, and production risk.
Read More
Claude Opus 4.8 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-5 nano across intelligence, coding evidence, mathematics, latency, pricing, and production readiness.
Read More
Claude Opus 4.8 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and GPT-5 across coding, reasoning, cost, reliability, lifecycle risk, and agent workflows.
Read More
Claude Opus 4.8 vs Kimi K3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and Kimi K3 across capability, speed, cost, agent reliability, lifecycle, and production fit.
Read More
Claude Opus 4.8 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 4.8 and o3 across intelligence, coding evidence, speed, cost, availability, and operational risk.
Read More
Claude Opus 5 High vs Medium: Which Effort Setting Should Developers Choose?
A developer-focused comparison of Claude Opus 5 High Effort and Medium Effort across measured quality, speed, cost, API identity, and production tradeoffs.
Read More
Claude Opus 5 High vs Xhigh: Which Effort Setting Should Developers Choose?
A developer-focused comparison of Claude Opus 5 High and Xhigh across quality, speed, cost, integration behavior, and practical coding workflows.
Read More
Claude Opus 5 High vs Gemini 1.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 High and Gemini 1.5 Pro, covering coding performance, operational availability, pricing, latency, and migration risk.
Read More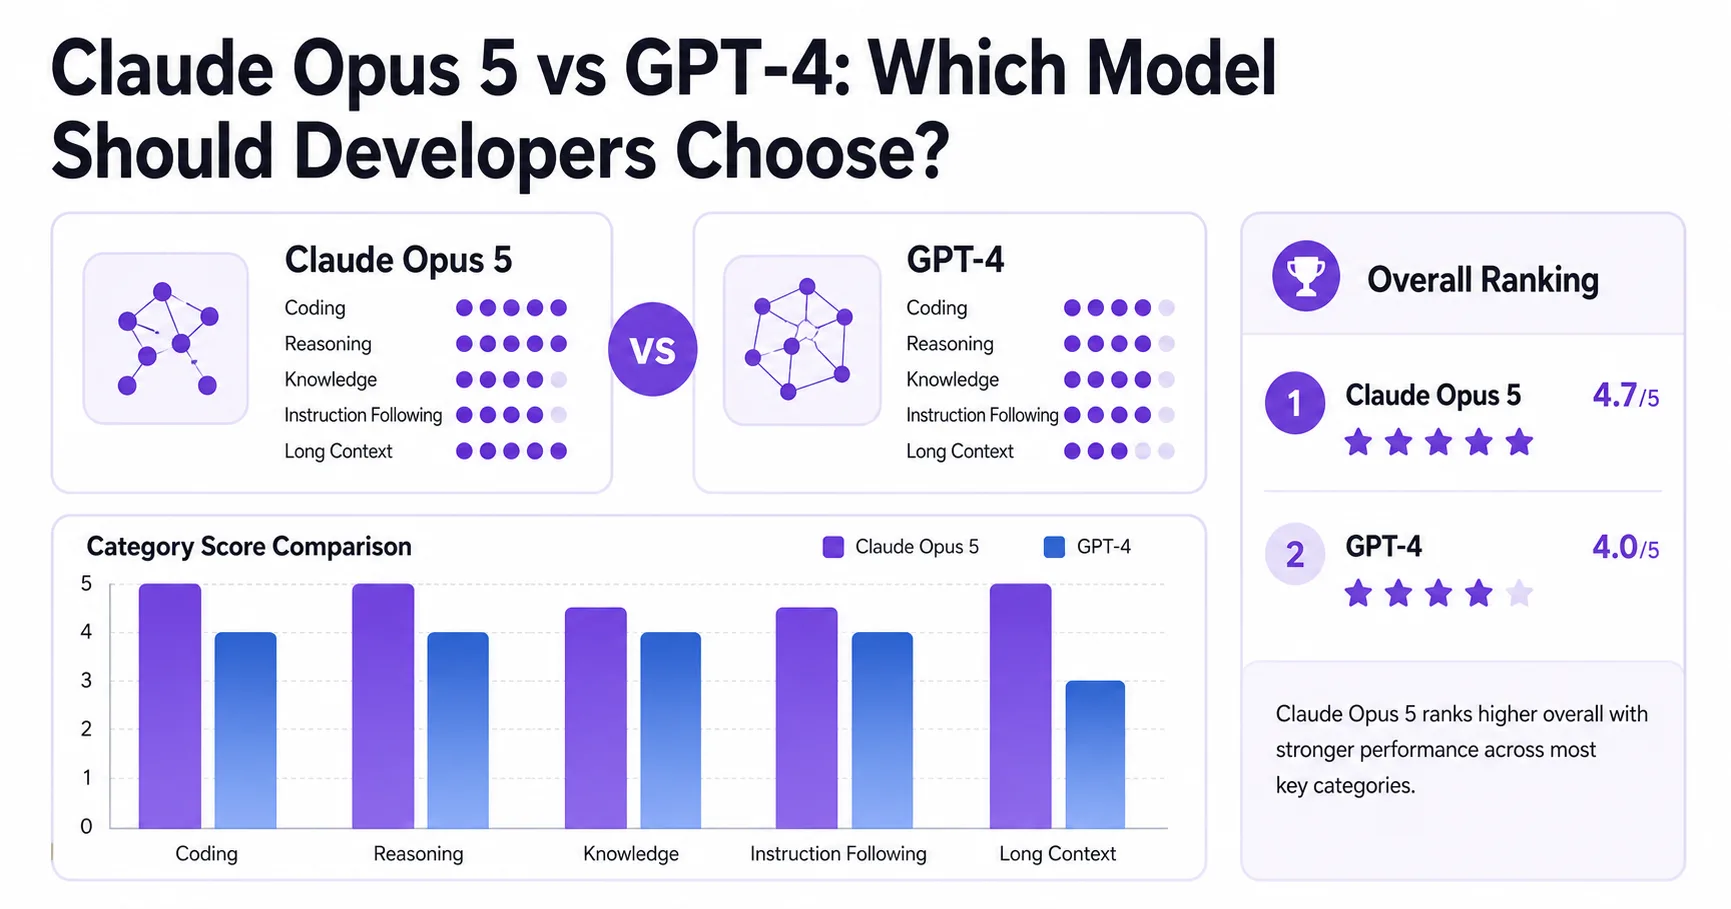
Claude Opus 5 vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-4 across capability, coding performance, speed, pricing, deployment confidence, and operational risk.
Read More
Claude Opus 5 vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-4o mini across capability, speed, cost, API behavior, lifecycle risk, and practical use cases.
Read More
Claude Opus 5 vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-4o (Nov '24), covering capability evidence, pricing, operational risk, and model-selection tradeoffs.
Read More
Claude Opus 5 vs GPT-5.5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.5 across intelligence, coding, speed, cost, tooling, reliability, and production fit.
Read More
Claude Opus 5 vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Sol across intelligence, coding, speed, cost, API identity, tools, and production risks.
Read More
Claude Opus 5 vs GPT-5.6 Sol: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Sol across coding performance, reasoning, speed, cost, APIs, and production risks.
Read More
Claude Opus 5 (High) vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
A developer-focused comparison of coding quality, throughput, cost, reasoning controls, integrations, and production risks.
Read More
Claude Opus 5 vs GPT-5.6 Terra: A Developer's Model Selection Guide
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Terra across reasoning quality, coding, speed, cost, tooling, deployment, and production risk.
Read More
Claude Opus 5 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5 mini across coding, intelligence, mathematics, speed, cost, API availability, and operational risk.
Read More
Claude Opus 5 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5 nano across intelligence, coding evidence, speed, cost, reliability, and model availability.
Read More
Claude Opus 5 High vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with adaptive high-effort reasoning and GPT-5 with high reasoning effort, covering coding quality, speed, cost, operational risk, and model lifecycle.
Read More
Claude Opus 5 High vs Grok-1: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 High and Grok-1 across measured intelligence, coding evidence, speed, cost, operational confidence, and model availability.
Read More
Claude Opus 5 vs Kimi K3 for Developers: Quality, Speed, Cost, and Production Fit
A developer-focused comparison of Claude Opus 5 and Kimi K3 across measured quality, speed, price, tooling, and production fit.
Read More
Claude Opus 5 High vs o3: Which Model Should Developers Choose?
Claude Opus 5 offers stronger measured general intelligence and coding evidence, while o3 is faster, cheaper, and stronger on the available math metric.
Read More
Claude Opus 5 Low Effort vs GPT-5 mini High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with low adaptive effort and GPT-5 mini with high effort, covering coding quality, evidence gaps, speed, cost, and production risk.
Read More
Claude Opus 5 Low vs GPT-5 nano High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with low adaptive reasoning and GPT-5 nano with high reasoning, covering capability evidence, speed, cost, availability, and selection risk.
Read More
Claude Opus 5 Low vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with low effort and GPT-5 with high reasoning effort, covering coding quality, cost, speed, reliability, and deployment risk.
Read More
Claude Opus 5 Low vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with low adaptive reasoning and OpenAI o3, covering capability evidence, speed, cost, operational risk, and model availability.
Read More
Claude Opus 5 Medium vs Xhigh: Which Effort Setting Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Medium and Xhigh across coding quality, speed, cost, API identity, and production risk.
Read More
Claude Opus 5 Medium vs Gemini 1.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and Gemini 1.5 Pro (Sep '24), covering availability, coding quality, speed, cost, and migration risk.
Read More
Claude Opus 5 Medium vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and GPT-4 across coding quality, intelligence, speed, pricing, availability, and integration risk.
Read More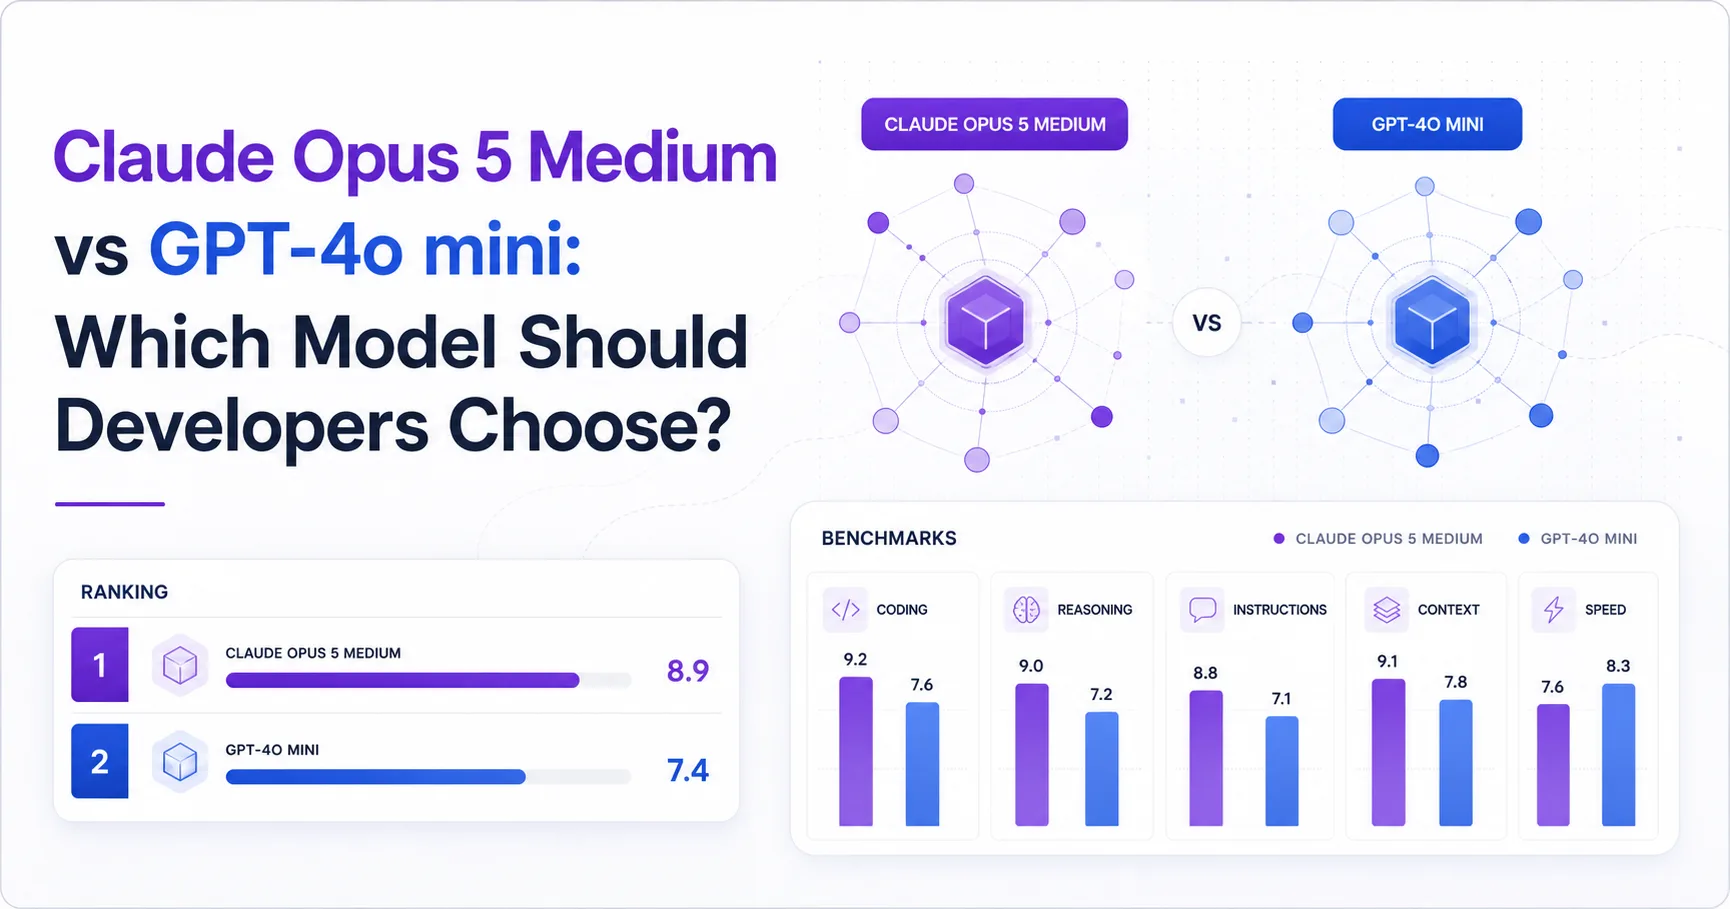
Claude Opus 5 Medium vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and GPT-4o mini across coding quality, latency, cost, model availability, and production risk.
Read More
Claude Opus 5 Medium vs GPT-4o: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and GPT-4o (Nov '24), covering capability evidence, pricing, operational risk, and model selection.
Read More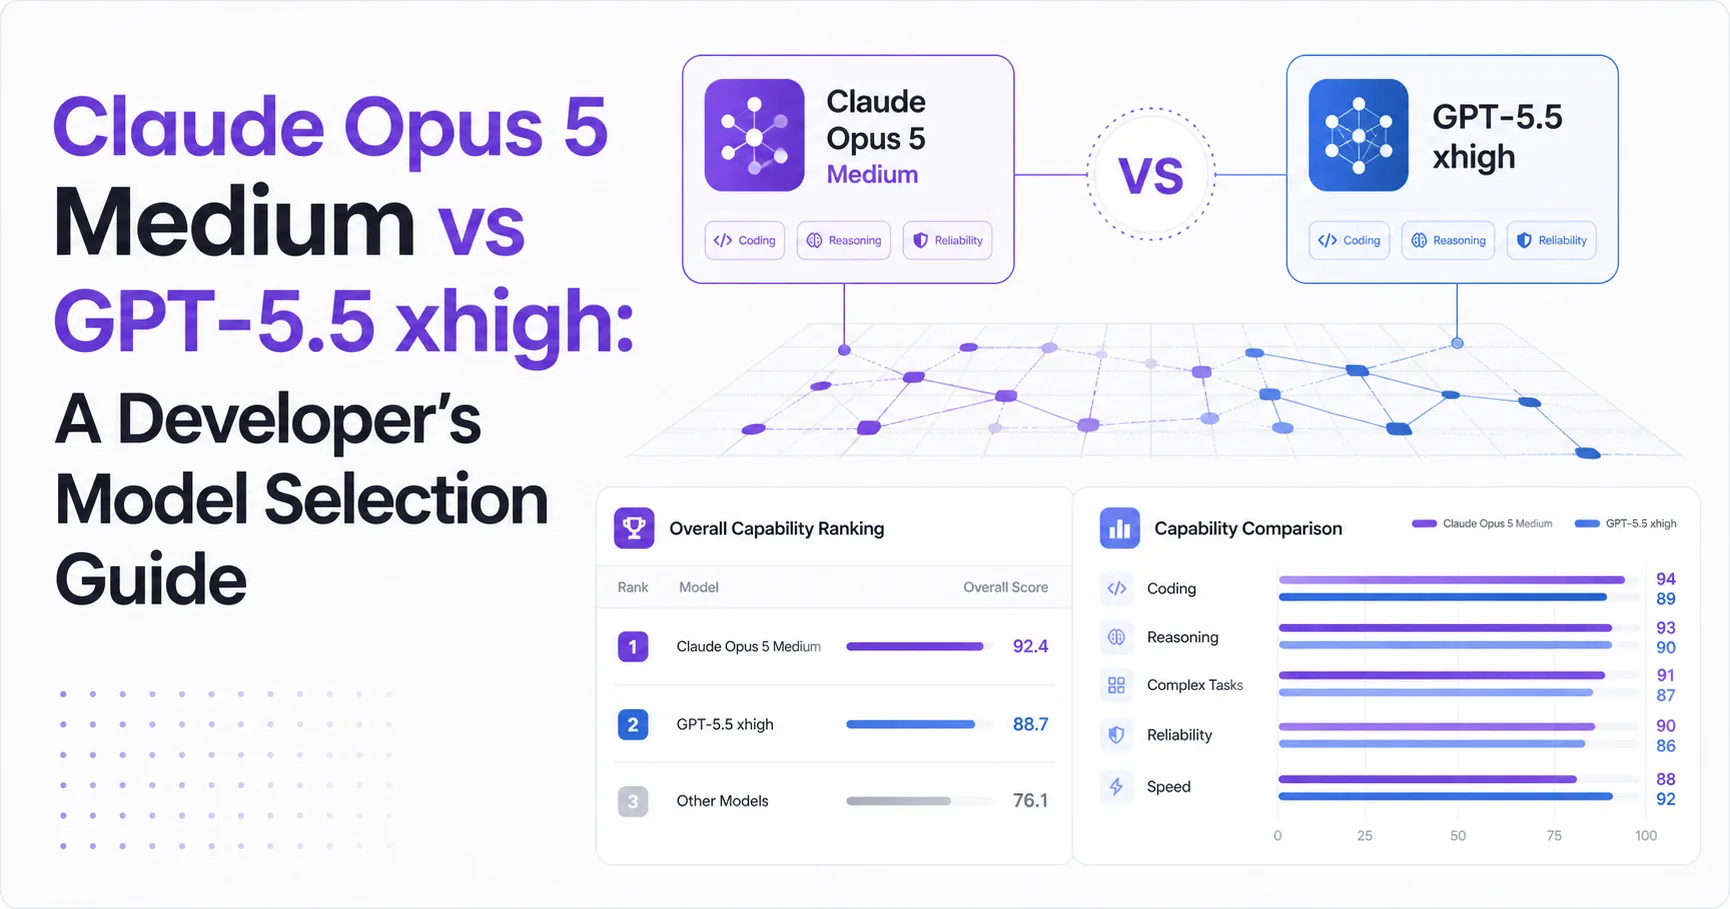
Claude Opus 5 Medium vs GPT-5.5 xhigh: A Developer's Model Selection Guide
A developer-focused comparison of Claude Opus 5 and GPT-5.5 across coding quality, general intelligence, speed evidence, cost, reliability, and agent workflows.
Read More
Claude Opus 5 Medium vs GPT-5.6 Sol High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Medium and GPT-5.6 Sol High across coding quality, output speed, API cost, tooling, reliability, and deployment risk.
Read More
Claude Opus 5 Medium vs GPT-5.6 Sol xhigh: Which Model Should Developers Choose?
A developer-focused comparison of coding quality, output speed, pricing, API configuration, and production risks.
Read More
Claude Opus 5 Medium vs GPT-5.6 Sol Max: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Medium and GPT-5.6 Sol Max across measured performance, throughput, cost, deployment, and workflow risk.
Read More
Claude Opus 5 Medium vs GPT-5.6 Terra (max): Which Model Should Developers Choose?
A developer-focused comparison of coding quality, reasoning, speed, cost, API behavior, and workload fit.
Read More
Claude Opus 5 Medium vs GPT-5 mini High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium effort and GPT-5 mini with high effort, covering coding quality, speed, pricing, reliability, and model availability.
Read More
Claude Opus 5 Medium vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and GPT-5 nano high, covering capability evidence, speed, cost, availability, and selection risks.
Read More
Claude Opus 5 Medium vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and GPT-5 with high reasoning effort, covering coding quality, mathematics, latency, pricing, version risk, and practical fit.
Read More
Claude Opus 5 Medium vs Kimi K3 Max: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Medium and Kimi K3 Max across quality, speed, cost, integration risks, and production fit.
Read More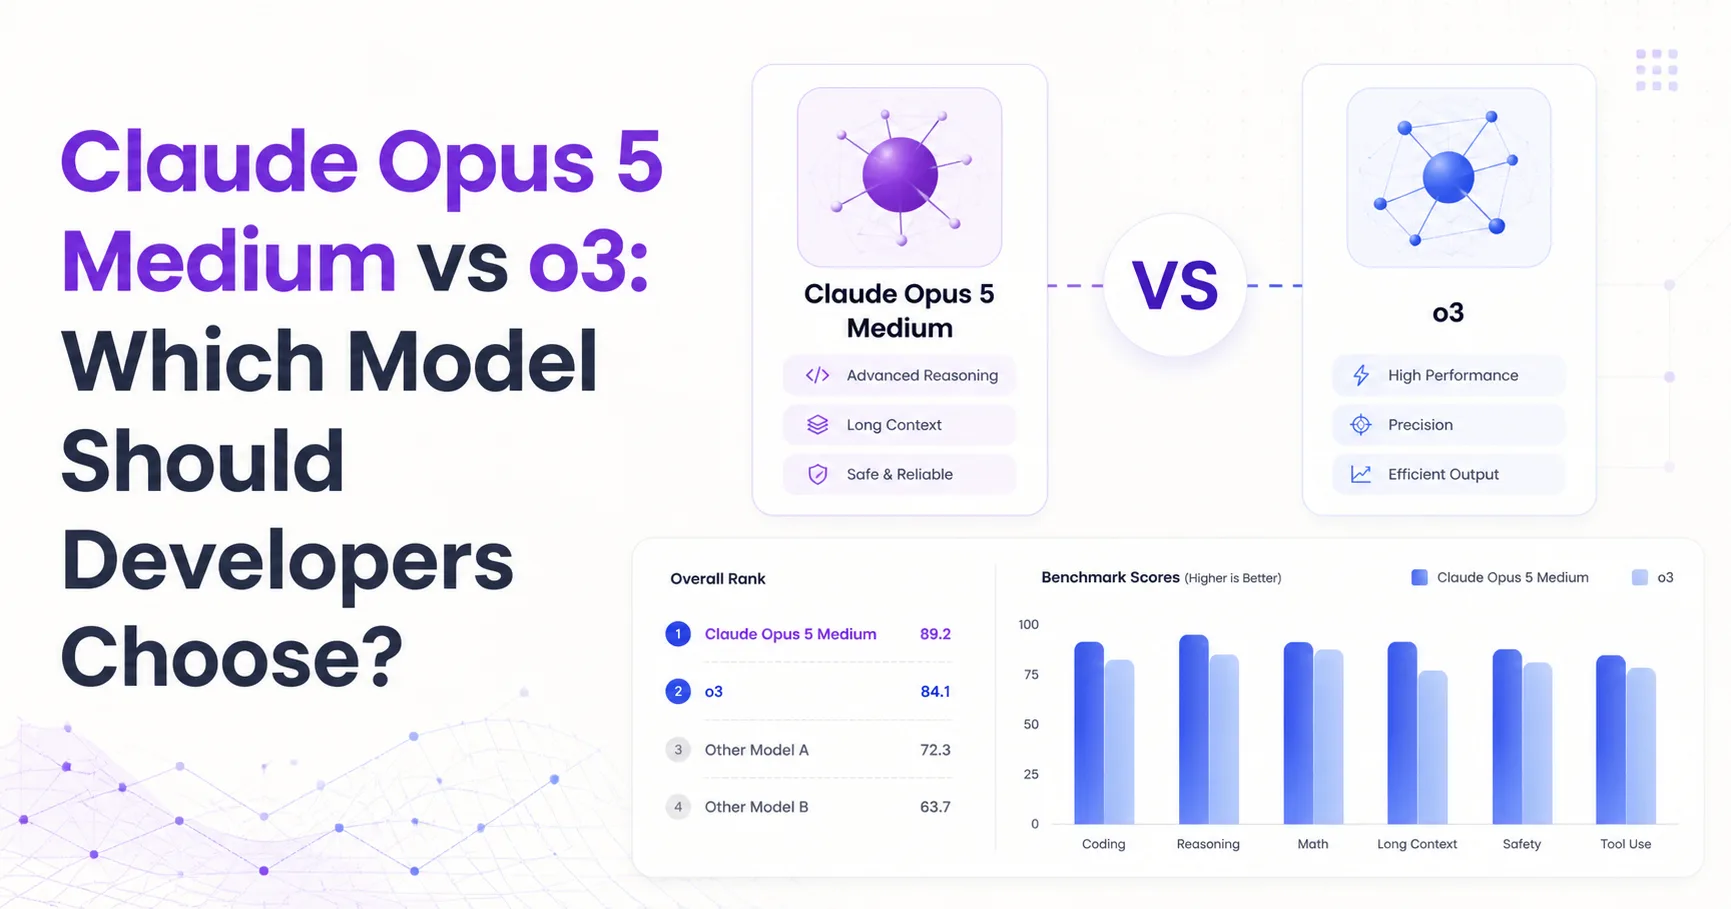
Claude Opus 5 Medium vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with medium adaptive reasoning and OpenAI o3, covering capability evidence, speed, cost, reliability, and model availability.
Read More
Claude Opus 5 Max Effort vs High Effort: Which Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Max Effort and High Effort for coding agents, interactive tools, cost control, and production integration.
Read More
Claude Opus 5 Max Effort vs Medium Effort: Which Should Developers Choose?
A developer-focused comparison of Claude Opus 5 reasoning settings, covering quality, speed, cost, production risks, and deployment choices.
Read More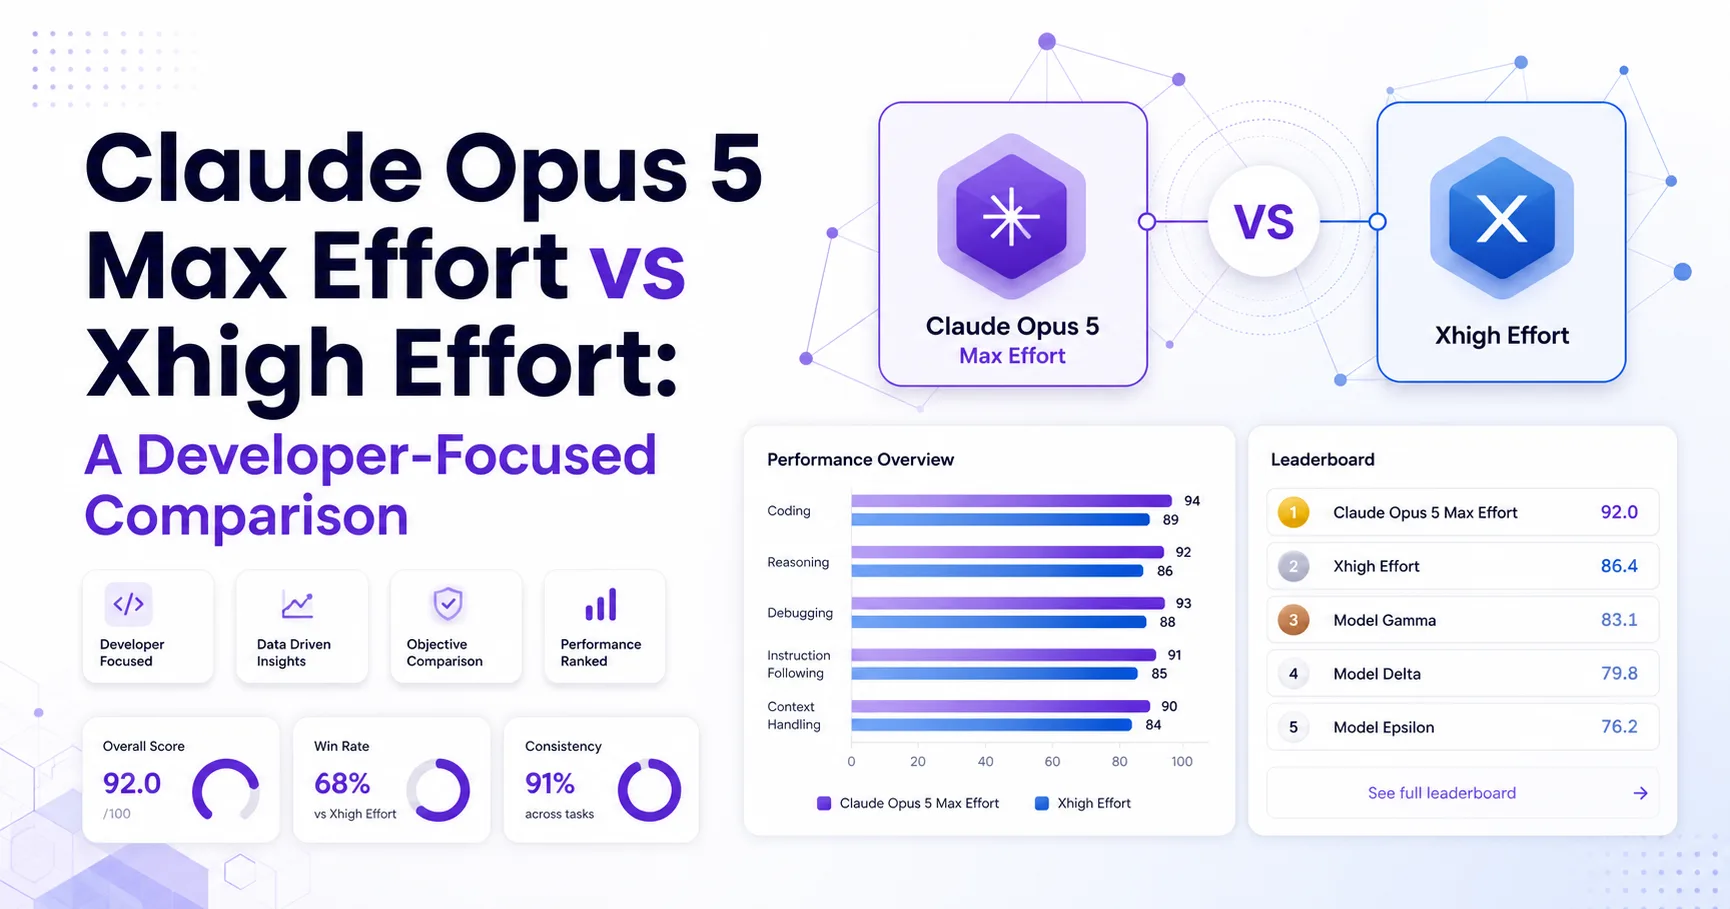
Claude Opus 5 Max Effort vs Xhigh Effort: A Developer-Focused Comparison
A source-grounded comparison of Claude Opus 5 Max Effort and Xhigh Effort for coding, agent workflows, cost control, and production model selection.
Read More
Claude Opus 5 vs DeepSeek V4 Pro: Capability, Cost, and Version Risk
Claude Opus 5 leads the available coding and intelligence data, while DeepSeek V4 Pro offers much lower listed token costs and faster output. The key decision risk is incomplete official evidence for the DeepSeek historical version.
Read More
Claude Opus 5 vs DeepSeek V4 Pro (Non-reasoning): Which Model Should Developers Choose?
Claude Opus 5 leads on the shared quality signals, while DeepSeek V4 Pro (Non-reasoning) is cheaper and faster. Version evidence limits a clean production recommendation.
Read More
Claude Opus 5 vs DeepSeek V4 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and DeepSeek V4 Pro across capability, speed, cost, reliability evidence, and practical deployment trade-offs.
Read More
Claude Opus 5 vs Gemini 1.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and Gemini 1.5 Pro, covering capability, speed, pricing, availability, operational risk, and practical model selection.
Read More
Claude Opus 5 vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-4 across capability signals, cost, speed, lifecycle certainty, and practical model-selection risk.
Read More
Claude Opus 5 vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-4o mini across capability, coding performance, speed, cost, lifecycle risk, and practical workload fit.
Read More
Claude Opus 5 vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-4o (Nov '24), covering capability evidence, speed, pricing, availability risk, and practical model-selection tradeoffs.
Read More
Claude Opus 5 vs GPT-5.5 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.5 across measured quality, coding, speed, cost, tooling, lifecycle status, and production tradeoffs.
Read More
Claude Opus 5 vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Sol (high), covering coding quality, speed, cost, operational risks, and practical model selection.
Read More
Claude Opus 5 vs GPT-5.6 Sol (xhigh): A Developer Selection Guide
A practical comparison of Claude Opus 5 and GPT-5.6 Sol across reasoning, coding, speed, pricing, deployment, and production risks.
Read More
Claude Opus 5 vs GPT-5.6 Sol: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Sol across capability, output speed, cost, APIs, reliability, and production fit.
Read More
Claude Opus 5 vs GPT-5.6 Terra: Which Reasoning Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Terra across quality, coding, speed, cost, reliability, and deployment fit.
Read More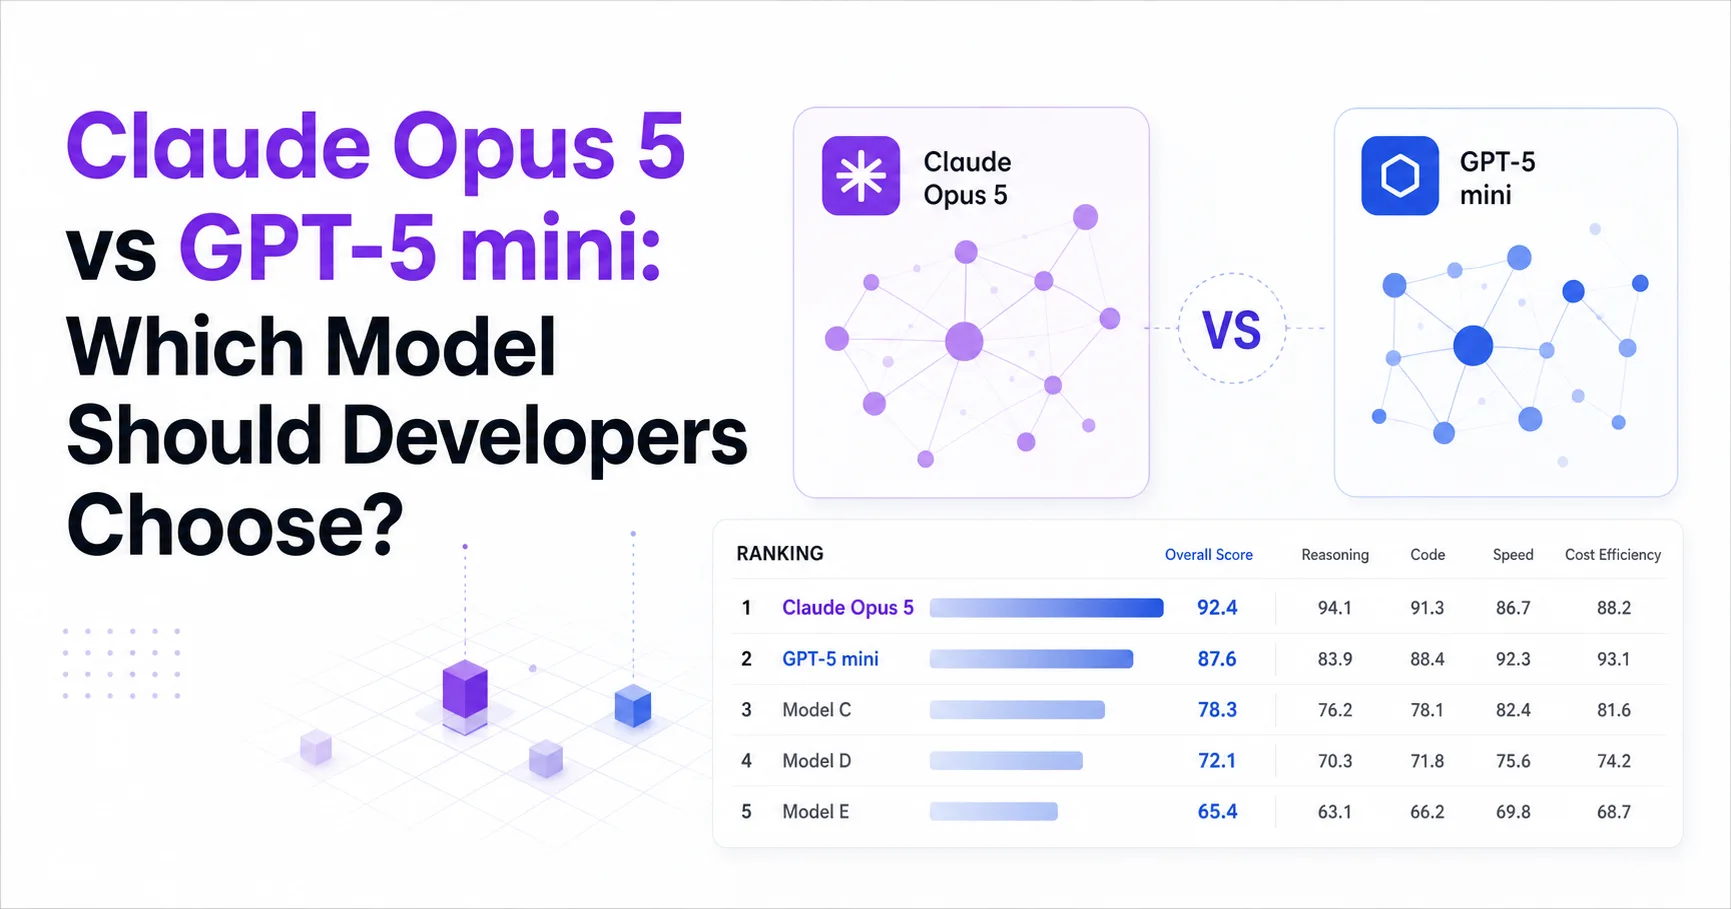
Claude Opus 5 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5 mini across coding, reasoning, speed, cost, availability, and production risk.
Read More
Claude Opus 5 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5 nano across capability evidence, speed, pricing, availability, and production risk.
Read More
Claude Opus 5 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5 across coding, reasoning, mathematics, speed, cost, tooling, lifecycle, and production risk.
Read More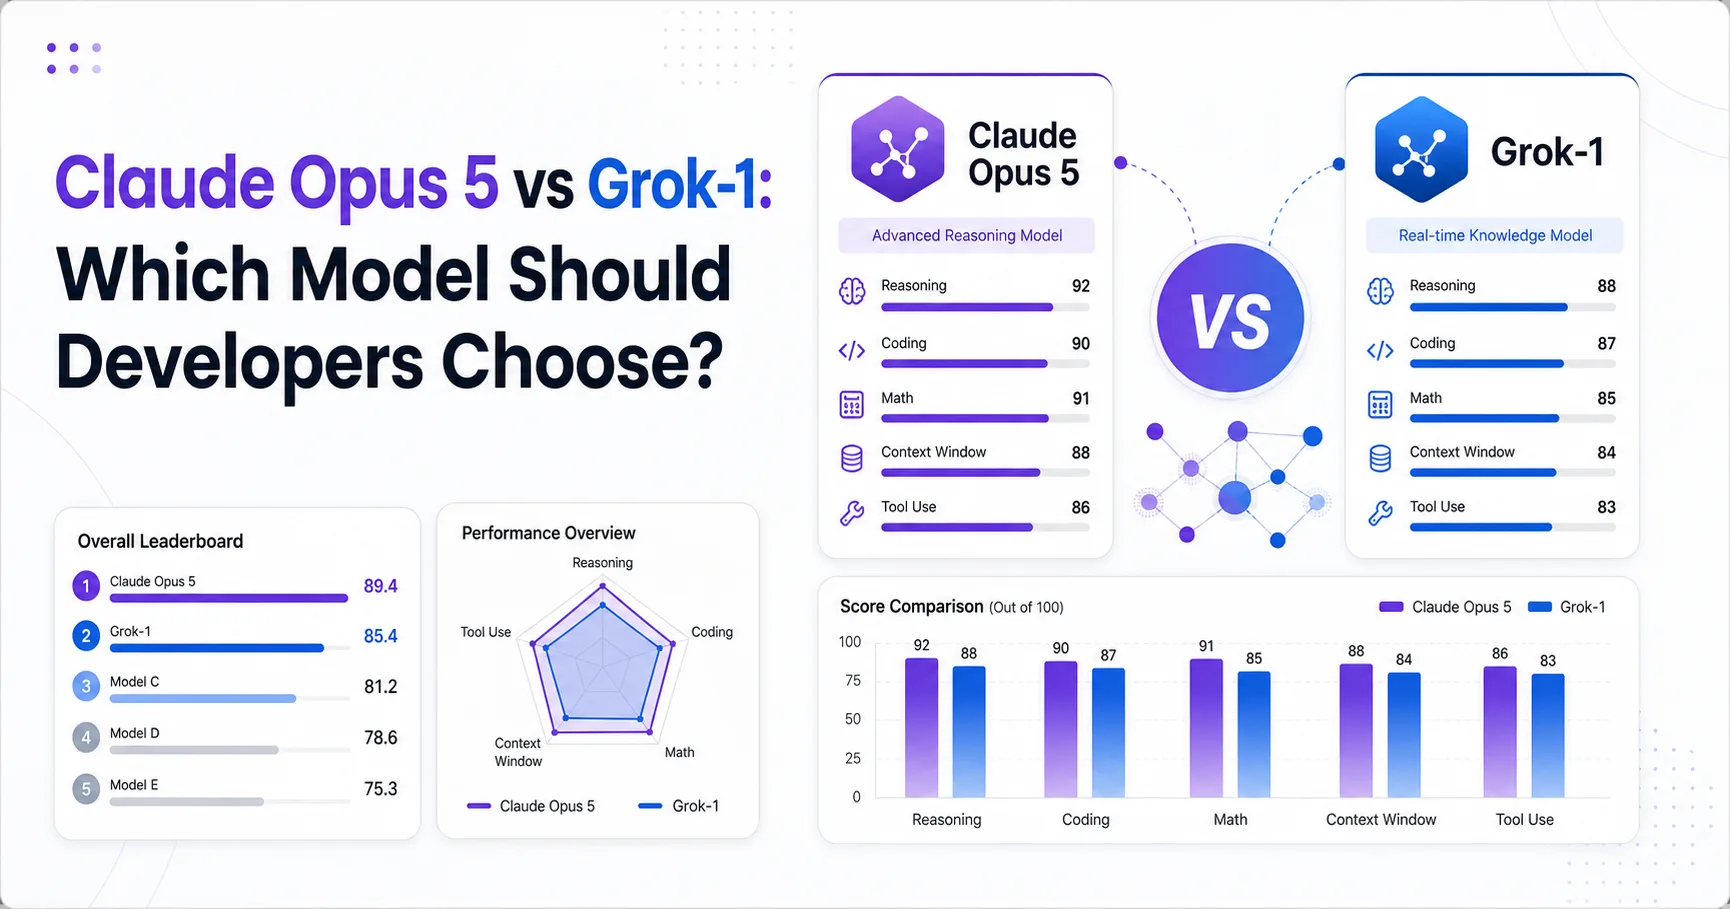
Claude Opus 5 vs Grok-1: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and Grok-1 across capability evidence, coding fit, speed, pricing, availability, and operational risk.
Read MoreClaude Opus 5 vs Kimi K3 for Developers: Quality, Speed, and Cost
A developer-focused comparison of Claude Opus 5 and Kimi K3 across coding quality, response speed, pricing, tooling, lifecycle, and production risks.
Read More
Claude Opus 5 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and o3 across capability evidence, speed, cost, availability, and production risk.
Read More
Claude Opus 5 Xhigh vs Gemini 1.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 at Xhigh effort and Gemini 1.5 Pro, covering capability, operational risk, speed, pricing, and model availability.
Read More
Claude Opus 5 Xhigh vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 with Xhigh effort and GPT-4, covering capability evidence, speed, pricing, reliability, and model-selection risks.
Read More
Claude Opus 5 Xhigh vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 at Xhigh effort and GPT-4o mini across coding, intelligence, speed, cost, API readiness, and operational risk.
Read More
Claude Opus 5 Xhigh vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Xhigh and GPT-4o (Nov '24), covering capability evidence, speed, pricing, lifecycle uncertainty, and practical model selection.
Read More
Claude Opus 5 vs GPT-5.5 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.5 across coding quality, intelligence, speed, API cost, tool support, lifecycle signals, and production fit.
Read More
Claude Opus 5 xhigh vs GPT-5.6 Sol high: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Sol across reasoning, coding, speed, cost, integration risk, and workflow fit.
Read More
Claude Opus 5 vs GPT-5.6 Sol: A Developer’s Model Selection Guide
A practical comparison of Claude Opus 5 and GPT-5.6 Sol for coding agents, reasoning workloads, latency-sensitive products, and API cost control.
Read More
Claude Opus 5 vs GPT-5.6 Sol for Developers: Speed, Cost, and Agentic Coding Trade-offs
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Sol across coding quality, reasoning, speed, pricing, API behavior, and production risk.
Read More
Claude Opus 5 (Xhigh Effort) vs GPT-5.6 Terra (Max)
A developer-focused comparison of Claude Opus 5 and GPT-5.6 Terra across coding quality, speed, cost, integration risk, and production fit.
Read More
Claude Opus 5 Xhigh vs GPT-5 mini High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Xhigh and GPT-5 mini High across coding quality, reasoning, speed, cost, availability, and integration risk.
Read More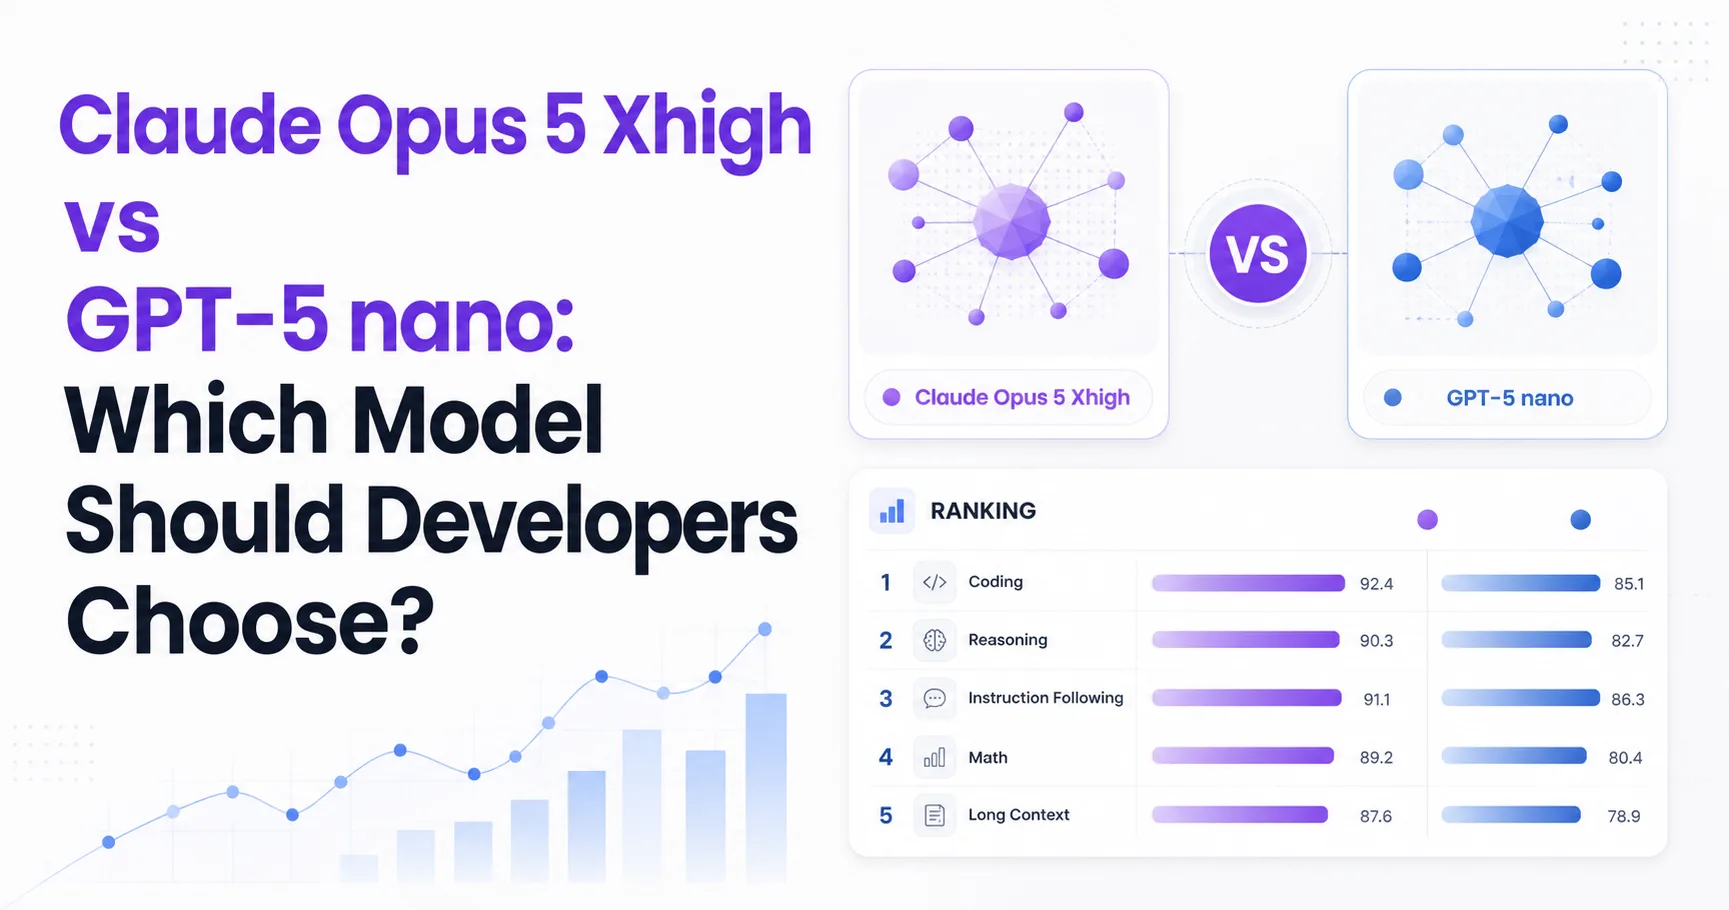
Claude Opus 5 Xhigh vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Xhigh and GPT-5 nano across capability, speed, cost, availability, and production risk.
Read More
Claude Opus 5 Xhigh vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 at xhigh effort and GPT-5 at high reasoning effort, covering capability, speed, cost, lifecycle risk, and practical fit.
Read More
Claude Opus 5 Xhigh vs Grok-1: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 and Grok-1 across capability evidence, speed, pricing, lifecycle certainty, and production risk.
Read More
Claude Opus 5 vs Kimi K3: A Developer’s Guide to Coding, Cost, and Agent Reliability
Claude Opus 5 leads the supplied intelligence, coding, and output-speed comparison, while Kimi K3 offers lower token prices and a different integration risk profile.
Read More
Claude Opus 5 Xhigh vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Opus 5 Xhigh and o3 across reasoning evidence, coding, speed, cost, API reliability, and model availability.
Read More
Claude Sonnet 4.6 Adaptive vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 Adaptive Reasoning, Max Effort and GPT-5 mini high across coding, intelligence, mathematics, latency, cost, and availability evidence.
Read More
Claude Sonnet 4.6 Adaptive vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 Adaptive and GPT-5 nano, covering measured quality, cost, availability evidence, and selection risks.
Read More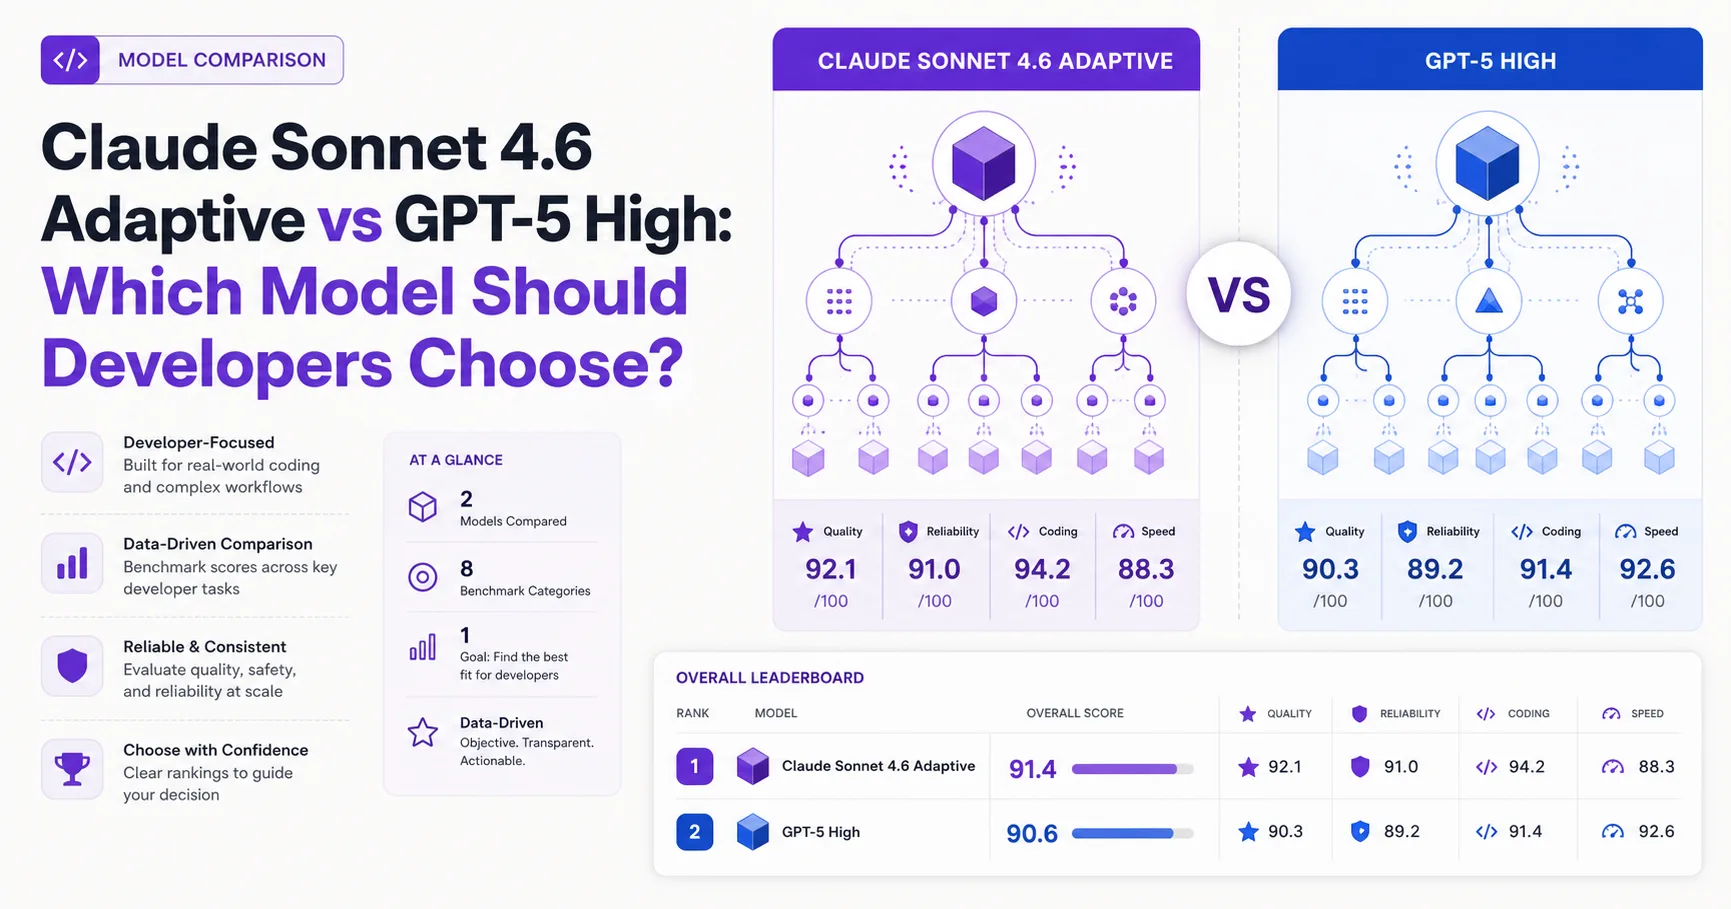
Claude Sonnet 4.6 Adaptive vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 Adaptive Reasoning Max Effort and GPT-5 high across coding quality, intelligence, math, latency, cost, API risk, and production fit.
Read More
Claude Sonnet 4.6 Adaptive vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 Adaptive Reasoning, Max Effort and o3 across measured quality, speed, cost, availability, and selection risk.
Read More
Claude Sonnet 4.6 Low Effort vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 Non-reasoning Low Effort and GPT-5 High across quality, coding evidence, speed, cost, API clarity, and production risk.
Read More
Claude Sonnet 4.6 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 Non-reasoning Low Effort and OpenAI o3 across intelligence, mathematics, speed, latency, pricing, and API certainty.
Read More
Claude Sonnet 4.6 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 and GPT-5 across capability signals, coding fit, latency, pricing, version stability, and practical selection criteria.
Read More
Claude Sonnet 4.6 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 4.6 and o3 across measured quality, mathematics, latency, cost, API availability, and selection risk.
Read More
Claude Sonnet 5 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and GPT-5 mini across coding quality, intelligence, mathematics, speed, pricing, API availability, and model-selection risk.
Read More
Claude Sonnet 5 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and GPT-5 across coding quality, general intelligence, speed, pricing, API behavior, and version risk.
Read More
Claude Sonnet 5 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and o3 across intelligence, coding evidence, speed, cost, availability, and production risk.
Read More
Claude Sonnet 5 vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and GPT-4o (Nov '24), covering measured intelligence, speed, pricing, API certainty, and evidence gaps.
Read More
Claude Sonnet 5 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and GPT-5 mini across coding, reasoning, speed, price, availability, and integration risk.
Read More
Claude Sonnet 5 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and GPT-5 nano covering capability, speed, cost, availability, integration risk, and practical model-selection criteria.
Read More
Claude Sonnet 5 vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of Claude Sonnet 5 and GPT-5 across coding, reasoning, cost, integration constraints, model status, and practical workload fit.
Read More
Cogito v2.1 (Reasoning) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of Cogito v2.1 (Reasoning) and GPT-5 nano (high), covering benchmark trade-offs, pricing, availability uncertainty, and practical model selection.
Read More
Cogito v2.1 (Reasoning) vs Grok-1: Which Model Should Developers Choose?
A practical comparison of Cogito v2.1 (Reasoning) and Grok-1 for developers, covering benchmark evidence, pricing uncertainty, availability, and production risk.
Read More
DeepSeek V4 Flash High vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash High and GPT-5 High across coding, reasoning, pricing, API capabilities, version stability, and production risk.
Read More
DeepSeek V4 Flash vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash (Reasoning, Max Effort) and GPT-5 mini (high), covering benchmark evidence, cost, availability, latency, and selection risk.
Read More
DeepSeek V4 Flash vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash and GPT-5 across coding, reasoning, pricing, API fit, version stability, and practical risk.
Read More
DeepSeek V4 Flash vs o3: Which Model Should Developers Choose?
A practical comparison of DeepSeek V4 Flash and o3 for developers choosing between cost, measured intelligence, speed, API availability, and production risk.
Read More
DeepSeek V4 Flash Non-reasoning vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash Non-reasoning and GPT-5 (high), covering capability evidence, speed, pricing, API constraints, version risk, and practical model selection.
Read More
DeepSeek V4 Flash 0731 vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash 0731 and GPT-5 mini (high), covering coding, reasoning, mathematics, speed, pricing, API certainty, and selection risk.
Read More
DeepSeek V4 Flash 0731 vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash 0731 and GPT-5 nano across capability evidence, speed, pricing, API availability, and production risk.
Read More
DeepSeek V4 Flash 0731 vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash 0731 and GPT-5 (high), covering coding quality, reasoning, mathematics, latency, pricing, API constraints, and deployment risk.
Read More
DeepSeek V4 Flash 0731 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Flash 0731 and o3 across measured intelligence, mathematics, speed, cost, API evidence, and operational risk.
Read More
DeepSeek V4 Pro 0424 High vs GPT-5.5 xhigh: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0424 High and GPT-5.5 xhigh across capability, coding, latency, pricing, reliability, and deployment risk.
Read More
DeepSeek V4 Pro High Effort vs GPT-5.6 Sol Max: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro (Reasoning, High Effort) and GPT-5.6 Sol (max), covering measured capability, latency, cost, API certainty, and operational risk.
Read More
DeepSeek V4 Pro (Reasoning, High Effort) vs GPT-5.6 Terra (max): Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0424 High and GPT-5.6 Terra across measured quality, coding, speed, latency, pricing, API evidence, and version risk.
Read More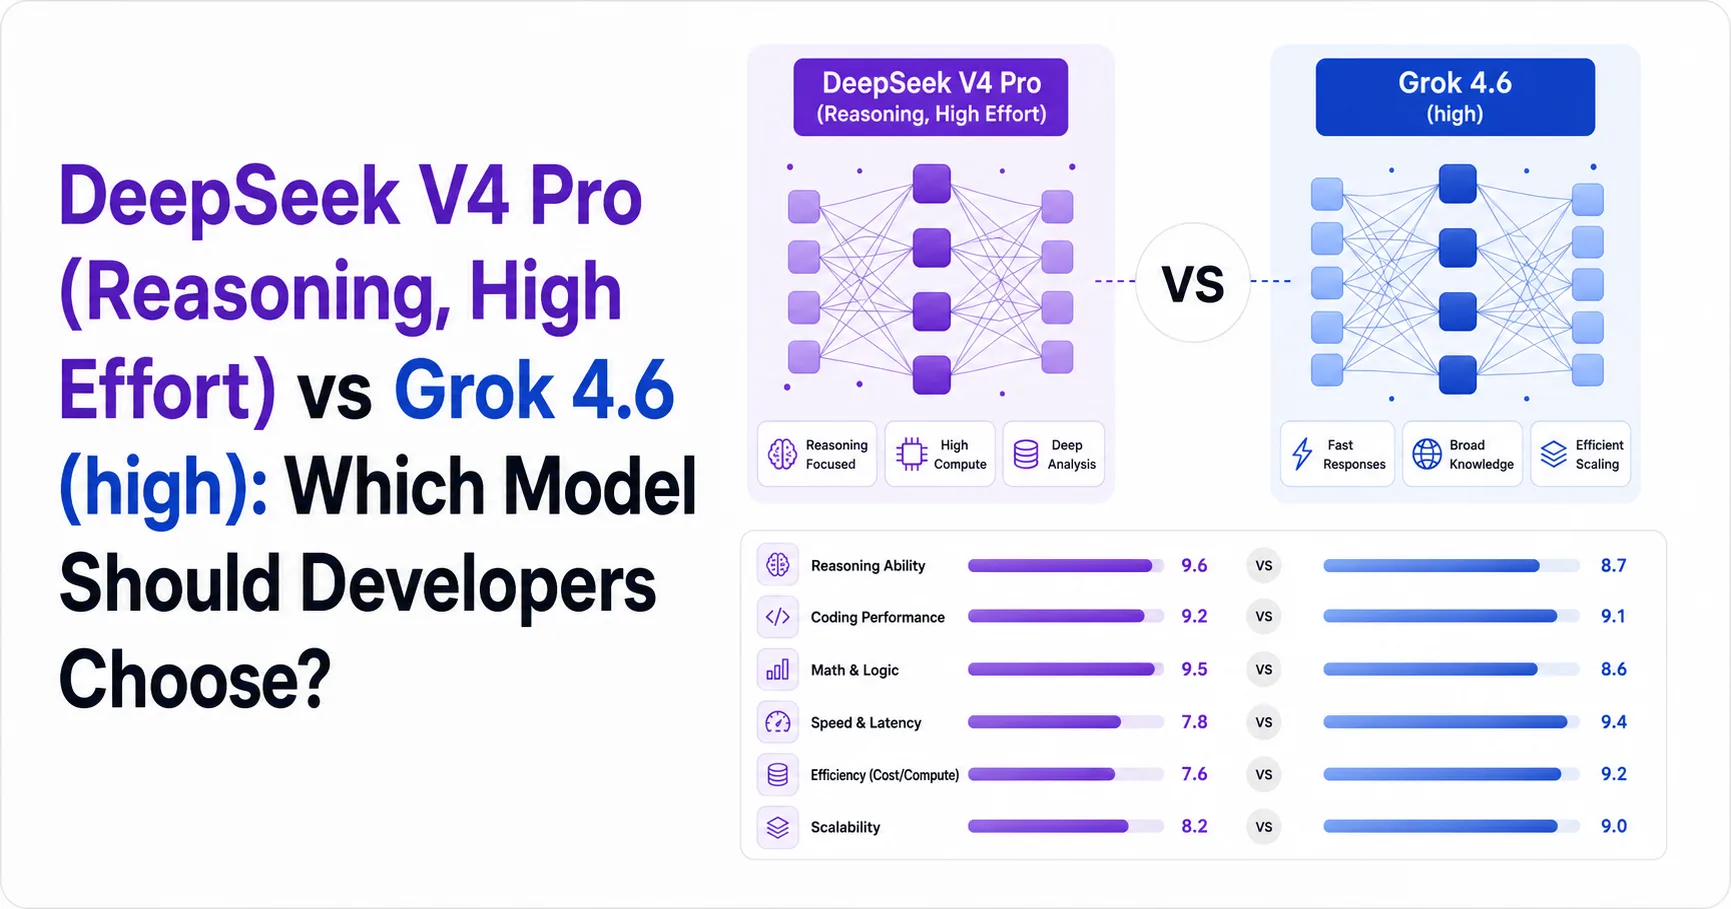
DeepSeek V4 Pro (Reasoning, High Effort) vs Grok 4.6 (high): Which Model Should Developers Choose?
Grok 4.6 leads on measured coding capability, while DeepSeek V4 Pro offers lower token pricing and lower latency. Choose based on task risk, budget, and version certainty.
Read More
DeepSeek V4 Pro (Reasoning, High Effort) vs Kimi K3 (max)
A developer-focused comparison of Kimi K3 (max) and DeepSeek V4 Pro (Reasoning, High Effort), covering measured quality, speed, price, API evidence, and selection risks.
Read More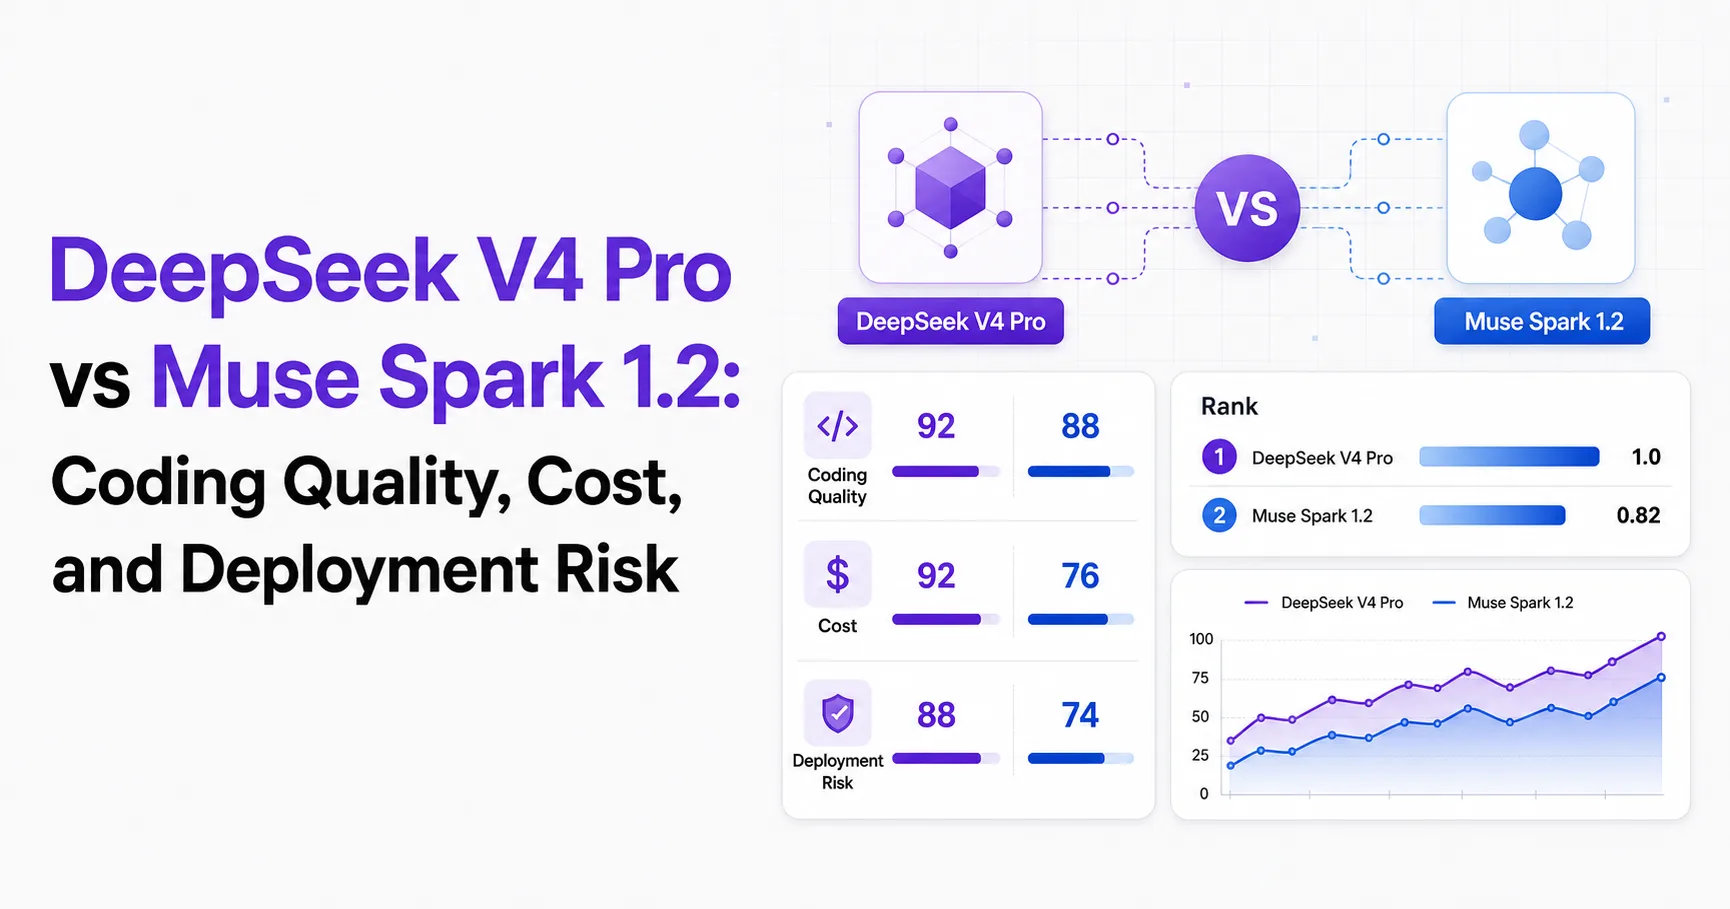
DeepSeek V4 Pro vs Muse Spark 1.2: Coding Quality, Cost, and Deployment Risk
A developer-focused comparison of DeepSeek V4 Pro (Reasoning, High Effort) and Muse Spark 1.2 (xhigh), covering benchmark strength, pricing, speed evidence, and documentation risk.
Read More
DeepSeek V4 Pro (Reasoning, High Effort) vs Qwen3.8 Max: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0424 High and Qwen3.8 Max across benchmark results, speed, latency, pricing, API availability, and evidence quality.
Read More
DeepSeek V4 Pro (Non-reasoning) vs GPT-5.5 (xhigh)
A developer-focused comparison of DeepSeek V4 Pro (Non-reasoning) and GPT-5.5 (xhigh), covering capability evidence, API certainty, cost, speed data, and deployment risks.
Read More
DeepSeek V4 Pro (Non-reasoning) vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
GPT-5.6 Sol (max) offers stronger measured reasoning and coding performance, while DeepSeek V4 Pro (Non-reasoning) offers much lower token costs and far lower measured latency, with important version-availability uncertainty.
Read More
DeepSeek V4 Pro (Non-reasoning) vs GPT-5.6 Terra (max)
GPT-5.6 Terra (max) leads measured reasoning and coding-oriented evaluations, while DeepSeek V4 Pro (Non-reasoning) offers much lower listed token costs and far lower measured latency.
Read More
DeepSeek V4 Pro (Non-reasoning) vs Grok 4.6 (high): Which Model Should Developers Choose?
Grok 4.6 (high) leads on measured capability, while DeepSeek V4 Pro (Non-reasoning) is far cheaper and has much lower latency.
Read More
DeepSeek V4 Pro (Non-reasoning) vs Kimi K3 (max): Speed, Cost, and Model Selection
Kimi K3 (max) leads on comparable intelligence evaluations, while DeepSeek V4 Pro (Non-reasoning) is faster and far cheaper. Version and API evidence remains incomplete.
Read More
DeepSeek V4 Pro (Non-reasoning) vs Muse Spark 1.2 (xhigh)
A developer-focused comparison of measured capability, cost, speed, and deployment uncertainty for DeepSeek V4 Pro (Non-reasoning) and Muse Spark 1.2 (xhigh).
Read More
DeepSeek V4 Pro (Non-reasoning) vs Qwen3.8 Max
Qwen3.8 Max leads measured quality, while DeepSeek V4 Pro (Non-reasoning) is faster, cheaper, and easier to justify only after version availability is verified.
Read More
DeepSeek V4 Pro High vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro (Reasoning, High Effort) and GPT-5 mini (high), covering coding, reasoning, mathematics, API certainty, speed, and cost.
Read More
DeepSeek V4 Pro High vs GPT-5 nano High: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro (Reasoning, High Effort) and GPT-5 nano (high), covering reasoning quality, coding evidence, speed, cost, API availability, and selection risks.
Read More
DeepSeek V4 Pro High vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro High and GPT-5 High across coding, reasoning, mathematics, speed, pricing, API maturity, and migration risk.
Read More
DeepSeek V4 Pro High vs o3: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro High and o3 across intelligence, coding evidence, speed, cost, API availability, and selection risk.
Read More
DeepSeek V4 Pro Non-Reasoning vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro Non-reasoning and GPT-5 high across capability, speed, cost, API fit, and deployment risk.
Read More
DeepSeek V4 Pro 0813 vs GPT-5.5 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0813 and GPT-5.5 (xhigh), covering measured quality, cost, speed evidence, API capabilities, and deployment risks.
Read More
DeepSeek V4 Pro 0813 vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0813 and GPT-5.6 Sol (max), covering coding capability, latency, cost, tools, long-context limits, and evidence gaps.
Read More
DeepSeek V4 Pro vs GPT-5.6 Terra: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0813 and GPT-5.6 Terra across coding quality, reasoning, speed, latency, cost, tools, and operational risk.
Read More
DeepSeek V4 Pro vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro and GPT-5 mini across coding quality, reasoning, speed, pricing, API availability, and selection risk.
Read More
DeepSeek V4 Pro vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro and GPT-5 nano across measured intelligence, math, speed, latency, price, API availability, and evidence quality.
Read More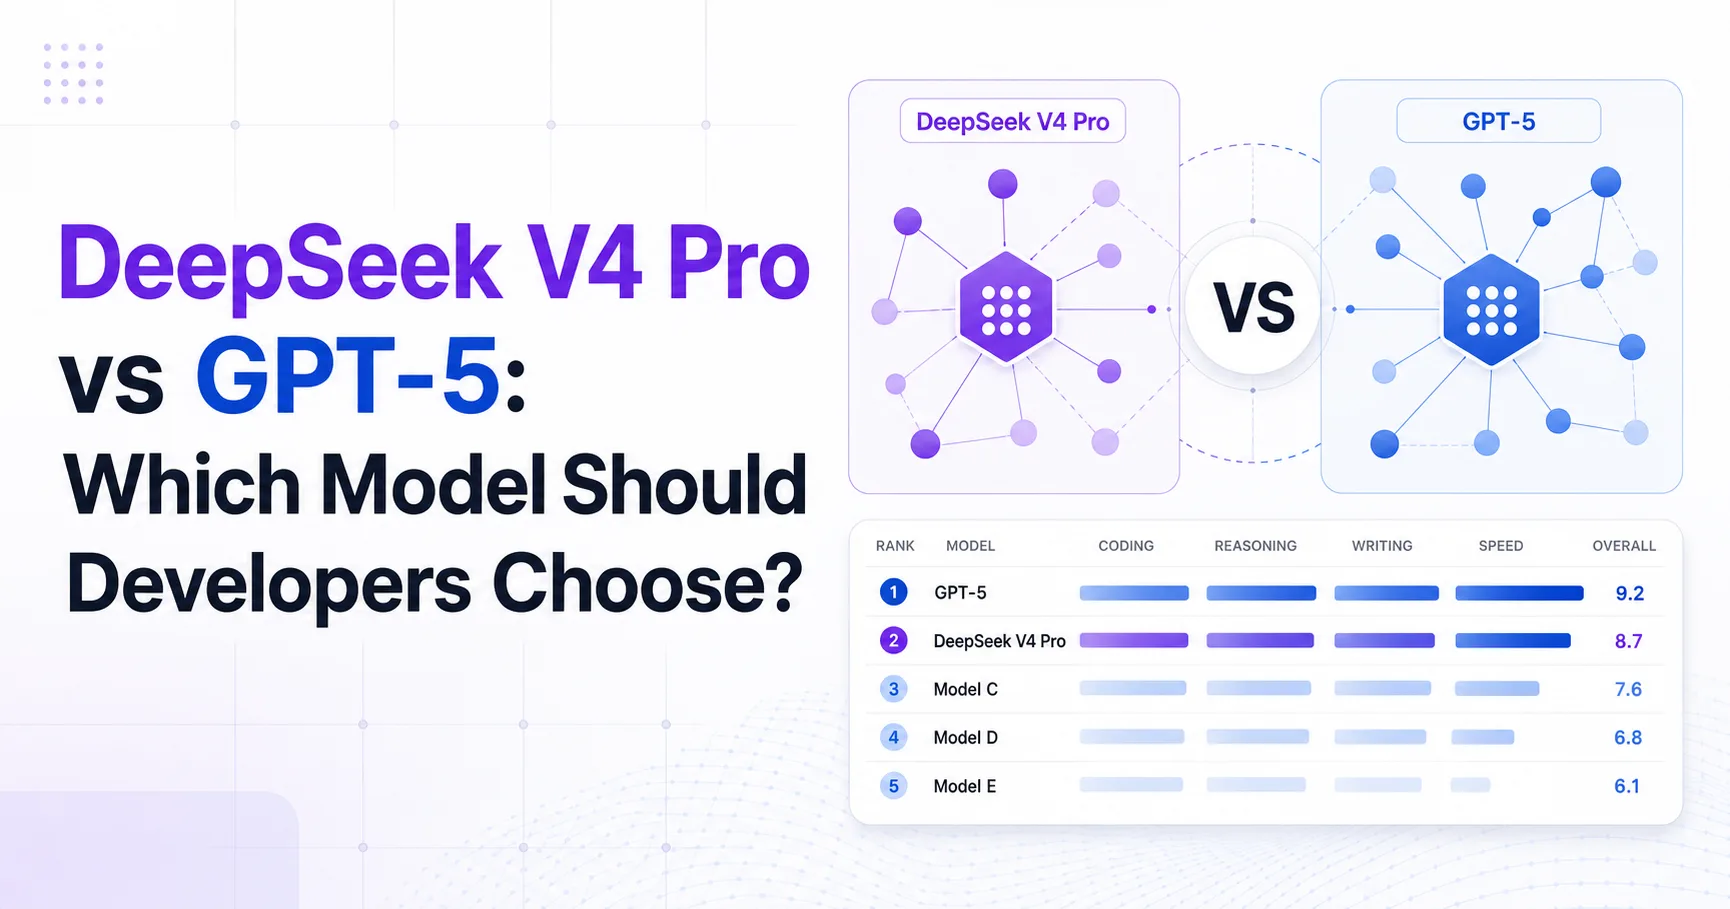
DeepSeek V4 Pro vs GPT-5: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro and GPT-5 across coding quality, reasoning, speed, pricing, API compatibility, and operational risk.
Read More
DeepSeek V4 Pro 0813 vs Grok 4.6 (high): Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0813 and Grok 4.6 (high), covering measured capability, latency, pricing, API fit, and unresolved deployment risks.
Read More
DeepSeek V4 Pro vs Kimi K3: Speed, Cost, and Capability Trade-offs
DeepSeek V4 Pro is the practical default for cost-sensitive production workloads, while Kimi K3 leads the available quality benchmarks for teams that can accept higher cost and slower responses.
Read More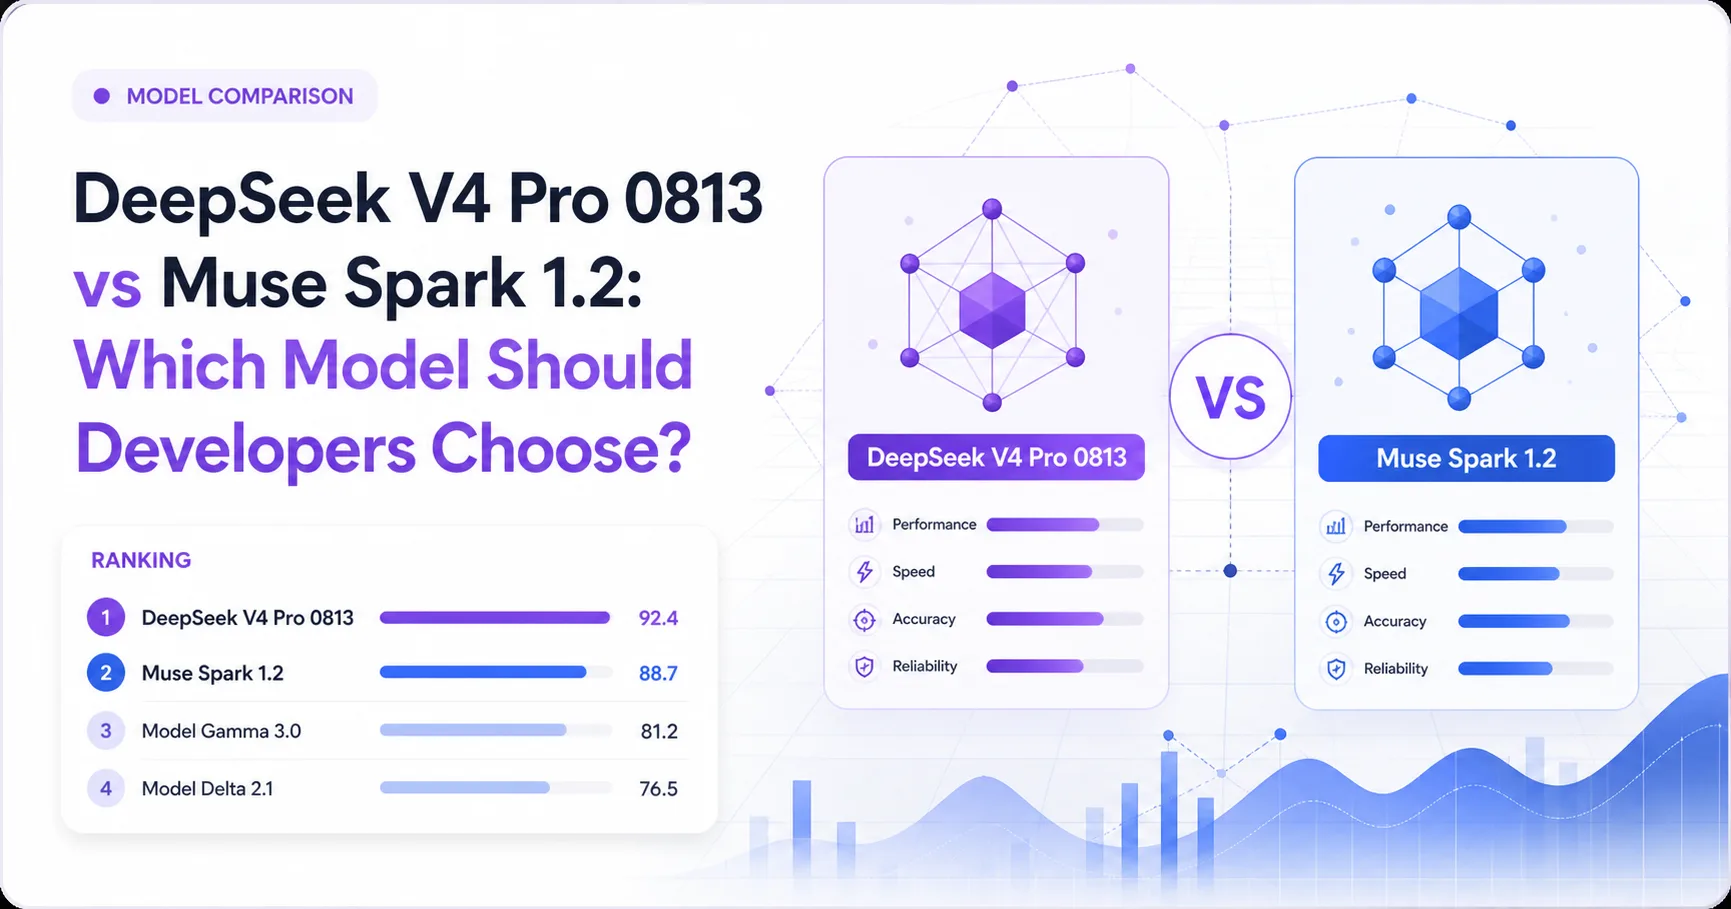
DeepSeek V4 Pro 0813 vs Muse Spark 1.2: Which Model Should Developers Choose?
DeepSeek V4 Pro 0813 offers a documented API, lower listed token prices, and measured output speed. Muse Spark 1.2 leads several benchmark results, but its official availability remains unverified.
Read More
DeepSeek V4 Pro vs o3: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro and o3 across measured quality, speed, cost, API availability, and selection risk.
Read More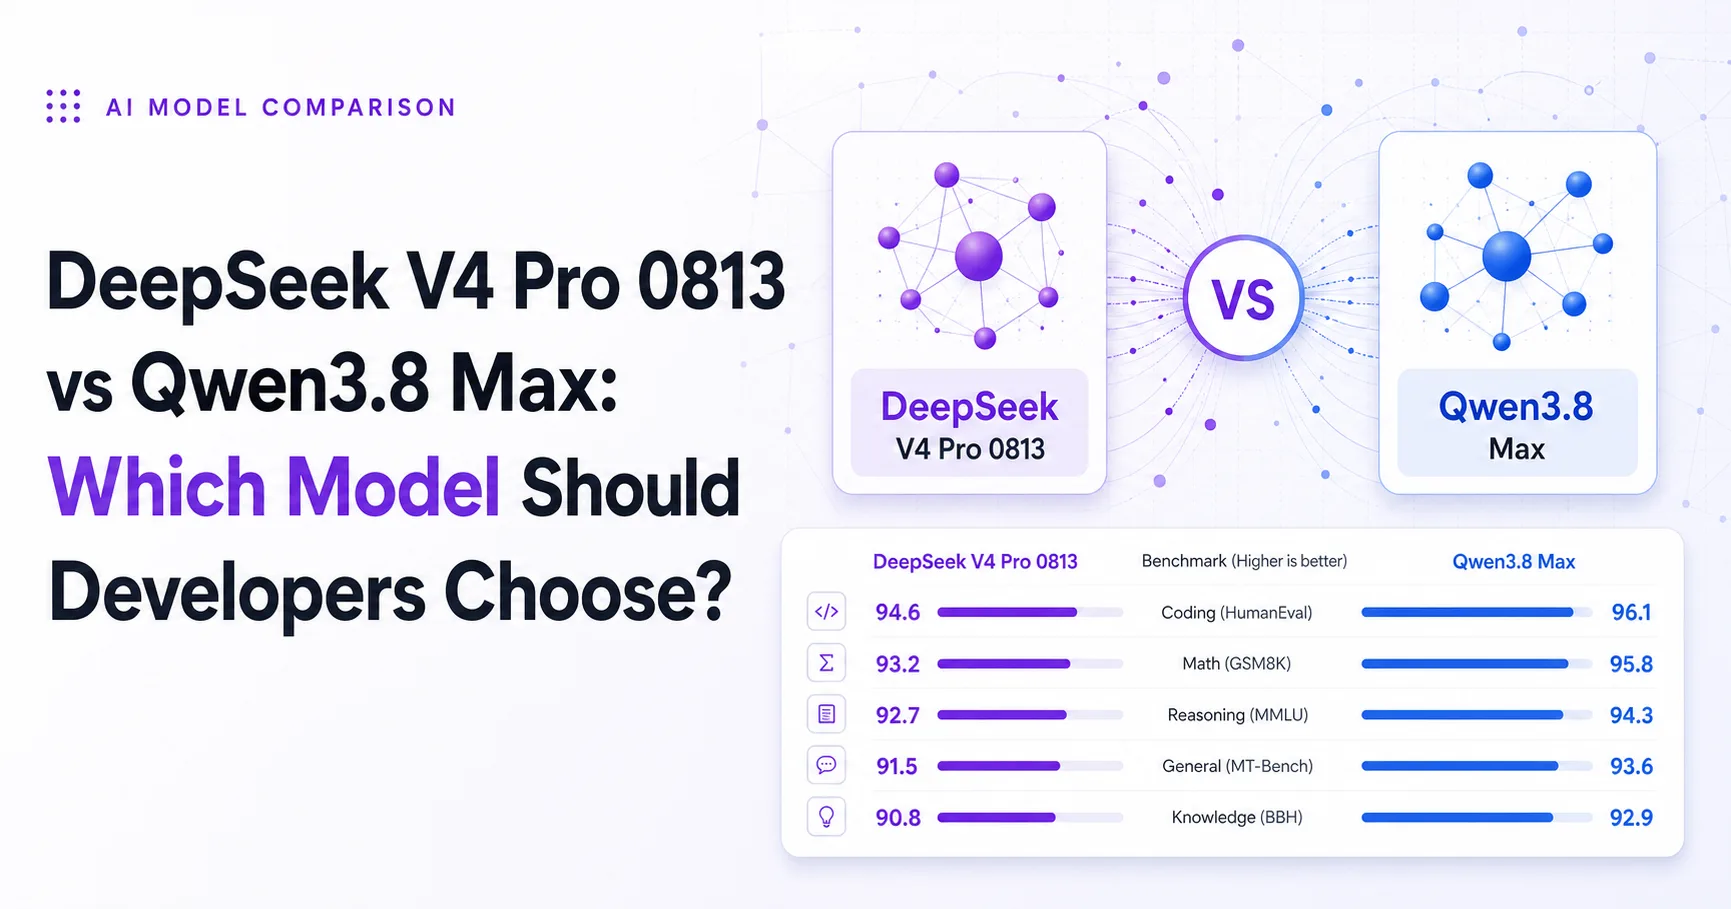
DeepSeek V4 Pro 0813 vs Qwen3.8 Max: Which Model Should Developers Choose?
A developer-focused comparison of DeepSeek V4 Pro 0813 and Qwen3.8 Max across benchmark results, speed, pricing, API readiness, and deployment risk.
Read More
EXAONE 4.5 33B vs Gemini 1.5 Pro: A Practical Model Selection Guide
A developer-focused comparison of EXAONE 4.5 33B Non-reasoning and Gemini 1.5 Pro, covering evidence quality, performance, cost, availability, and deployment risk.
Read More
EXAONE 4.5 33B (Non-reasoning) vs GPT-4: Which Model Should Developers Choose?
A practical comparison of EXAONE 4.5 33B (Non-reasoning) and GPT-4, focused on documented capability, cost visibility, performance evidence, and deployment risk.
Read More
EXAONE 4.5 33B (Non-reasoning) vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of EXAONE 4.5 33B (Non-reasoning) and GPT-4o mini, covering evidence quality, benchmark visibility, pricing uncertainty, and deployment risk.
Read More
EXAONE 4.5 33B vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of EXAONE 4.5 33B (Non-reasoning) and GPT-4o (Nov '24), covering evidence quality, performance, cost, availability, and selection risk.
Read More
EXAONE 4.5 33B vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of EXAONE 4.5 33B (Non-reasoning) and GPT-5 mini (high), covering evidence quality, benchmark visibility, pricing, availability, and selection risk.
Read More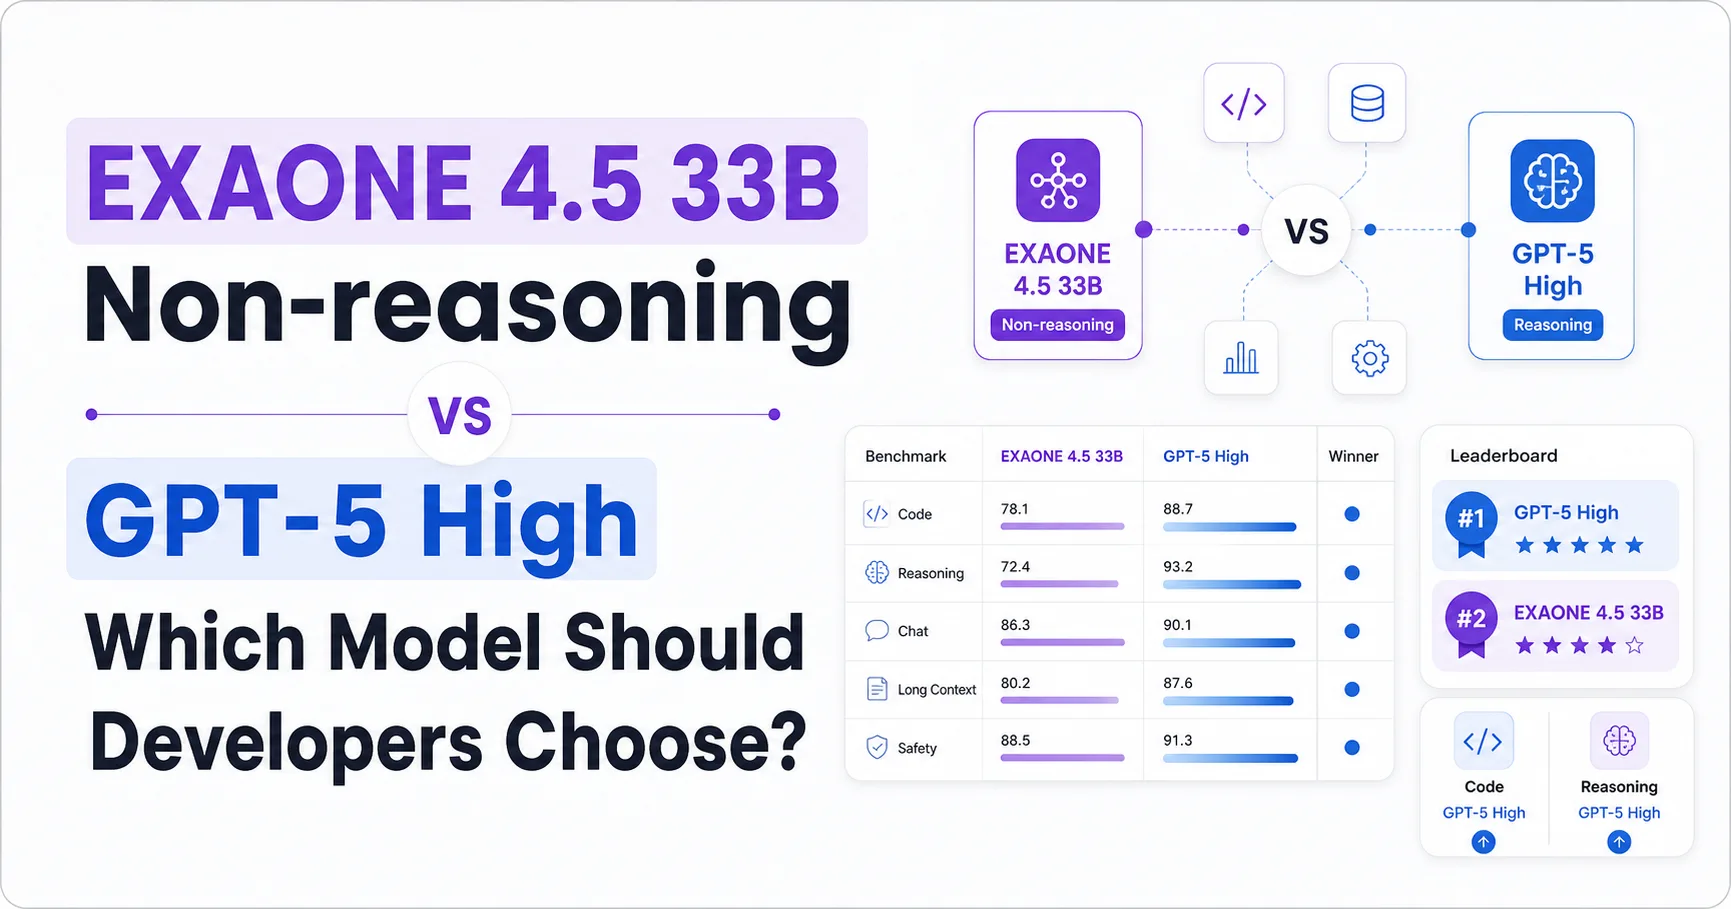
EXAONE 4.5 33B Non-reasoning vs GPT-5 High: Which Model Should Developers Choose?
A developer-focused comparison of EXAONE 4.5 33B Non-reasoning and GPT-5 High, covering evidence quality, coding, reasoning, API readiness, pricing, migration risk, and practical model selection.
Read More
Gemini 1.5 Pro vs Gemini 3 Deep Think: A Developer Selection Guide
A cautious comparison of Gemini 1.5 Pro (Sep '24) and Gemini 3 Deep Think for developers, focused on evidence, availability, performance, cost, and deployment risk.
Read More
Gemini 1.5 Pro (Sep '24) vs GPT-5.4 Pro (xhigh): Which Should Developers Choose?
A careful developer comparison of Gemini 1.5 Pro (Sep '24) and GPT-5.4 Pro (xhigh), covering measured capability, cost visibility, availability risk, and production selection criteria.
Read More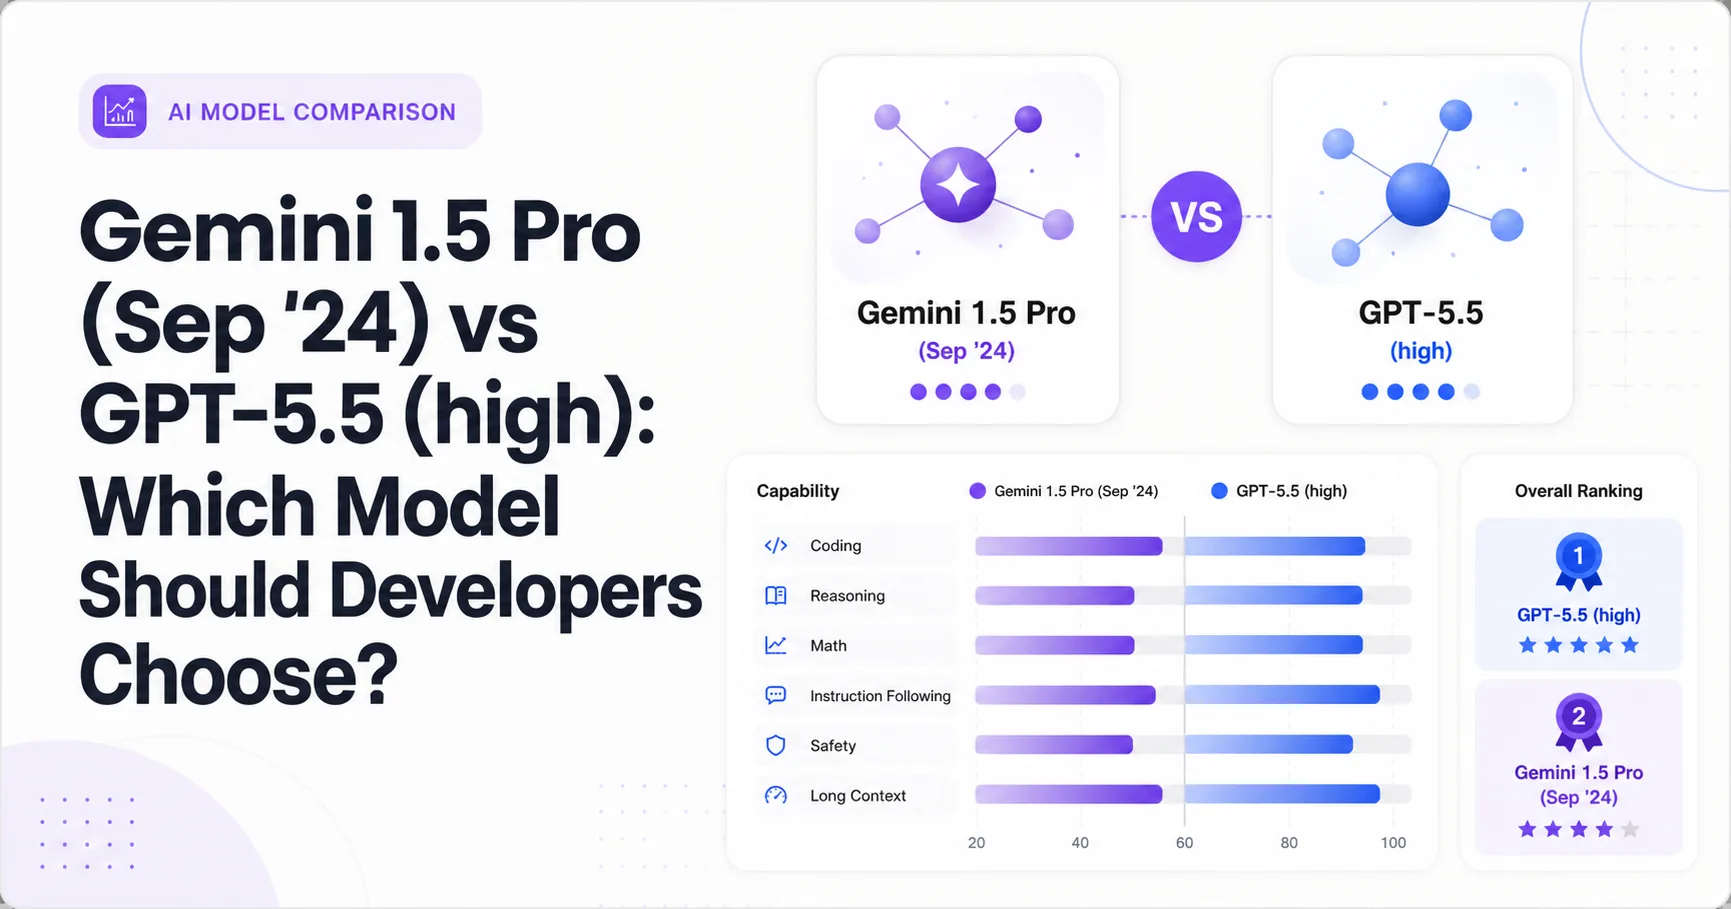
Gemini 1.5 Pro (Sep '24) vs GPT-5.5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro (Sep '24) and GPT-5.5 (high), covering capability, cost, availability, reliability evidence, and practical model-selection risks.
Read More
Gemini 1.5 Pro (Sep '24) vs GPT-5.5 Pro (xhigh): Which Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro (Sep '24) and GPT-5.5 Pro (xhigh), focused on evidence quality, availability, performance, cost, and deployment risk.
Read More
Gemini 1.5 Pro vs GPT-5.5: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro (Sep '24) and GPT-5.5 (xhigh), covering capability, reliability, pricing, performance, and production risk.
Read More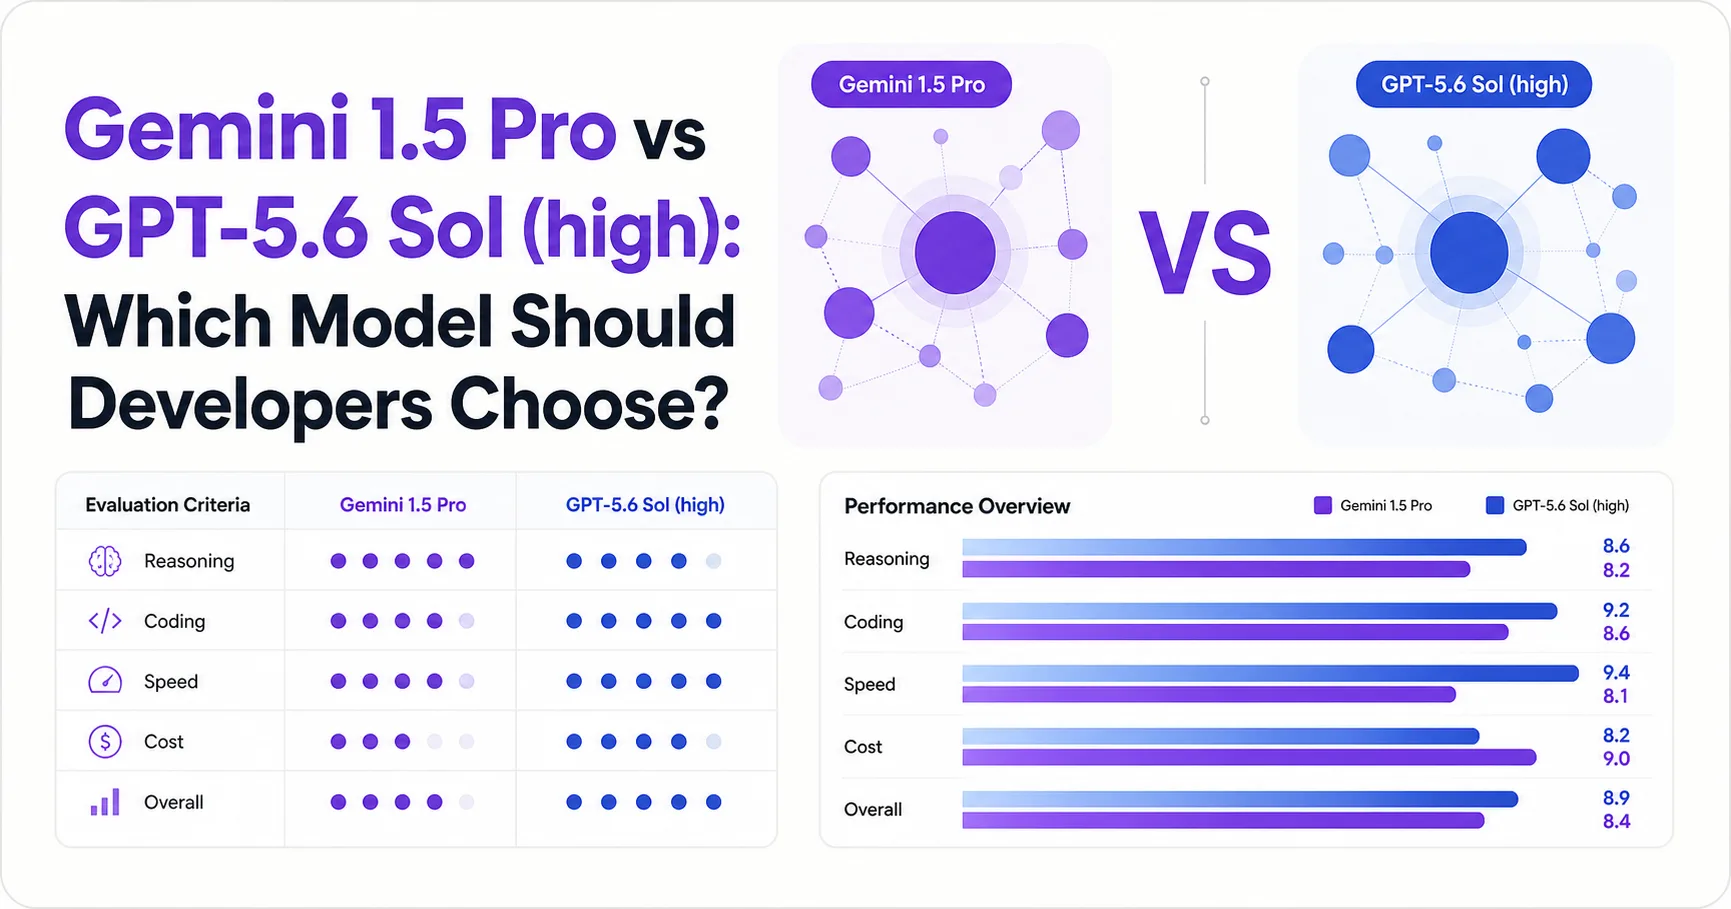
Gemini 1.5 Pro vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro and GPT-5.6 Sol (high), covering capability, operational availability, pricing, speed, evidence quality, and migration risk.
Read More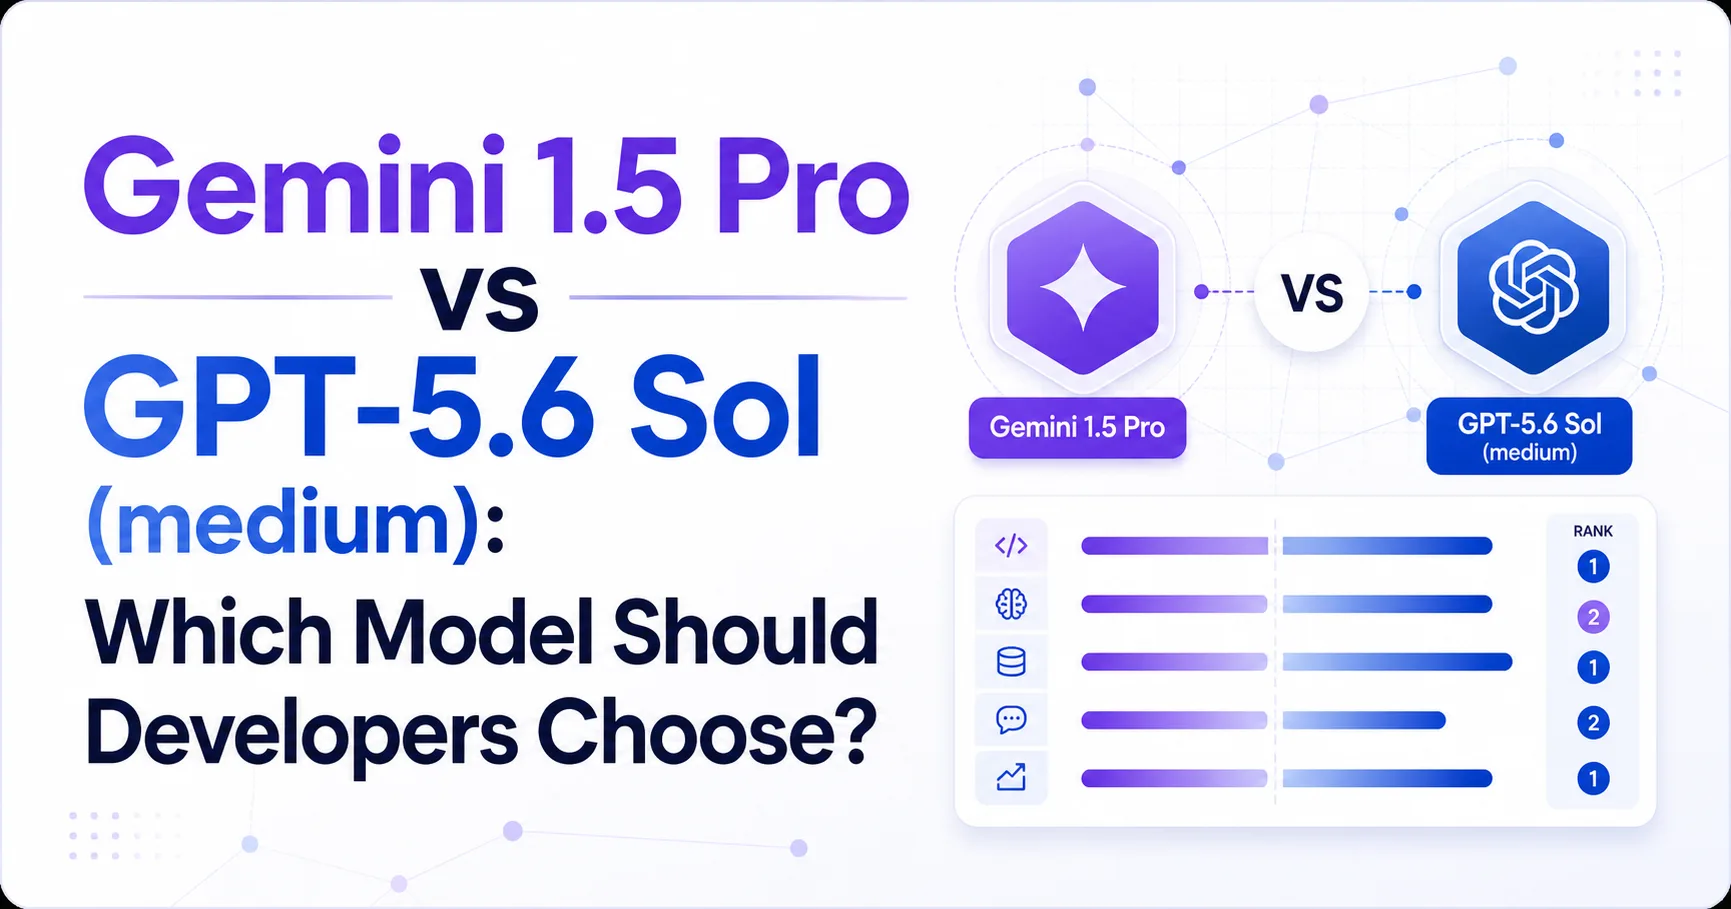
Gemini 1.5 Pro vs GPT-5.6 Sol (medium): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro (Sep '24) and GPT-5.6 Sol (medium), covering capability, coding performance, cost, availability, operational risk, and model selection.
Read More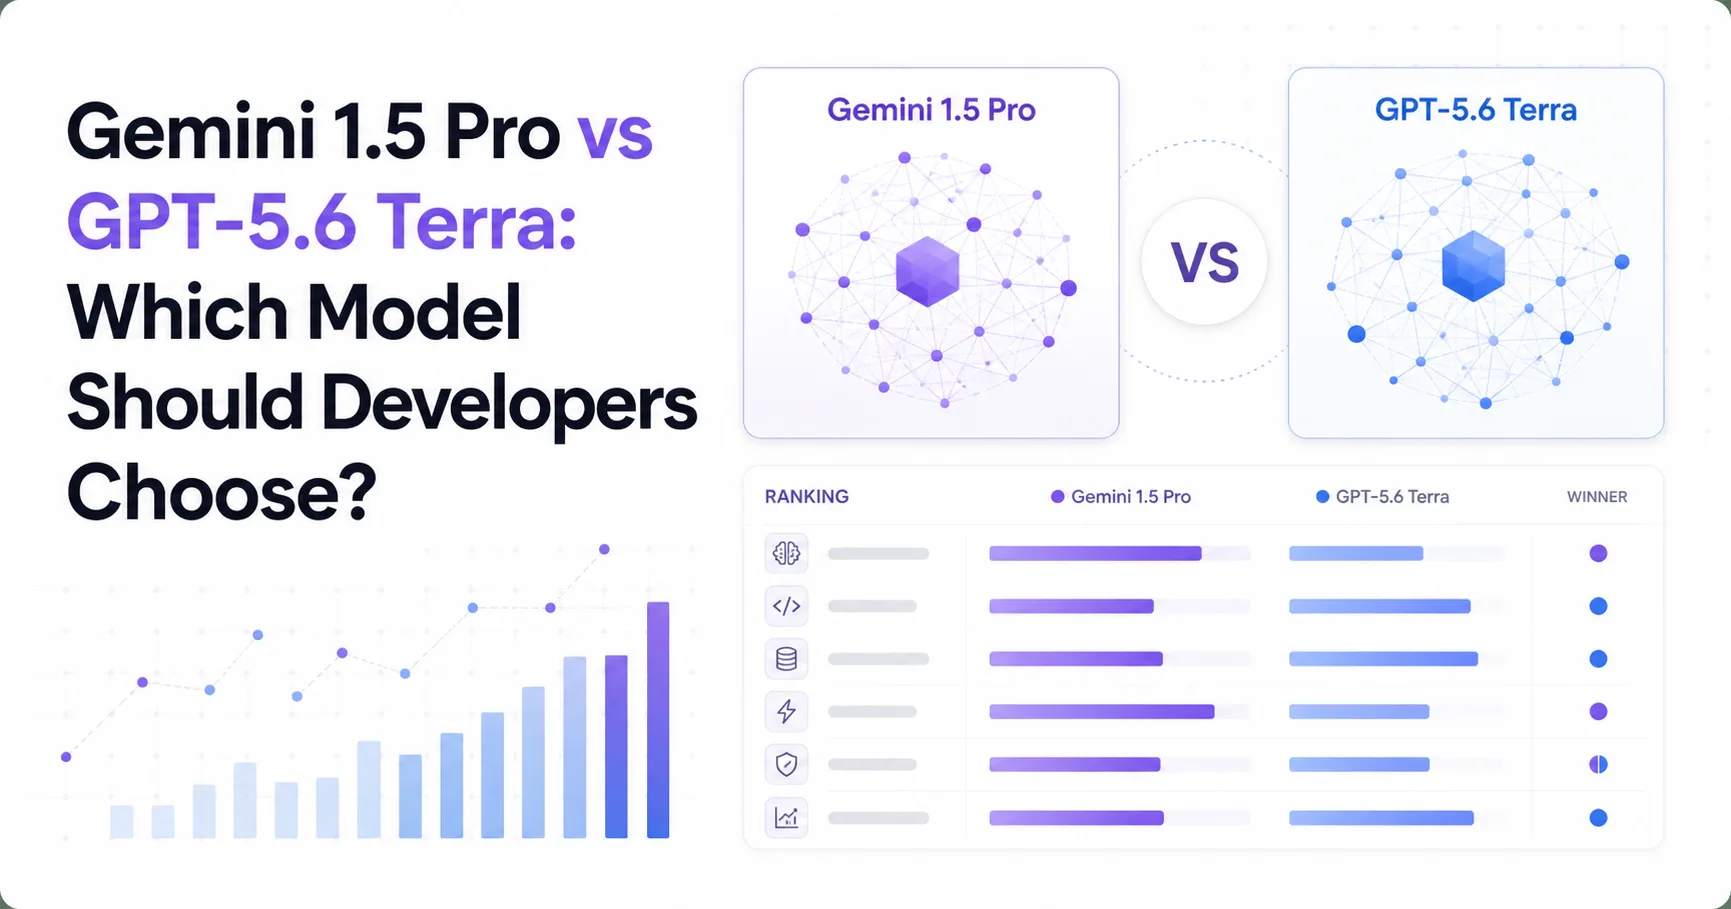
Gemini 1.5 Pro vs GPT-5.6 Terra: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro (Sep '24) and GPT-5.6 Terra (max), covering capability evidence, operational risk, pricing, speed, and model selection.
Read More
Gemini 1.5 Pro (Sep '24) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of Kimi K3 (max) and Gemini 1.5 Pro (Sep '24), covering capability, operational status, pricing, integration risk, and practical model selection.
Read More
Gemini 1.5 Pro vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 1.5 Pro (Sep '24) and Mi:dm K 2.5 Pro Preview, covering benchmark evidence, availability, pricing, and selection risk.
Read More
Gemini 3.1 Pro Preview vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.1 Pro Preview and GPT-5 mini (high), covering capability signals, speed, cost, availability risk, and practical model selection.
Read More
Gemini 3.1 Pro Preview vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.1 Pro Preview and GPT-5 nano (high), covering measured intelligence, coding evidence, speed, pricing, availability, and uncertainty.
Read More
Gemini 3.1 Pro Preview vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.1 Pro Preview and GPT-5 (high), covering capability signals, speed, pricing, API maturity, and practical selection criteria.
Read More
Gemini 3.1 Pro Preview vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.1 Pro Preview and o3 across measured intelligence, coding evidence, speed, cost, availability, and deployment risk.
Read More
Gemini 3.5 Flash-Lite vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash-Lite and GPT-5 (high), covering coding quality, reasoning, speed, pricing, modality, version status, and evidence limits.
Read More
Gemini 3.5 Flash-Lite vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash-Lite and o3 across measured quality, speed, cost, availability, and selection risk.
Read More
Gemini 3.5 Flash (medium) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (medium) and GPT-5 mini (high), covering evidence quality, speed, cost, model availability, and production risk.
Read More
Gemini 3.5 Flash (medium) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (medium) and GPT-5 nano (high), covering intelligence, speed, cost, availability, evidence gaps, and practical selection criteria.
Read More
Gemini 3.5 Flash (medium) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (medium) and GPT-5 (high), covering capability signals, speed, pricing, API certainty, and production risks.
Read More
Gemini 3.5 Flash (medium) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (medium) and o3 across intelligence, mathematics, speed, pricing, availability, and production risk.
Read More
Gemini 3.5 Flash (minimal) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (minimal) and GPT-5 (high), covering evidence quality, speed, pricing, coding fit, and API risk.
Read More
Gemini 3.5 Flash (minimal) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (minimal) and o3 across intelligence, mathematics, speed, latency, cost, and API availability.
Read More
Gemini 3.5 Flash (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (high) and GPT-5 mini (high), covering coding quality, reasoning, speed, cost, availability, and deployment risk.
Read More
Gemini 3.5 Flash (high) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (high) and GPT-5 nano (high), covering capability evidence, speed, cost, availability, and production risk.
Read More
Gemini 3.5 Flash (high) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (high) and GPT-5 (high), covering coding, reasoning, latency, pricing, API maturity, and production risks.
Read More
Gemini 3.5 Flash (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.5 Flash (high) and o3 across capability evidence, coding, speed, cost, availability, and production risk.
Read More
Gemini 3.6 Flash (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.6 Flash (high) and GPT-5 mini (high), covering measured capability, speed, pricing, evidence quality, and deployment risk.
Read More
Gemini 3.6 Flash (high) vs GPT-5 nano (high): Which Model Should Developers Choose?
Gemini 3.6 Flash (high) offers the stronger measured intelligence profile and documented agent features, while GPT-5 nano (high) is far cheaper in the supplied comparison data. Data provided by https://artificialanalysis.ai/
Read More
Gemini 3.6 Flash (high) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.6 Flash (high) and GPT-5 (high), covering coding, reasoning, latency, pricing, API constraints, version risk, and practical fit.
Read More
Gemini 3.6 Flash (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3.6 Flash (high) and o3 across intelligence, coding evidence, speed, pricing, availability, and practical risk.
Read More
Gemini 3 Deep Think vs GPT-4: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Deep Think and GPT-4, covering availability, evidence quality, benchmark data, pricing, and practical selection risk.
Read More
Gemini 3 Deep Think vs GPT-4o mini: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Deep Think and GPT-4o mini, covering availability, evidence quality, performance, pricing, and production risk.
Read More
Gemini 3 Deep Think vs GPT-4o (Nov '24): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Deep Think and GPT-4o (Nov '24), covering availability, evidence quality, benchmark coverage, pricing, and practical selection risk.
Read More
Gemini 3 Deep Think vs GPT-5 mini (high): What Developers Can Actually Choose
A developer-focused comparison of Gemini 3 Deep Think and GPT-5 mini (high), emphasizing availability, evidence quality, performance signals, pricing uncertainty, and practical model-selection risk.
Read More
Gemini 3 Deep Think vs GPT-5 nano (high): Which Model Can Developers Actually Choose?
A source-grounded comparison of Gemini 3 Deep Think and GPT-5 nano (high), focused on availability, evidence, cost signals, performance data, and production risk.
Read More
Gemini 3 Deep Think vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Deep Think and GPT-5 (high), covering availability, evidence quality, coding performance, pricing, and production risk.
Read More
Gemini 3 Deep Think vs Grok-1: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Deep Think and Grok-1, covering availability, evidence quality, performance, pricing, and production risk.
Read More
Gemini 3 Flash Preview (Reasoning) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Flash Preview (Reasoning) and GPT-5 mini (high), covering benchmark signals, pricing, latency, evidence gaps, and practical model selection.
Read More
Gemini 3 Flash Preview (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Flash Preview (Reasoning) and GPT-5 (high), covering measured capability, latency, pricing, API maturity, and decision risks.
Read More
Gemini 3 Flash Preview (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Flash Preview (Reasoning) and o3 across intelligence, mathematics, speed, cost, and production risk.
Read More
Gemini 3 Pro Preview (low) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Pro Preview (low) and GPT-5 (high), covering benchmark evidence, pricing, API availability, version risk, and practical selection criteria.
Read More
Gemini 3 Pro Preview (low) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Pro Preview (low) and o3 across measurable quality, mathematics, speed, price, and API availability.
Read More
Gemini 3 Pro Preview (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A source-backed comparison of Gemini 3 Pro Preview (high) and GPT-5 mini (high), covering measured intelligence, mathematics, coding evidence, latency, pricing, and model availability uncertainty.
Read More
Gemini 3 Pro Preview (high) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemini 3 Pro Preview (high) and GPT-5 (high), covering availability, benchmark signals, latency, pricing, and evidence gaps.
Read More
Gemini 3 Pro Preview (high) vs o3: A Developer’s Model Selection Guide
A developer-focused comparison of Gemini 3 Pro Preview (high) and o3 across measured quality, speed, cost, availability, and deployment risk.
Read More
Gemma 4 31B (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of Gemma 4 31B (Reasoning) and GPT-5 (high), covering coding, reasoning, speed, pricing, API availability, and production risk.
Read More
GLM-4.6 (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-4.6 (Reasoning) and GPT-5 (high), covering benchmark tradeoffs, API certainty, pricing, latency, and selection risks.
Read More
GLM-4.7 (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-4.7 (Reasoning) and GPT-5 (high), covering coding, reasoning, latency, pricing, API readiness, evidence quality, and deployment risk.
Read More
GLM-4.7 (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GLM-4.7 (Reasoning) and o3 across benchmark evidence, speed, pricing, availability, and selection risk.
Read More
GLM-5.1 (Non-reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.1 (Non-reasoning) and GPT-5 (high), covering evidence quality, performance, pricing, API readiness, and migration risk.
Read More
GLM-5.1 (Non-reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.1 (Non-reasoning) and o3 across measured intelligence, mathematics, latency, output speed, pricing, and current availability evidence.
Read More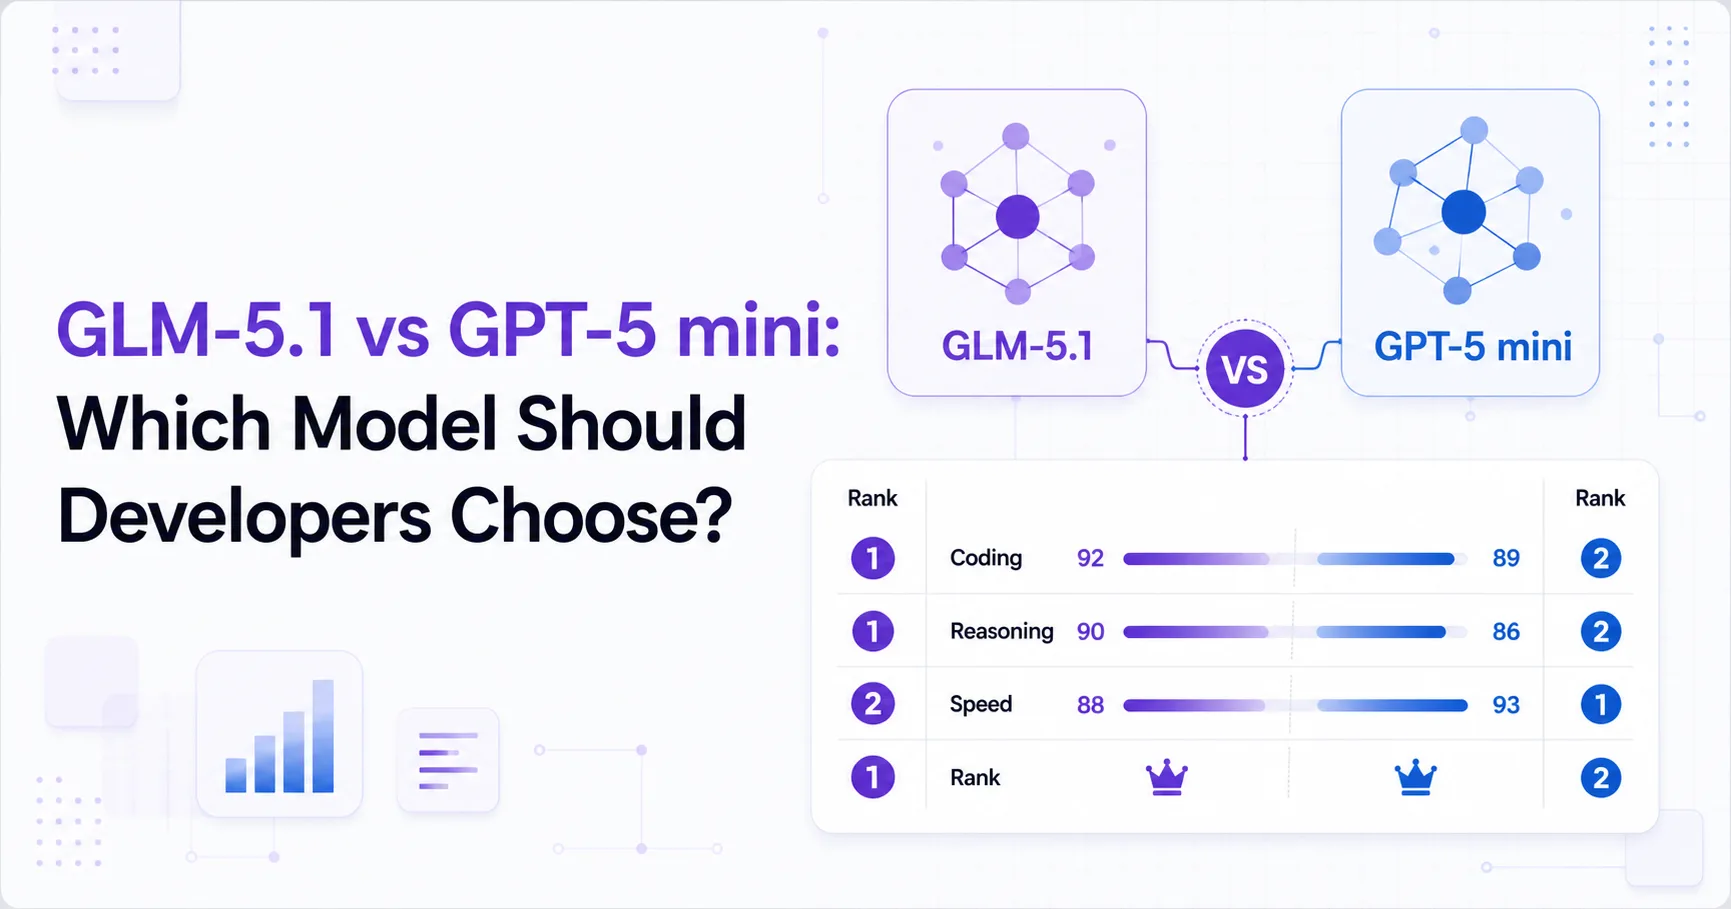
GLM-5.1 vs GPT-5 mini: Which Model Should Developers Choose?
A practical comparison of GLM-5.1 (Reasoning) and GPT-5 mini (high) for coding, reasoning, mathematics, latency, and API cost.
Read More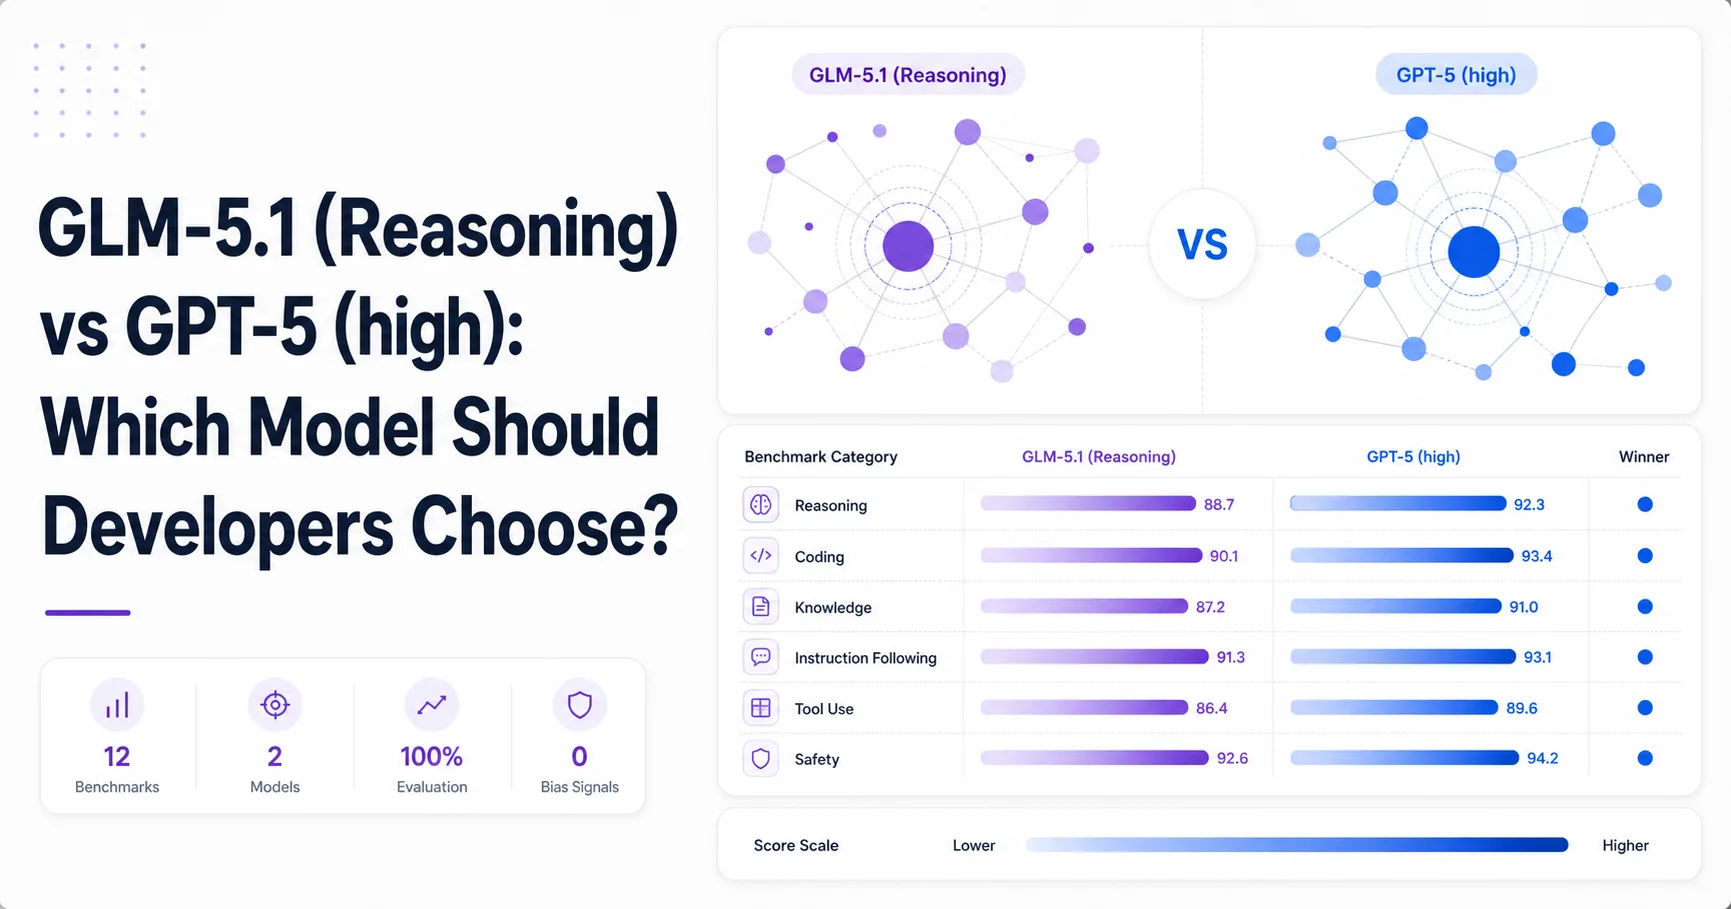
GLM-5.1 (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.1 (Reasoning) and GPT-5 (high), covering coding quality, reasoning, mathematics, cost, latency, documentation, and deployment risk.
Read More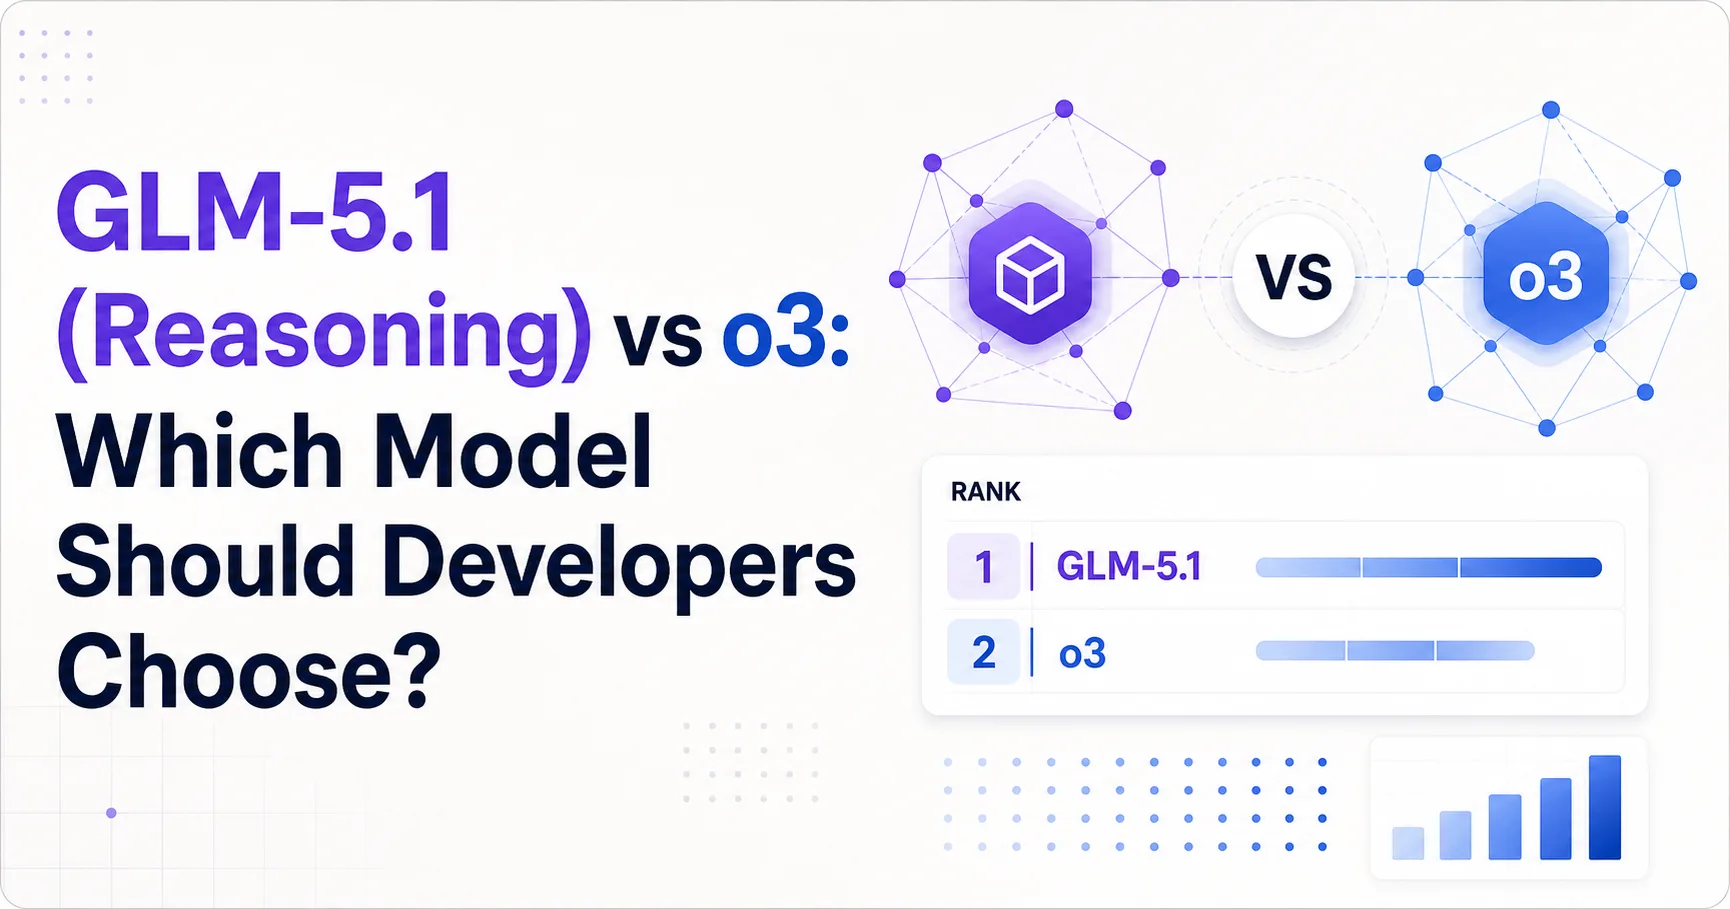
GLM-5.1 (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.1 (Reasoning) and o3 across measured quality, coding evidence, speed, pricing, availability, and selection risk.
Read More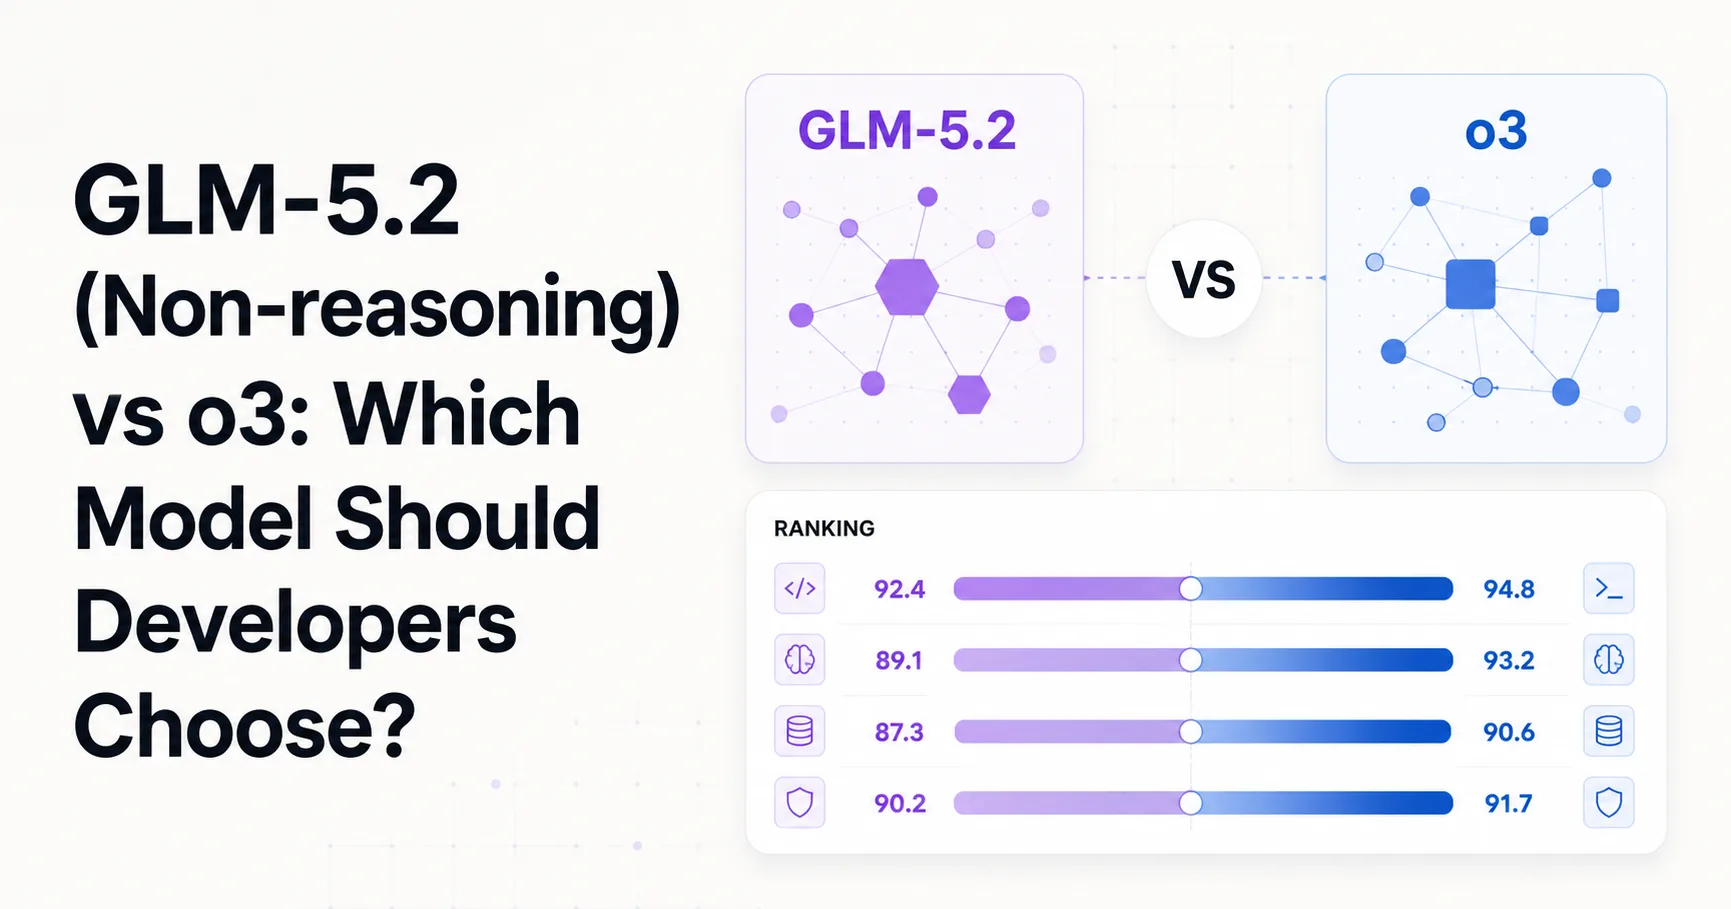
GLM-5.2 (Non-reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.2 (Non-reasoning) and o3 across measured intelligence, coding evidence, speed, cost, and current availability uncertainty.
Read More
GLM-5.2 (max) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.2 (max) and GPT-5 mini (high), covering coding performance, cost, availability evidence, speed, and operational risk.
Read More
GLM-5.2 (max) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.2 (max) and GPT-5 nano (high), covering measured intelligence, math, coding evidence, cost, speed, availability, and deployment risk.
Read More
GLM-5.2 (max) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.2 (max) and GPT-5 (high) across coding quality, reasoning, speed, pricing, reliability, and deployment trade-offs.
Read More
GLM-5.2 (max) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GLM-5.2 (max) and o3 across measured intelligence, coding evidence, speed, cost, availability, and operational risk.
Read More
GLM-5 (Non-reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5 (Non-reasoning) and GPT-5 (high), covering evidence quality, task capability, latency, pricing, production risk, and practical model selection.
Read More
GLM-5 (Non-reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GLM-5 (Non-reasoning) and o3 across measured intelligence, mathematics, latency, speed, pricing, and deployment confidence.
Read More
GLM-5-Turbo vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5-Turbo and GPT-5 mini (high), covering measured intelligence, math evidence, latency, pricing, availability uncertainty, and model-selection risk.
Read More
GLM-5-Turbo vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5-Turbo and GPT-5 (high), covering evidence quality, capability signals, latency, pricing, deployment risk, and practical model selection.
Read More
GLM-5 vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM-5 (Reasoning) and GPT-5 mini (high), covering measured intelligence, pricing, latency, evidence quality, and selection risk.
Read More
GLM-5 vs GPT-5: Which Reasoning Model Should Developers Choose?
A developer-focused comparison of GLM-5 (Reasoning) and GPT-5 (high), covering measured capability, pricing, lifecycle risk, evidence gaps, and practical model-selection trade-offs.
Read More
GLM-5 (Reasoning) vs o3: Which Model Should Developers Choose?
A practical comparison of GLM-5 (Reasoning) and o3 for developers choosing between cost, measured intelligence, mathematics, speed, and deployment confidence.
Read More
GLM 5V Turbo (Reasoning) vs GPT-5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GLM 5V Turbo (Reasoning) and GPT-5 (high), covering measured quality, latency, pricing, evidence gaps, version risk, and practical model selection.
Read More
GPT-4 vs GPT-5.4 Pro (xhigh): Which Model Should Developers Choose?
A careful developer-focused comparison of GPT-4 and GPT-5.4 Pro (xhigh), covering measured capabilities, pricing, availability evidence, and the risks created by missing official documentation.
Read More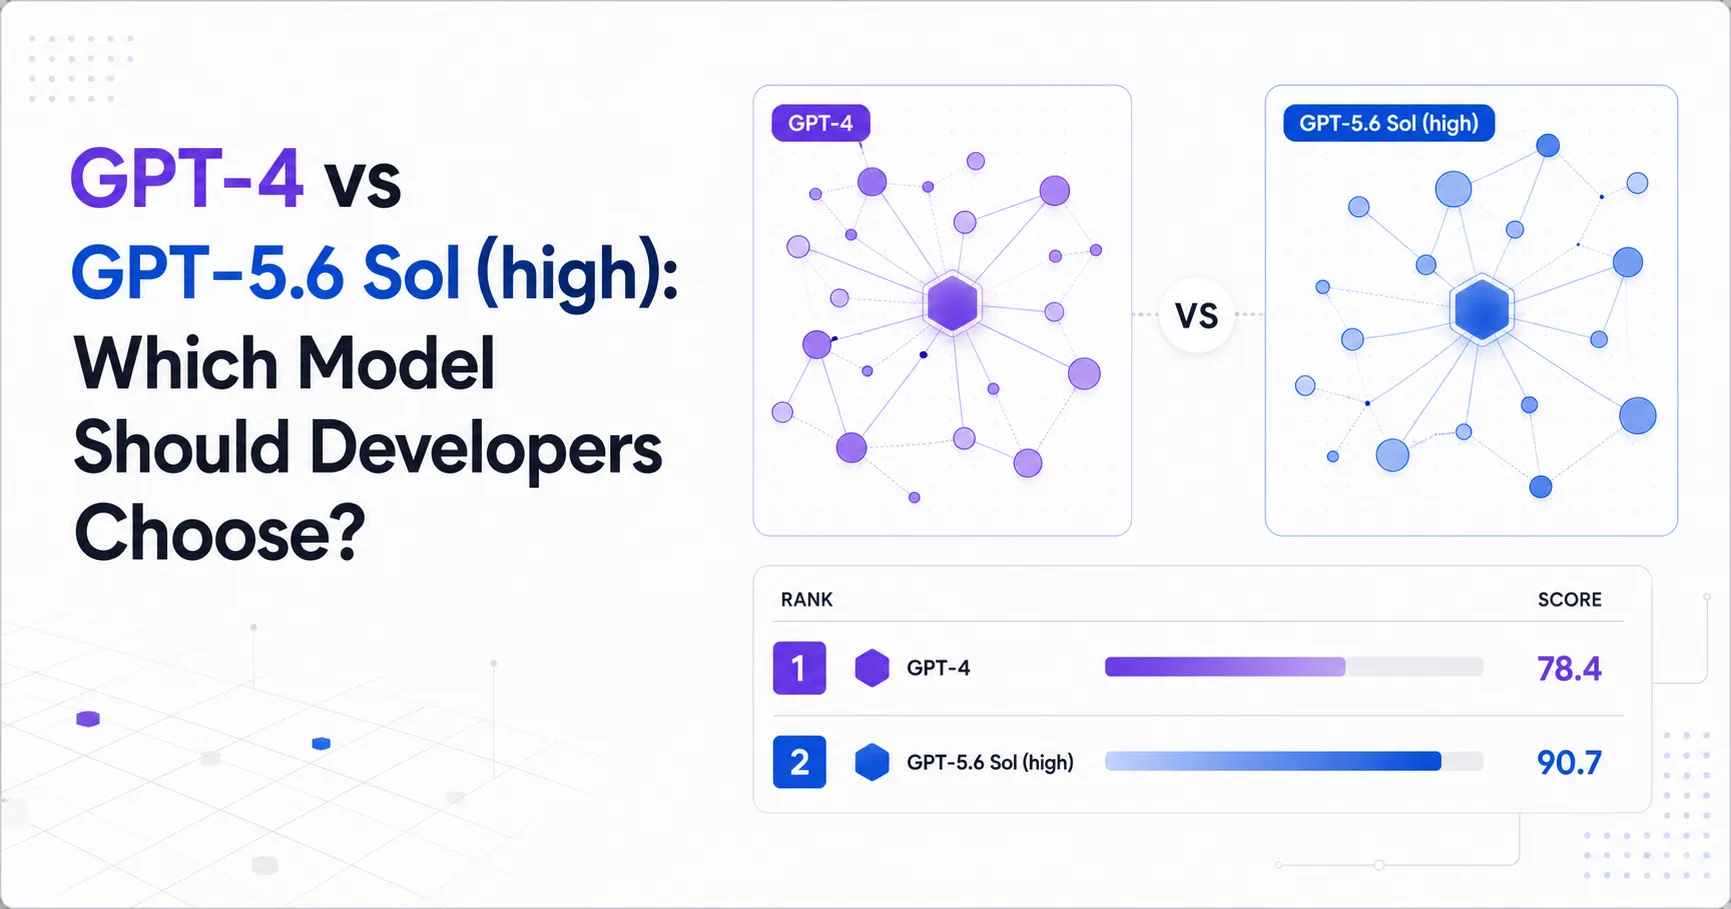
GPT-4 vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4 and GPT-5.6 Sol (high), covering capability, coding performance, cost, latency, evidence quality, and practical selection risks.
Read More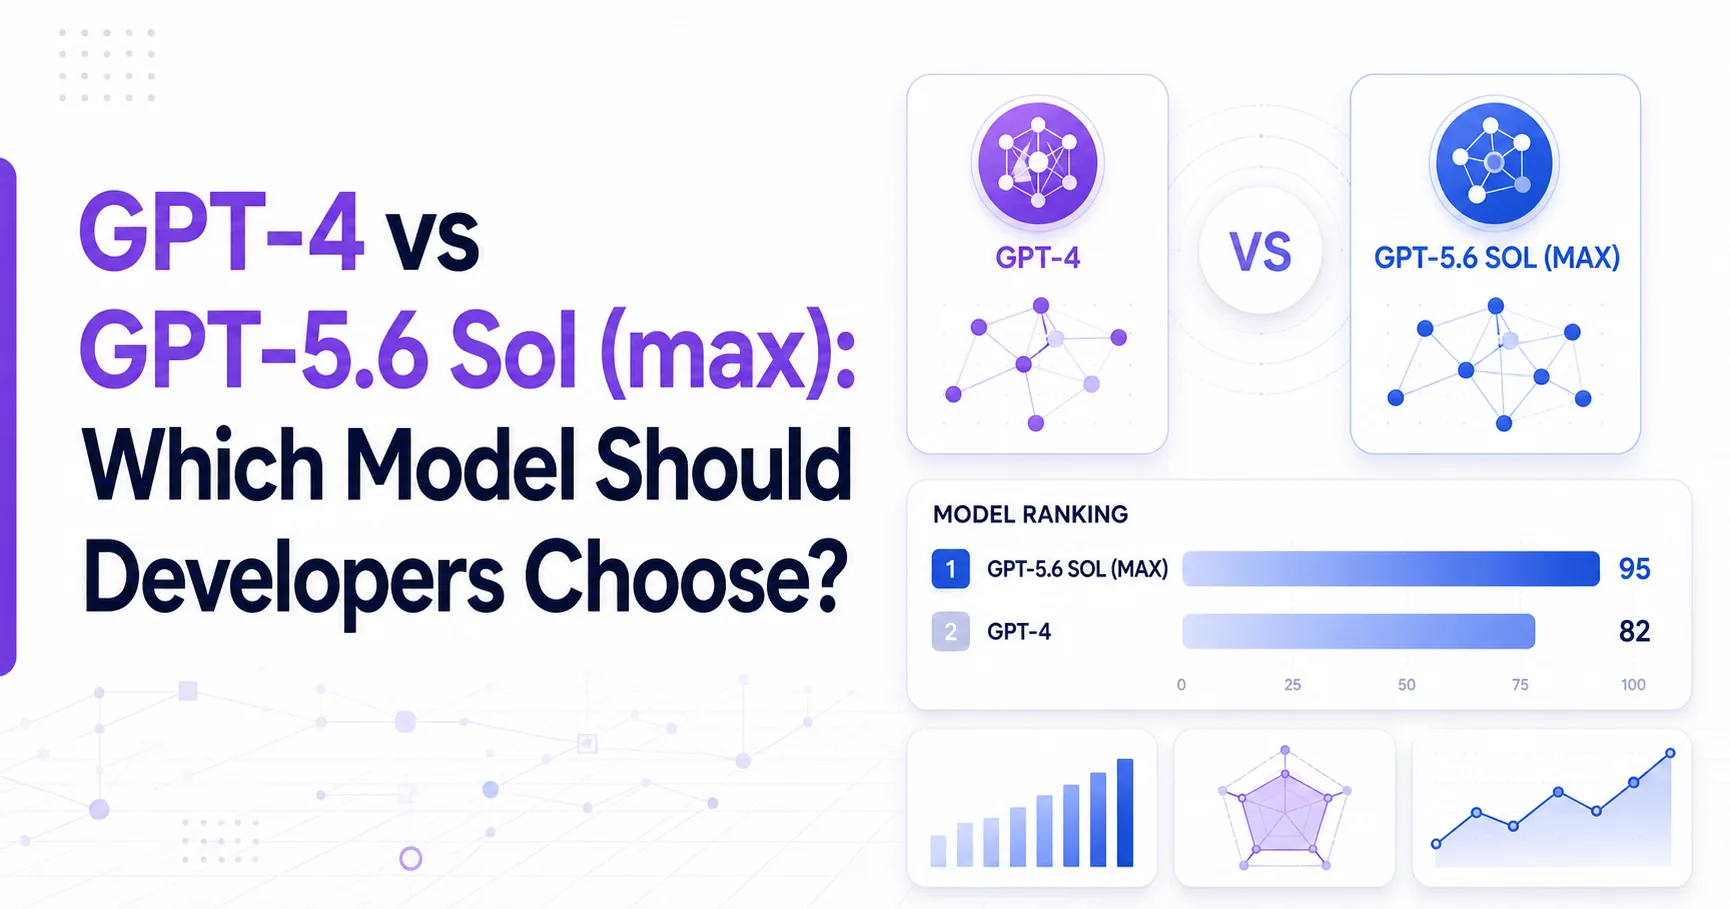
GPT-4 vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4 and GPT-5.6 Sol (max), covering capability evidence, speed, pricing, migration risk, and practical selection criteria.
Read More
GPT-4 vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4 and Kimi K3 (max), covering benchmark results, pricing, latency, API maturity, context uncertainty, and production risks.
Read More
GPT-4 vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A data-led comparison of GPT-4 and Mi:dm K 2.5 Pro Preview for developers choosing a model under incomplete documentation, uneven benchmark coverage, and uncertain availability.
Read More
GPT-4o mini vs GPT-5.4 Pro (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o mini and GPT-5.4 Pro (xhigh), covering verified capabilities, benchmark evidence, pricing, uncertainty, and practical selection criteria.
Read More
GPT-4o mini vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o mini and GPT-5.6 Sol (high), covering capability, cost, speed, operational risk, and practical model selection.
Read More
GPT-4o mini vs GPT-5.6 Sol (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o mini and GPT-5.6 Sol (xhigh), covering capability, latency, cost, availability, and practical selection criteria.
Read More
GPT-4o mini vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o mini and GPT-5.6 Sol (max), covering capability, latency, pricing, operational risk, and model-selection tradeoffs.
Read More
GPT-4o mini vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o mini and Kimi K3 (max), covering capability, latency, cost, API stability, and production fit.
Read More
GPT-4o mini vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o mini and Mi:dm K 2.5 Pro Preview, covering benchmark evidence, pricing uncertainty, documentation, and production-selection risks.
Read More
GPT-4o vs GPT-5.4 Pro (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and GPT-5.4 Pro (xhigh), covering measured benchmarks, cost, availability uncertainty, and practical model-selection risks.
Read More
GPT-4o (Nov '24) vs GPT-5.5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and GPT-5.5 (high), covering capability, latency, pricing, reliability, and practical model selection.
Read More
GPT-4o (Nov '24) vs GPT-5.5 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and GPT-5.5 (xhigh), covering capability evidence, latency, pricing, uncertainty, and practical model selection.
Read More
GPT-4o (Nov '24) vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A practical comparison of GPT-4o (Nov '24) and GPT-5.6 Sol (high) for developer workflows, covering capability evidence, cost, speed, reliability risks, and API availability.
Read More
GPT-4o (Nov '24) vs GPT-5.6 Sol (xhigh): Which Model Should Developers Choose?
A practical comparison of GPT-4o (Nov '24) and GPT-5.6 Sol (xhigh) for developers weighing capability, speed, cost, availability, and production risk.
Read More
GPT-4o (Nov '24) vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and GPT-5.6 Sol (max), covering capability, coding evidence, latency, pricing, operational risk, and model availability.
Read More
GPT-4o (Nov '24) vs GPT-5.6 Terra (xhigh): Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and GPT-5.6 Terra (xhigh), covering measured quality, speed, cost, API status, and deployment risks.
Read More
GPT-4o (Nov '24) vs GPT-5.6 Terra (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and GPT-5.6 Terra (max), covering measured intelligence, speed, pricing, API availability, and evidence gaps.
Read More
GPT-4o (Nov '24) vs Grok 4.5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and Grok 4.5 (high), covering availability, capability evidence, speed, pricing, operational risks, and model-selection trade-offs.
Read More
GPT-4o (Nov '24) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and Kimi K3 (max), covering evidence quality, reasoning, coding, latency, pricing, API readiness, and deployment risk.
Read More
GPT-4o (Nov '24) vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of GPT-4o (Nov '24) and Mi:dm K 2.5 Pro Preview, covering benchmark evidence, cost, availability uncertainty, and practical selection risks.
Read More
GPT-5.1 Codex (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.1 Codex (high) and o3 across benchmark results, latency, pricing, availability evidence, and practical model-selection risk.
Read More
GPT-5.1 (high) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.1 (high) and o3 across reasoning quality, math, coding evidence, latency, speed, pricing, and operational uncertainty.
Read More
GPT-5.2 Codex (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.2 Codex (xhigh) and GPT-5 mini (high), covering measured intelligence, cost, latency, evidence gaps, availability, and practical model-selection risks.
Read More
GPT-5.2 Codex (xhigh) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.2 Codex (xhigh) and o3, covering measured capability, speed, pricing, availability evidence, and practical selection criteria.
Read More
GPT-5.2 (medium) vs GPT-5 mini (high): Which Model Should Developers Choose?
A practical comparison of GPT-5.2 (medium) and GPT-5 mini (high) for developer model selection, covering benchmark evidence, cost, availability uncertainty, and decision risks.
Read More
GPT-5.2 (medium) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.2 (medium) and o3 covering capability signals, latency, pricing, documentation risk, and production fit.
Read More
GPT-5.2 (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.2 (xhigh) and GPT-5 mini (high), covering evaluation results, latency, pricing, availability evidence, and model-selection risk.
Read More
GPT-5.2 (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.2 (xhigh) and o3, covering measured capability, speed, cost, API availability, and model-selection risk.
Read More
GPT-5.3 Codex vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.3 Codex and GPT-5 mini across documented positioning, measured performance, cost, availability, and selection risk.
Read More
GPT-5.3 Codex vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.3 Codex and GPT-5 nano across capability, speed, cost, availability, and selection risk.
Read More
GPT-5.3 Codex vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.3 Codex and o3 covering capability signals, speed, pricing, availability uncertainty, and practical selection criteria.
Read More
GPT-5.4 (low) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 (low) and o3 across measured intelligence, latency, pricing, availability evidence, and decision risk.
Read More
GPT-5.4 mini (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 mini (xhigh) and GPT-5 mini (high), covering coding quality, general intelligence, math evidence, pricing, availability uncertainty, and practical model selection.
Read More
GPT-5.4 mini (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 mini (xhigh) and o3 across measured intelligence, mathematics, coding evidence, latency, speed, pricing, and API availability.
Read More
GPT-5.4 nano vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 nano (xhigh) and GPT-5 mini (high), covering measured capability, latency, pricing, API availability, and selection risks.
Read More
GPT-5.4 nano (xhigh) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 nano (xhigh) and o3 across capability evidence, speed, pricing, availability, and selection risk.
Read More
GPT-5.4 Pro (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 Pro (xhigh) and GPT-5 mini (high), covering evidence quality, cost, benchmarks, availability, and selection risk.
Read More
GPT-5.4 Pro (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 Pro (xhigh) and GPT-5 nano (high), covering evidence quality, benchmark visibility, price, speed, and production risk.
Read More
GPT-5.4 (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 (xhigh) and GPT-5 mini (high), covering capability, coding performance, cost, availability, and model-selection risks.
Read More
GPT-5.4 (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 (xhigh) and GPT-5 nano (high), covering capability evidence, cost, availability, latency, and selection risks.
Read More
GPT-5.4 (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.4 (xhigh) and o3 across measured intelligence, coding evidence, mathematics, latency, cost, availability, and deployment risk.
Read More
GPT-5.5 (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (high) and GPT-5 mini (high), covering capability, coding performance, cost, availability evidence, and model-selection tradeoffs.
Read More
GPT-5.5 (high) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (high) and GPT-5 nano (high), covering capability evidence, pricing, uncertainty, and practical selection criteria.
Read More
GPT-5.5 (high) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (high) and o3 across capability evidence, speed, cost, availability, reliability, and practical model-selection trade-offs.
Read More
GPT-5.5 Instant (May 2026) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 Instant (May 2026) and o3 across measured intelligence, math coverage, latency, speed, price, and API availability uncertainty.
Read More
GPT-5.5 (low) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (low) and GPT-5 mini (high), covering coding performance, cost, latency, evidence gaps, and practical model selection.
Read More
GPT-5.5 (low) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (low) and GPT-5 nano (high), covering intelligence, coding evidence, latency, pricing, availability uncertainty, and practical selection criteria.
Read More
GPT-5.5 (low) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (low) and o3 across capability signals, speed, cost, availability, and production risk.
Read More
GPT-5.5 (medium) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (medium) and GPT-5 mini (high), covering coding capability, cost, availability evidence, and practical model-selection tradeoffs.
Read More
GPT-5.5 (medium) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (medium) and GPT-5 nano (high), covering capability evidence, cost, availability, uncertainty, and practical model selection.
Read More
GPT-5.5 (medium) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (medium) and o3 covering capability evidence, coding relevance, speed, cost, API availability, and migration risk.
Read More
GPT-5.5 (Non-reasoning) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (Non-reasoning) and o3 across measured intelligence, math and coding evidence, latency, pricing, and current API visibility.
Read More
GPT-5.5 Pro (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 Pro (xhigh) and GPT-5 mini (high), covering evidence quality, benchmark visibility, pricing status, and production risk.
Read More
GPT-5.5 Pro (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A practical comparison of GPT-5.5 Pro (xhigh) and GPT-5 nano (high), focused on evidence quality, pricing uncertainty, measured capabilities, availability, and developer selection risk.
Read More
GPT-5.5 Pro (xhigh) vs Grok-1: A Practical Model Selection Guide
A evidence-led comparison of GPT-5.5 Pro (xhigh) and Grok-1 for developers, focused on availability, pricing, performance evidence, and production risk.
Read More
GPT-5.5 (xhigh) vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (xhigh) and GPT-5.6 Sol (high), covering measured quality, speed evidence, API configuration, pricing, workflow risks, and migration decisions.
Read More
GPT-5.5 vs GPT-5.6 Sol (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 and GPT-5.6 Sol across capability, speed evidence, pricing, API fit, and production risks.
Read More
GPT-5.5 (xhigh) vs GPT-5.6 Sol (max): Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (xhigh) and GPT-5.6 Sol (max), covering capability, speed, pricing, lifecycle status, workflow fit, and evidence gaps.
Read More
GPT-5.5 (xhigh) vs GPT-5.6 Terra (max): A Developer's Model Selection Guide
A developer-focused comparison of GPT-5.5 (xhigh) and GPT-5.6 Terra (max), covering quality, coding, speed, pricing, evidence gaps, and production fit.
Read More
GPT-5.5 (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (xhigh) and GPT-5 mini (high), covering coding quality, latency, pricing, model availability, and selection risks.
Read More
GPT-5.5 (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (xhigh) and GPT-5 nano (high), covering capability, cost, availability, uncertainty, and practical model-selection tradeoffs.
Read More
GPT-5.5 (xhigh) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 and Kimi K3 across quality, coding, latency, cost, tooling, and production risks.
Read More
GPT-5.5 (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.5 (xhigh) and o3 across capability evidence, coding relevance, speed, pricing, availability, and deployment risk.
Read More
GPT-5.6 Luna (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (high) and GPT-5 mini (high), covering benchmark evidence, speed, pricing, API availability, and selection risks.
Read More
GPT-5.6 Luna (high) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (high) and GPT-5 nano (high), covering measured capability, speed, pricing, API availability, and evidence gaps.
Read More
GPT-5.6 Luna (high) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (high) and o3 covering measured performance, pricing, availability risk, and practical model-selection trade-offs.
Read More
GPT-5.6 Luna (low) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (low) and o3 across price, speed, available evidence, model availability, and practical selection risk.
Read More
GPT-5.6 Luna (medium) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (medium) and GPT-5 mini (high), covering measured quality, speed, cost, uncertainty, and practical model-selection risks.
Read More
GPT-5.6 Luna (medium) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (medium) and o3 across measured intelligence, speed, pricing, availability, and evidence quality.
Read More
GPT-5.6 Luna vs GPT-5 mini: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna and GPT-5 mini across coding, intelligence, mathematics, speed, pricing, API availability, and production risk.
Read More
GPT-5.6 Luna vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna and GPT-5 nano across capability, speed, cost, availability, and production risk.
Read More
GPT-5.6 Luna vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna and o3 covering measured performance, cost, availability evidence, and model-selection risk.
Read More
GPT-5.6 Luna (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (xhigh) and GPT-5 mini (high), covering measured capability, speed, pricing, availability evidence, and practical selection risks.
Read More
GPT-5.6 Luna (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (xhigh) and GPT-5 nano (high), covering evidence quality, speed, pricing, capability fit, and API availability.
Read More
GPT-5.6 Luna (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Luna (xhigh) and o3 across measured intelligence, coding evidence, speed, pricing, API visibility, and selection risk.
Read More
GPT-5.6 Sol (high) vs GPT-5.6 Sol (xhigh): Which Reasoning Setting Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol high and xhigh reasoning settings across coding quality, speed, cost, API behavior, and production fit.
Read More
GPT-5.6 Sol (high) vs GPT-5.6 Terra (max): Which Model Should Developers Choose?
GPT-5.6 Sol leads measured quality, while GPT-5.6 Terra delivers substantially better speed and cost for high-volume developer workloads.
Read More
GPT-5.6 Sol (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (high) and GPT-5 mini (high), covering capability, speed, cost, API availability, evidence quality, and practical selection criteria.
Read More
GPT-5.6 Sol (high) vs GPT-5 nano (high): Which Model Should Developers Choose?
A source-backed comparison of GPT-5.6 Sol (high) and GPT-5 nano (high) for developer model selection, covering capability, speed, cost, availability, and evidence gaps.
Read More
GPT-5.6 Sol (high) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (high) and Kimi K3 (max), covering coding quality, output speed, cost, API configuration, and production risks.
Read More
GPT-5.6 Sol (high) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (high) and o3 across capability evidence, speed, cost, availability, and practical model-selection risks.
Read More
GPT-5.6 Sol (low) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (low) and GPT-5 mini (high), covering coding quality, speed, cost, availability, and evidence gaps.
Read More
GPT-5.6 Sol (low) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (low) and GPT-5 nano (high), covering capability evidence, speed, pricing uncertainty, and practical model-selection risks.
Read More
GPT-5.6 Sol (low) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (low) and o3, covering measured intelligence, speed, cost, availability uncertainty, and practical model-selection trade-offs.
Read More
GPT-5.6 Sol (medium) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (medium) and GPT-5 mini (high), covering coding quality, reasoning, speed, cost, availability, and evidence gaps.
Read More
GPT-5.6 Sol (medium) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (medium) and GPT-5 nano (high), covering capability, speed, cost, evidence quality, and practical model selection.
Read More
GPT-5.6 Sol (medium) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (medium) and o3 across reasoning quality, coding evidence, speed, cost, availability, and operational risk.
Read More
GPT-5.6 Sol (Non-reasoning) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (Non-reasoning) and GPT-5 mini (high), covering coding quality, latency, pricing, evidence gaps, and practical model selection.
Read More
GPT-5.6 Sol Non-reasoning vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol Non-reasoning and o3 across measured quality, coding evidence, speed, cost, and current API availability.
Read More
GPT-5.6 Sol (max) vs GPT-5.6 Sol (high): Which Setting Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol reasoning settings across measured quality, coding, speed, pricing, and practical deployment risk.
Read MoreGPT-5.6 Sol (max) vs GPT-5.6 Sol (xhigh): A Developer Decision Guide
A developer-focused comparison of GPT-5.6 Sol reasoning configurations across coding quality, general intelligence, speed, cost, and production fit.
Read More
GPT-5.6 Sol (max) vs GPT-5.6 Terra (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol and GPT-5.6 Terra across quality, speed, cost, API capabilities, evidence, and production fit.
Read More
GPT-5.6 Sol (max) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (max) and GPT-5 mini (high), covering capability, speed, cost, evidence quality, and practical model selection.
Read More
GPT-5.6 Sol vs GPT-5 nano: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (max) and GPT-5 nano (high), covering capability evidence, cost, speed, availability, and selection risks.
Read More
GPT-5.6 Sol (max) vs Grok-1: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (max) and Grok-1 across measured intelligence, coding evidence, speed, pricing, API availability, and selection risk.
Read More
GPT-5.6 Sol (max) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol and Kimi K3 across capability, speed, cost, tooling, multimodal input, and production risk.
Read More
GPT-5.6 Sol (max) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (max) and o3 across intelligence, coding, speed, cost, availability, and evidence quality.
Read More
GPT-5.6 Sol (xhigh) vs GPT-5.6 Terra (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol and GPT-5.6 Terra across quality, speed, cost, API behavior, and practical deployment risk.
Read More
GPT-5.6 Sol (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (xhigh) and GPT-5 mini (high), covering capability, speed, cost, evidence quality, and practical model selection.
Read More
GPT-5.6 Sol (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (xhigh) and GPT-5 nano (high), covering capability evidence, speed, pricing, availability uncertainty, and practical model selection.
Read More
GPT-5.6 Sol (xhigh) vs Grok-1: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (xhigh) and Grok-1 across measured intelligence, coding evidence, speed, cost, availability, and production risk.
Read More
GPT-5.6 Sol (xhigh) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol and Kimi K3 across coding quality, speed, cost, multimodal support, agent tooling, and production risks.
Read More
GPT-5.6 Sol (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Sol (xhigh) and o3 across capability evidence, speed, cost, API availability, and production risk.
Read More
GPT-5.6 Terra (high) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (high) and GPT-5 mini (high), covering capability, speed, pricing, evidence gaps, and practical model selection.
Read More
GPT-5.6 Terra (high) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (high) and GPT-5 nano (high), covering measured quality, speed, pricing, availability uncertainty, and practical model-selection risks.
Read More
GPT-5.6 Terra (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (high) and o3 across intelligence, coding evidence, speed, cost, API availability, and selection risk.
Read More
GPT-5.6 Terra (low) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (low) and GPT-5 mini (high), covering coding quality, intelligence, speed, cost, availability, and evidence gaps.
Read More
GPT-5.6 Terra (low) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (low) and o3 across measured intelligence, coding evidence, speed, cost, availability, and deployment risk.
Read More
GPT-5.6 Terra (medium) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (medium) and GPT-5 mini (high), covering coding quality, speed, cost, availability, and evidence gaps.
Read More
GPT-5.6 Terra (medium) vs GPT-5 nano (high): Which Model Should Developers Choose?
A source-grounded comparison of GPT-5.6 Terra (medium) and GPT-5 nano (high), covering intelligence, coding evidence, mathematics, speed, pricing, availability, and selection risks.
Read More
GPT-5.6 Terra (medium) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (medium) and o3 across intelligence, coding evidence, speed, latency, pricing, and API availability.
Read More
GPT-5.6 Terra (Non-reasoning) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (Non-reasoning) and o3 across capability signals, speed, pricing, API availability, and selection risk.
Read More
GPT-5.6 Terra (max) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (max) and GPT-5 mini (high), covering capability, speed, cost, availability, evidence quality, and practical model selection.
Read More
GPT-5.6 Terra vs GPT-5 nano: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra and GPT-5 nano across intelligence, coding, mathematics, speed, cost, availability, and deployment risk.
Read More
GPT-5.6 Terra vs Kimi K3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra and Kimi K3 across coding, intelligence, speed, cost, multimodal input, and production risk.
Read More
GPT-5.6 Terra vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra and o3 across intelligence, coding evidence, speed, cost, availability, and production risk.
Read More
GPT-5.6 Terra (xhigh) vs GPT-5 mini (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (xhigh) and GPT-5 mini (high), covering coding quality, speed, cost, deployment confidence, and selection trade-offs.
Read More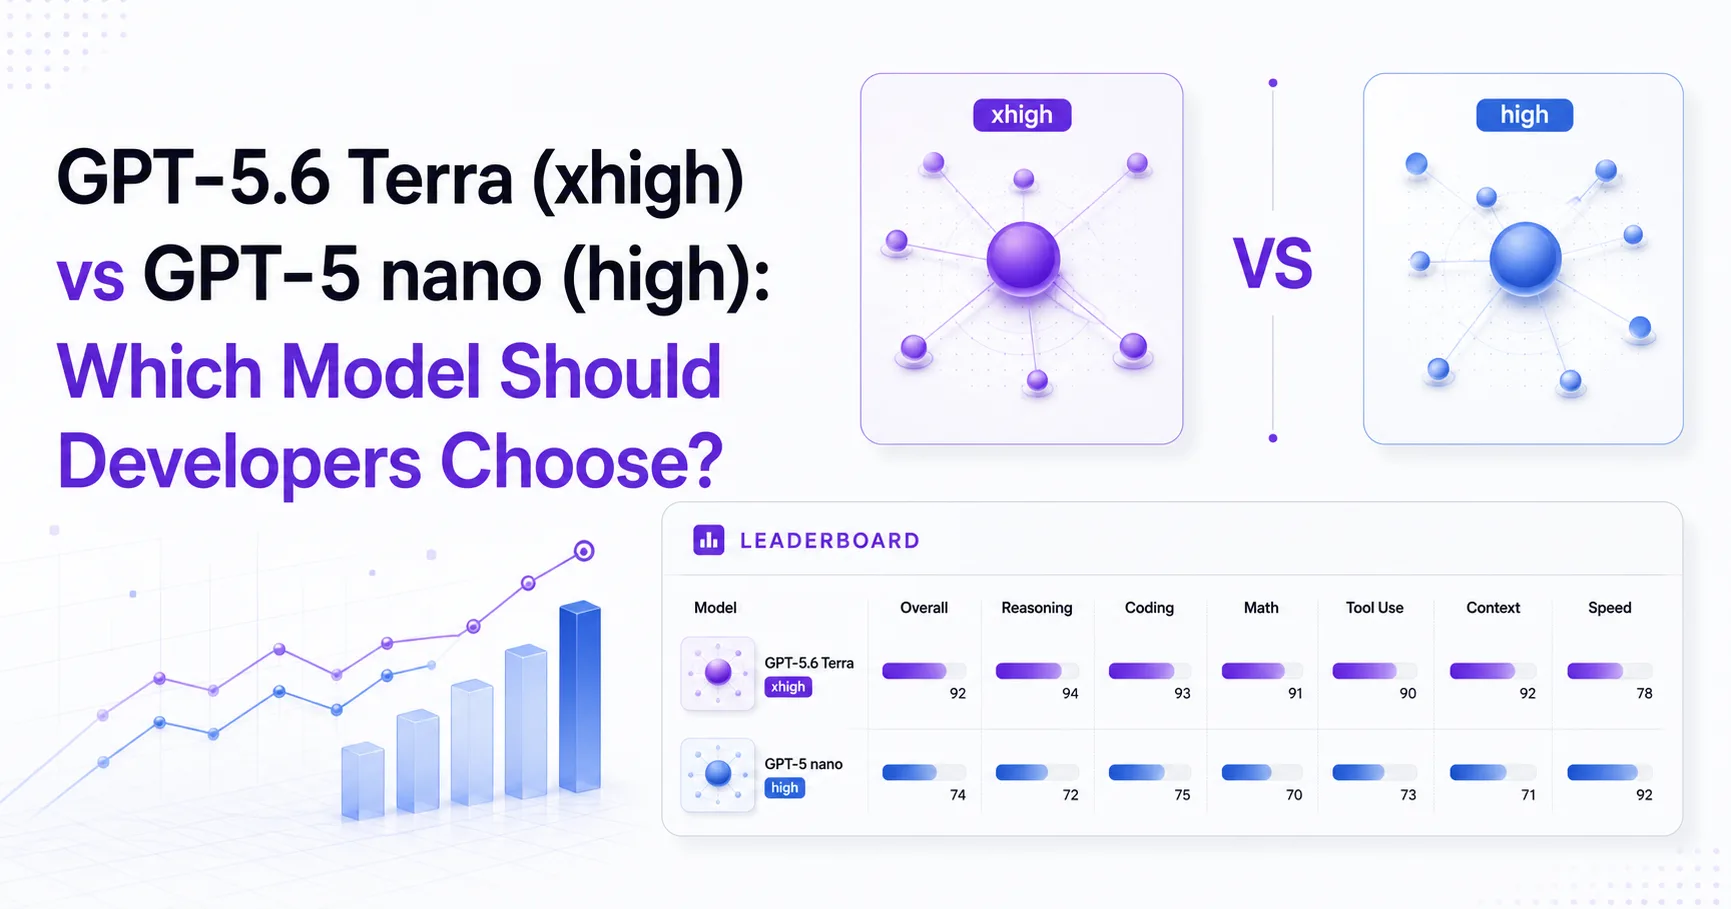
GPT-5.6 Terra (xhigh) vs GPT-5 nano (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (xhigh) and GPT-5 nano (high), covering capability evidence, speed, pricing, availability uncertainty, and workload fit.
Read More
GPT-5.6 Terra (xhigh) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5.6 Terra (xhigh) and o3 across intelligence, coding, mathematics, speed, cost, API availability, and deployment risk.
Read More
GPT-5 Codex (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 Codex (high) and o3 across benchmark results, speed, pricing, availability, and production risk.
Read More
GPT-5 (low) vs Grok 4: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (low) and Grok 4 across benchmark results, pricing, latency, evidence quality, and model-selection risk.
Read More
GPT-5 (low) vs o3-pro: Which OpenAI Model Should Developers Choose?
A practical comparison of GPT-5 (low) and o3-pro for developer model selection, covering benchmark evidence, latency, pricing, API certainty, and evidence gaps.
Read More
GPT-5 (medium) vs GPT-5 mini (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (medium) and GPT-5 mini (medium), covering benchmark evidence, latency, pricing, availability risk, and practical model-selection tradeoffs.
Read More
GPT-5 (medium) vs Grok 4: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (medium) and Grok 4 across benchmark results, latency, pricing, evidence quality, and deployment risk.
Read More
GPT-5 (medium) vs o3-pro: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 (medium) and o3-pro covering measured quality, latency, pricing, evidence gaps, and practical model selection criteria.
Read More
GPT-5 (medium) vs o3: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 (medium) and o3 across measured quality, latency, pricing, availability, and evidence gaps.
Read More
GPT-5 mini (medium) vs Grok 4: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (medium) and Grok 4 across benchmark performance, latency, pricing, evidence quality, and practical model-selection risk.
Read More
GPT-5 mini (medium) vs o3-pro: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (medium) and o3-pro across measured quality, latency, pricing, availability, and evidence quality.
Read More
GPT-5 mini (high) vs Grok 4.3 (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Grok 4.3 (high), covering benchmark evidence, cost, latency, availability, and selection risk.
Read More
GPT-5 mini vs Grok 4.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini and Grok 4.5 across capability, speed, cost, availability, and implementation risk.
Read More
GPT-5 mini (high) vs Grok Build 0.1 0616: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Grok Build 0.1 0616 across benchmark results, cost, latency, availability, and evidence quality.
Read More
GPT-5 mini (high) vs Hy3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Hy3 across benchmark evidence, speed, pricing, availability, and selection risk.
Read More
GPT-5 mini (high) vs Inkling Small: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Inkling Small across capability signals, cost, speed, availability, and evidence quality.
Read More
GPT-5 mini (high) vs Inkling (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Inkling (xhigh), covering capability evidence, latency, pricing, uncertainty, and practical model selection.
Read More
GPT-5 mini (high) vs JT-4.1 Flash 236B A21B: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and JT-4.1 Flash 236B A21B across measured quality, latency, price, and deployment confidence.
Read More
GPT-5 mini (high) vs Kimi K2.6: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Kimi K2.6 across benchmark performance, latency, pricing, evidence quality, and practical model-selection risks.
Read More
GPT-5 mini (high) vs Kimi K2.7 Code: Which Model Should Developers Choose?
A data-led comparison of GPT-5 mini (high) and Kimi K2.7 Code for developer model selection, covering coding performance, cost, latency, availability, and evidence gaps.
Read More
GPT-5 mini (high) vs Kimi K3 (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Kimi K3 (low), covering measured capability, latency, price, evidence quality, and practical selection risk.
Read More
GPT-5 mini (high) vs Kimi K3 (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Kimi K3 (max), covering measured capability, pricing, availability, integration risk, and practical selection criteria.
Read More
GPT-5 mini (high) vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Mi:dm K 2.5 Pro Preview, covering benchmark evidence, pricing visibility, reliability risks, and model-selection tradeoffs.
Read More
GPT-5 mini (high) vs MiMo-V2.5-Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and MiMo-V2.5-Pro across coding, reasoning, mathematics, speed, pricing, availability, and evidence quality.
Read More
GPT-5 mini (high) vs MiMo-V2-Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and MiMo-V2-Pro across intelligence, coding evidence, latency, pricing, availability, and selection risk.
Read More
GPT-5 mini (high) vs MiniMax-M2.7: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and MiniMax-M2.7 across benchmark performance, latency, pricing, evidence quality, and model-selection risk.
Read More
GPT-5 mini (high) vs MiniMax-M3: Which Model Should Developers Choose?
A data-led comparison of GPT-5 mini (high) and MiniMax-M3 for coding, reasoning, latency, and API cost, with explicit coverage of evidence gaps.
Read More
GPT-5 mini (high) vs Motif 3 (Beta): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Motif 3 (Beta), covering capability signals, pricing, evidence quality, and practical model-selection risks.
Read More
GPT-5 mini (high) vs Muse Spark 1.1 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Muse Spark 1.1 (xhigh), covering capability evidence, API availability, performance, pricing, risks, and practical model selection.
Read More
GPT-5 mini (high) vs Muse Spark: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Muse Spark across measured capability, coding, mathematics, latency, pricing, and deployment certainty.
Read More
GPT-5 mini (high) vs Nex-N2-Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Nex-N2-Pro across capability, coding, latency, pricing, evidence quality, and production risk.
Read More
GPT-5 mini vs Nemotron 3 Ultra 550B A55B: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Nemotron 3 Ultra 550B A55B (Reasoning), covering benchmark evidence, speed, cost, availability, and selection risk.
Read More
GPT-5 mini (high) vs Qwen3.6 Plus: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Qwen3.6 Plus across intelligence, coding, mathematics, latency, speed, pricing, and verified availability.
Read More
GPT-5 mini (high) vs Qwen3.7 Max: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Qwen3.7 Max across benchmark evidence, latency, pricing, availability, and decision risk.
Read More
GPT-5 mini (high) vs Qwen3.7 Plus: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 mini (high) and Qwen3.7 Plus across capability signals, latency, pricing, evidence quality, and model-selection risk.
Read More
GPT-5 nano vs Grok 4.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano and Grok 4.5 across measured quality, speed, cost, API availability, and production risk.
Read More
GPT-5 nano (high) vs Kimi K2.6: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano (high) and Kimi K2.6 across measured intelligence, mathematics, latency, pricing, availability, and evidence quality.
Read More
GPT-5 nano (high) vs Kimi K3 (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano (high) and Kimi K3 (low), covering benchmark evidence, latency, pricing uncertainty, and model-selection risks.
Read More
GPT-5 nano vs Kimi K3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano and Kimi K3 covering availability, reasoning, coding, latency, cost, API constraints, and production risk.
Read More
GPT-5 nano (high) vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano (high) and Mi:dm K 2.5 Pro Preview, covering benchmark trade-offs, recorded pricing, availability risks, and practical selection criteria.
Read More
GPT-5 nano vs MiniMax-M3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano and MiniMax-M3 covering measured quality, speed, pricing, evidence gaps, and practical model-selection risks.
Read More
GPT-5 nano (high) vs Motif 3 (Beta): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano (high) and Motif 3 (Beta), covering benchmark evidence, latency, pricing, availability risk, and model-selection tradeoffs.
Read More
GPT-5 nano vs Muse Spark 1.1: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano and Muse Spark 1.1 across capability evidence, latency, pricing, API maturity, and deployment risk.
Read More
GPT-5 nano (high) vs Muse Spark: A Developer’s Model Selection Guide
A data-led comparison of GPT-5 nano (high) and Muse Spark for developers choosing between cost, measured capability, latency, and evidence quality.
Read More
GPT-5 nano (high) vs Qwen3.7 Max: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 nano (high) and Qwen3.7 Max based on available pricing, latency, evaluation data, and evidence gaps.
Read More
GPT-5 vs GPT-5.1 Codex mini: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.1 Codex mini, covering capability evidence, API availability, cost, latency, and deployment risk.
Read More
GPT-5 vs GPT-5.1 Codex (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.1 Codex (high), covering verified API status, evaluation data, cost, latency, and selection risk.
Read More
GPT-5 vs GPT-5.1 (High): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.1 (high), covering coding, reasoning, mathematics, latency, pricing, documentation status, and selection risks.
Read More
GPT-5 vs GPT-5.2 Codex: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.2 Codex across intelligence, coding evidence, latency, pricing, API availability, and migration risk.
Read More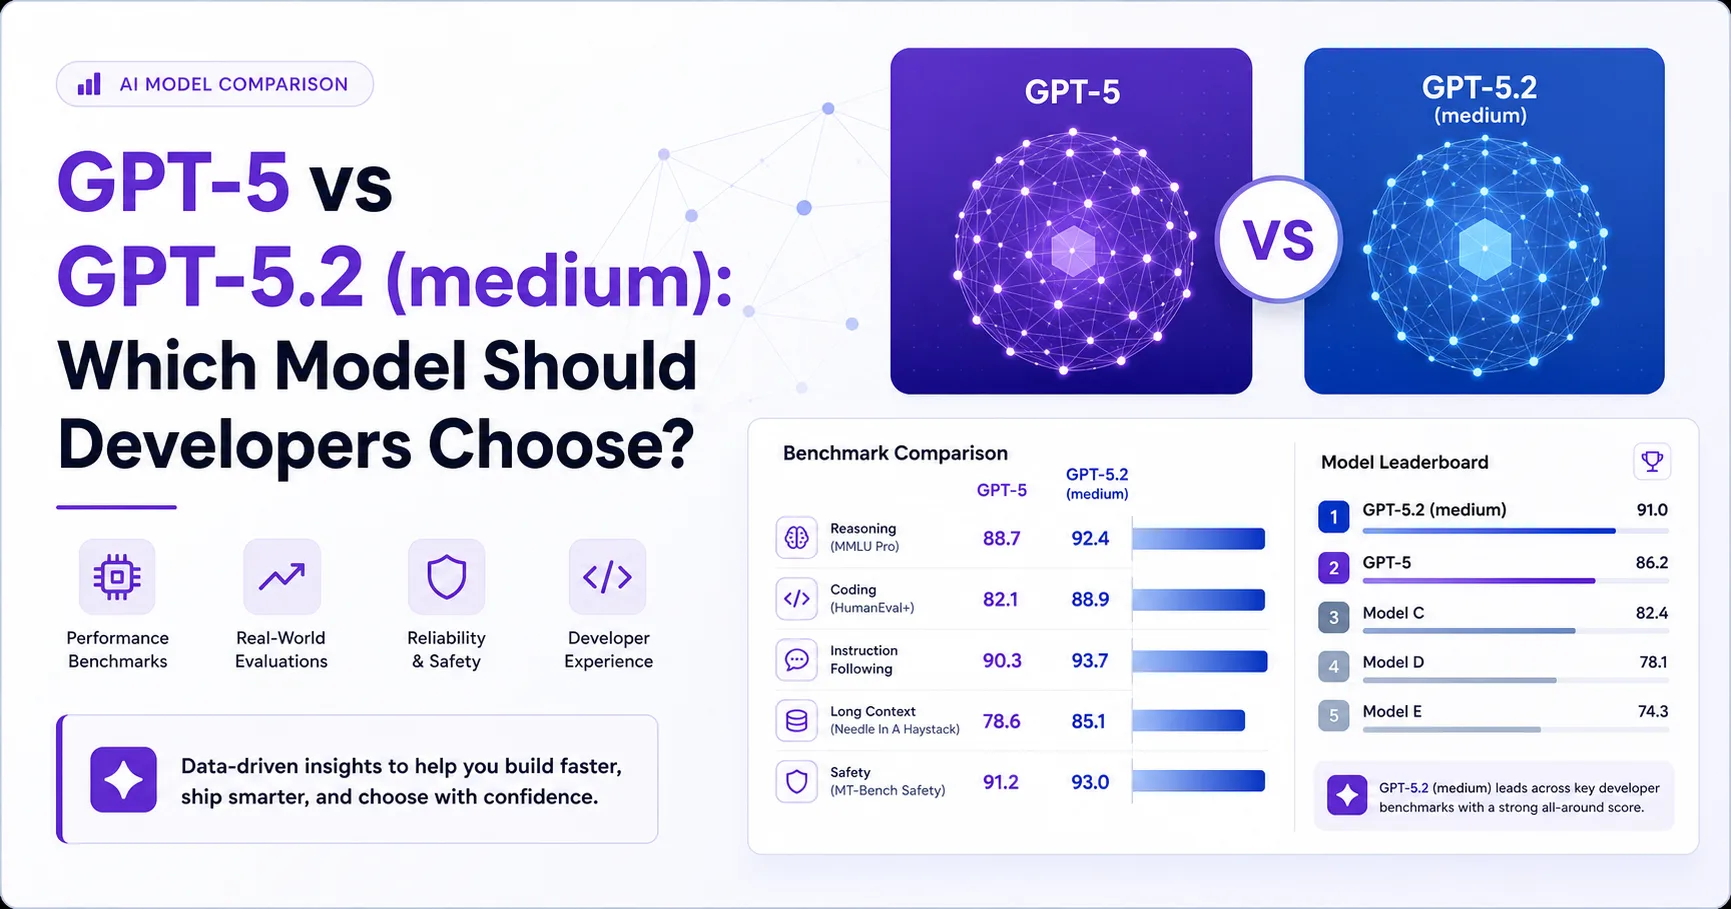
GPT-5 vs GPT-5.2 (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.2 (medium), covering measured quality, cost, API evidence, version risk, and selection guidance.
Read More
GPT-5 vs GPT-5.2: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.2 (xhigh), covering benchmark evidence, API availability, cost, uncertainty, and practical selection criteria.
Read More
GPT-5 vs GPT-5.3 Codex: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.3 Codex across reasoning, coding evidence, speed, cost, API maturity, and production risk.
Read More
GPT-5 (high) vs GPT-5.4 (low): Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.4 (low), covering capability evidence, pricing, API certainty, version risk, and practical selection criteria.
Read More
GPT-5 vs GPT-5.4 mini (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.4 mini (medium), covering capability evidence, API uncertainty, pricing, latency, version risk, and practical selection criteria.
Read More
GPT-5 vs GPT-5.4 mini: Which Model Should Developers Choose?
A practical comparison of GPT-5 and GPT-5.4 mini across measured capability, coding performance, latency, cost, API status, and deployment risk.
Read More
GPT-5 (high) vs GPT-5.4 nano (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.4 nano (medium), covering measured capability, cost, availability uncertainty, and practical selection risks.
Read More
GPT-5 vs GPT-5.4 nano: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.4 nano across coding capability, reasoning evidence, latency, pricing, version stability, and production risk.
Read More
GPT-5 vs GPT-5.4 Pro (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.4 Pro (xhigh), covering evidence quality, cost, availability, performance, and production risk.
Read More
GPT-5 vs GPT-5.4 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.4 (xhigh), covering coding capability, reasoning, context, cost, tooling, lifecycle risk, and practical selection criteria.
Read More
GPT-5 (high) vs GPT-5.5 (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.5 (high), covering capability, cost, latency, operational risk, and practical model selection.
Read More
GPT-5 (high) vs GPT-5.5 Instant: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.5 Instant, covering evidence quality, benchmark visibility, latency, pricing, API risk, and practical model selection.
Read More
GPT-5 vs GPT-5.5 (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.5 (low), covering capability, cost, evidence quality, API availability, and migration risk.
Read More
GPT-5 (high) vs GPT-5.5 (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.5 (medium), covering capability, cost, context, tooling, reliability, and migration risk.
Read More
GPT-5 vs GPT-5.5 Non-reasoning: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.5 (Non-reasoning), covering coding quality, latency, pricing, API evidence, and migration risk.
Read More
GPT-5 vs GPT-5.5 Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.5 Pro, covering evidence quality, coding use cases, pricing uncertainty, and production risk.
Read More
GPT-5 vs GPT-5.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.5 across coding quality, reasoning, cost, latency, tooling, lifecycle risk, and production fit.
Read More
GPT-5 (high) vs GPT-5.6 Luna (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Luna (high), covering benchmark evidence, pricing, API certainty, speed, and practical selection risks.
Read More
GPT-5 vs GPT-5.6 Luna (low): Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Luna (low), covering coding quality, reasoning evidence, cost, speed, version risk, and practical model selection.
Read More
GPT-5 vs GPT-5.6 Luna (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Luna (medium), covering measured quality, coding evidence, pricing, API uncertainty, and practical selection criteria.
Read More
GPT-5 (high) vs GPT-5.6 Luna (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Luna (xhigh), covering coding quality, cost, latency, evidence gaps, and production fit.
Read More
GPT-5 vs GPT-5.6 Luna: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Luna across capability, speed, cost, tooling, lifecycle risk, and production fit.
Read More
GPT-5 (high) vs GPT-5.6 Sol (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Sol (high), covering capability, coding performance, cost, latency, operational risk, and practical model selection.
Read More
GPT-5 vs GPT-5.6 Sol (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Sol (low), covering coding quality, reasoning evidence, speed, pricing, API certainty, and migration risk.
Read More
GPT-5 vs GPT-5.6 Sol (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Sol (medium), covering coding quality, reasoning evidence, speed, pricing, operational risk, and practical model selection.
Read More
GPT-5 (high) vs GPT-5.6 Sol Non-reasoning: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Sol Non-reasoning across capability, coding, speed, cost, API clarity, and production risk.
Read More
GPT-5 (high) vs GPT-5.6 Sol (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Sol (xhigh), covering capability, speed, pricing, lifecycle risk, and practical selection criteria.
Read More
GPT-5 (high) vs GPT-5.6 Sol (max): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Sol (max), covering capability, cost, latency, coding use cases, operational risks, and evidence gaps.
Read More
GPT-5 (high) vs GPT-5.6 Terra (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Terra (high), covering capability signals, speed, pricing, version risk, and evidence gaps.
Read More
GPT-5 (high) vs GPT-5.6 Terra (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Terra (low), covering capability evidence, pricing, speed, API certainty, migration risk, and practical model selection.
Read More
GPT-5 vs GPT-5.6 Terra (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Terra (medium), covering coding quality, intelligence, speed, cost, evidence gaps, and migration risk.
Read More
GPT-5 vs GPT-5.6 Terra Non-reasoning: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Terra Non-reasoning across coding, intelligence, speed, cost, API status, and evidence quality.
Read More
GPT-5 (high) vs GPT-5.6 Terra (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5.6 Terra (xhigh), covering capability, speed, cost, API status, deployment limits, and practical selection criteria.
Read More
GPT-5 vs GPT-5.6 Terra: Which OpenAI Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5.6 Terra across coding quality, reasoning, speed, cost, tooling, lifecycle risk, and production fit.
Read More
GPT-5 vs GPT-5 Codex (High): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and GPT-5 Codex (high), covering evidence quality, measured capability, pricing, operational risk, and practical model selection.
Read More
GPT-5 (high) vs GPT-5 (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5 (low), covering measured capability, API evidence, pricing, version risk, and practical model-selection trade-offs.
Read More
GPT-5 (high) vs GPT-5 (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 high and medium reasoning settings, covering capability evidence, cost, availability, uncertainty, and practical model selection.
Read More
GPT-5 (high) vs GPT-5 mini (medium): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and GPT-5 mini (medium), covering capability evidence, latency, pricing uncertainty, lifecycle risk, and practical model selection.
Read MoreGPT-5 vs GPT-5 mini: A Developer-Focused Model Selection Guide
A practical comparison of GPT-5 and GPT-5 mini across benchmark quality, speed, latency, pricing, engineering controls, and production uncertainty.
Read More
GPT-5 (high) vs Grok 4.1 Fast (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Grok 4.1 Fast (Reasoning), covering capability evidence, latency, pricing, API risk, and where the available data remains incomplete.
Read More
GPT-5 vs Grok 4.20 0309 v2: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Grok 4.20 0309 v2 across capability evidence, pricing, latency, reliability, and model-selection risk.
Read More
GPT-5 (high) vs Grok 4.3 (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Grok 4.3 (low), covering evidence quality, performance, cost, speed, tooling, and selection risk.
Read More
GPT-5 (high) vs Grok 4.3 (high): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Grok 4.3 (high), covering benchmark evidence, pricing, API certainty, version risk, and practical model-selection trade-offs.
Read More
GPT-5 vs Grok 4.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Grok 4.5 across coding, reasoning, speed, cost, tooling, lifecycle risk, and production fit.
Read More
GPT-5 (high) vs Grok Build 0.1 0616: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Grok Build 0.1 0616 across benchmark evidence, cost, operational certainty, and model-selection risk.
Read More
GPT-5 (high) vs Hy3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Hy3 across coding, reasoning, speed, cost, reliability, and deployment risk.
Read More
GPT-5 (high) vs Inkling Small: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Inkling Small across capability evidence, latency, cost, version risk, and decision confidence.
Read More
GPT-5 (high) vs Inkling (xhigh): Which Model Should Developers Choose?
A source-backed comparison of GPT-5 (high) and Inkling (xhigh) for coding, reasoning, latency, pricing, and production risk.
Read More
GPT-5 (high) vs JT-35B-Flash: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and JT-35B-Flash across capability evidence, latency, pricing, version risk, and practical model-selection tradeoffs.
Read More
GPT-5 (high) vs JT-4.1 Flash 236B A21B: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and JT-4.1 Flash 236B A21B across coding, reasoning, mathematics, latency, pricing, evidence quality, and deployment risk.
Read More
GPT-5 (high) vs KAT-Coder-Pro V1: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and KAT-Coder-Pro V1 across intelligence, mathematics, coding evidence, latency, pricing, and production risk.
Read More
GPT-5 (high) vs KAT Coder Pro V2: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and KAT Coder Pro V2 across coding quality, reasoning evidence, speed, pricing, reliability, and product risk.
Read More
GPT-5 (high) vs Kimi K2.5 (Non-reasoning): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Kimi K2.5 (Non-reasoning), covering evidence quality, reasoning, coding, latency, cost, and production risk.
Read More
GPT-5 (high) vs Kimi K2.5 (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Kimi K2.5 (Reasoning), covering coding quality, reasoning evidence, latency, cost, reliability, and model-selection risk.
Read More
GPT-5 vs Kimi K2.6 Non-reasoning: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Kimi K2.6 Non-reasoning across capability evidence, speed, cost, operational risk, and model-selection fit.
Read More
GPT-5 vs Kimi K2.6: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Kimi K2.6 across coding, intelligence, mathematics, latency, cost, API maturity, and evidence quality.
Read More
GPT-5 (high) vs Kimi K2.7 Code: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Kimi K2.7 Code across coding quality, broader intelligence, speed, pricing, reliability, and evidence quality.
Read More
GPT-5 (high) vs Kimi K2 Thinking: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Kimi K2 Thinking across reasoning evidence, coding signals, latency, pricing, API readiness, and deployment risk.
Read More
GPT-5 vs Kimi K3 (low): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Kimi K3 (low), covering evidence quality, coding performance, cost, operational risk, and model-selection tradeoffs.
Read More
GPT-5 (high) vs LongCat 2.0: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and LongCat 2.0 across coding, reasoning, speed, pricing, API readiness, and evidence quality.
Read More
GPT-5 (high) vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Mi:dm K 2.5 Pro Preview, covering reasoning performance, coding signals, pricing evidence, product risk, and selection criteria.
Read More
GPT-5 (high) vs MiMo-V2-Flash: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiMo-V2-Flash across evidence quality, intelligence, latency, cost, tooling, and production risk.
Read More
GPT-5 vs MiMo-V2.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and MiMo-V2.5 across coding, reasoning evidence, speed, cost, API readiness, and selection risk.
Read More
GPT-5 (high) vs MiMo-V2.5-Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiMo-V2.5-Pro across coding, reasoning, speed, cost, evidence quality, and production risk.
Read More
GPT-5 (high) vs MiMo-V2-Omni-0327: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiMo-V2-Omni-0327 across capability evidence, latency, pricing, version risk, and production suitability.
Read More
GPT-5 (high) vs MiMo-V2-Omni: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiMo-V2-Omni across measured intelligence, coding evidence, latency, pricing, API readiness, and selection risk.
Read More
GPT-5 (high) vs MiMo-V2-Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiMo-V2-Pro covering evidence quality, measured capability, pricing, operational risk, and practical model selection.
Read More
GPT-5 (high) vs MiniMax-M2.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiniMax-M2.5 covering capability evidence, pricing, latency, uncertainty, and practical model selection.
Read More
GPT-5 (high) vs MiniMax-M2.7: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiniMax-M2.7 across coding, intelligence, mathematics, latency, pricing, documentation, and selection risk.
Read More
GPT-5 (high) vs MiniMax-M2: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiniMax-M2 across quality, coding evidence, latency, pricing, reliability, and selection risk.
Read More
GPT-5 (high) vs MiniMax-M3: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and MiniMax-M3 across coding quality, reasoning evidence, latency, cost, reliability, and deployment risk.
Read More
GPT-5 (high) vs Mistral Medium 3.5: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Mistral Medium 3.5 across coding, reasoning, latency, output speed, pricing, version status, and evidence quality.
Read More
GPT-5 (high) vs Motif 3 (Beta): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Motif 3 (Beta), covering capability evidence, pricing, reliability, version risk, and where the available data remains incomplete.
Read More
GPT-5 (high) vs Muse Spark 1.1 (xhigh): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Muse Spark 1.1 (xhigh), covering coding, reasoning, speed, cost, API maturity, multimodal scope, and production risk.
Read More
GPT-5 (high) vs Muse Spark: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Muse Spark across coding quality, reasoning evidence, latency, pricing, API readiness, and selection risk.
Read More
GPT-5 vs Nex-N2-Pro: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Nex-N2-Pro across benchmark evidence, speed, cost, API readiness, and production risk.
Read More
GPT-5 (high) vs Nemotron 3 Ultra 550B A55B: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Nemotron 3 Ultra 550B A55B across measured quality, coding, speed, cost, and production readiness.
Read More
GPT-5 (high) vs Qwen3.5 122B A10B: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.5 122B A10B across coding, reasoning, speed, cost, reliability, and deployment evidence.
Read More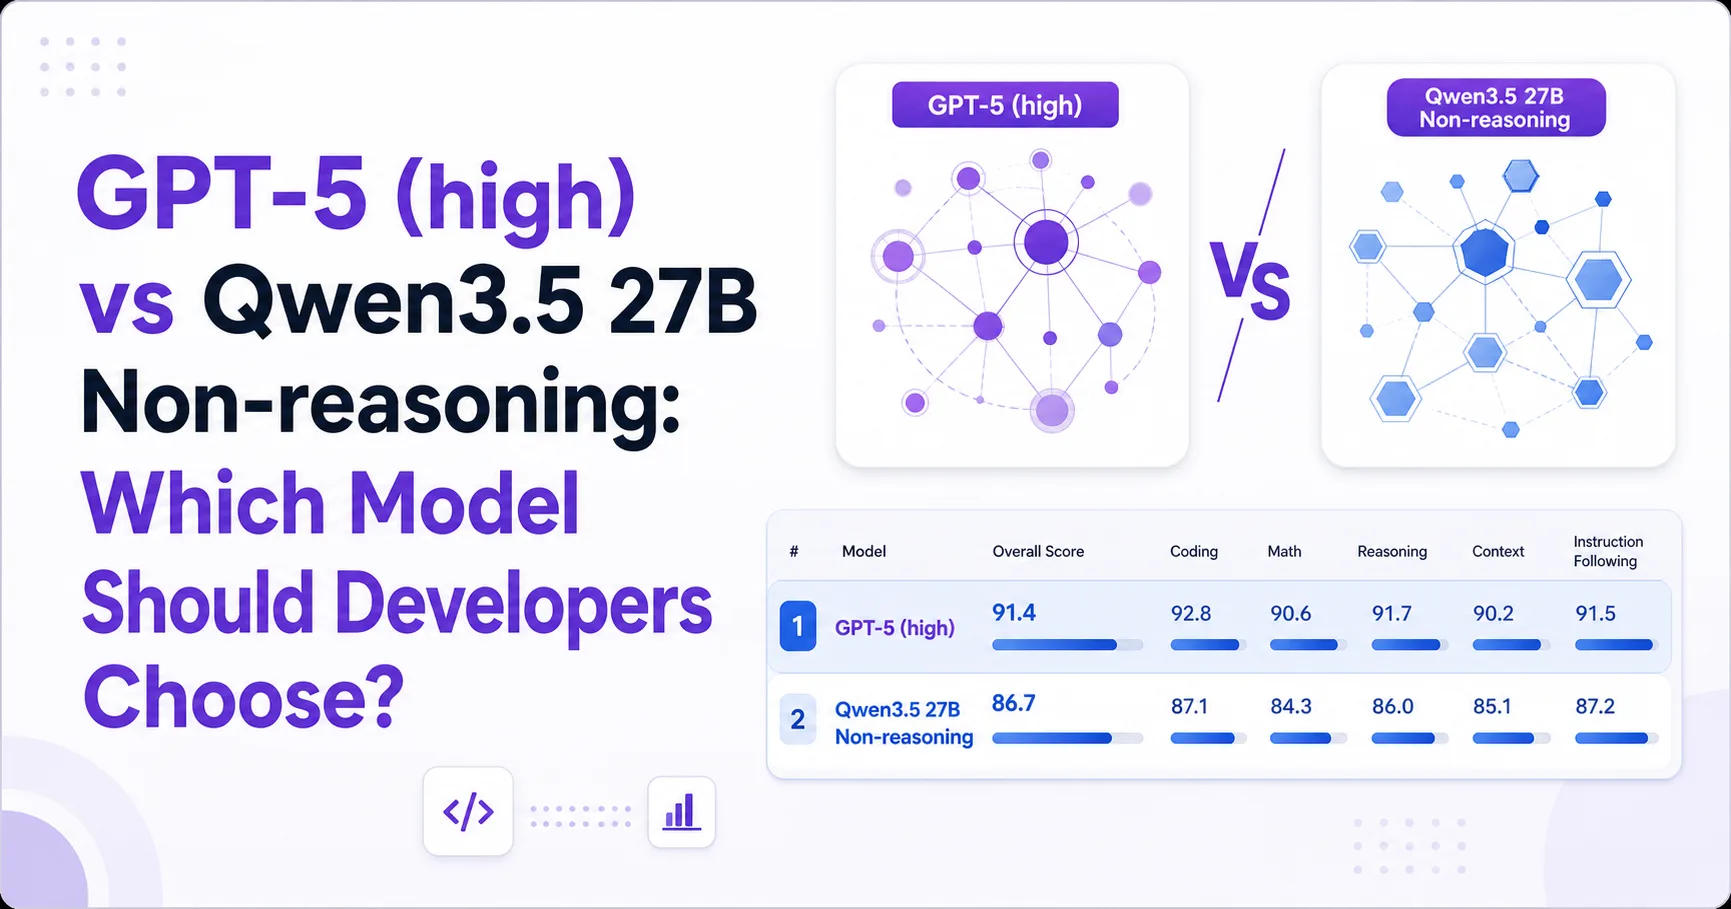
GPT-5 (high) vs Qwen3.5 27B Non-reasoning: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.5 27B Non-reasoning across capability evidence, latency, pricing, deployment risk, and model-selection fit.
Read More
GPT-5 (high) vs Qwen3.5 35B A3B (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.5 35B A3B (Reasoning), covering evidence quality, measured capability, latency, pricing, migration risk, and practical selection criteria.
Read More
GPT-5 vs Qwen3.5 397B A17B: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 and Qwen3.5 397B A17B across capability evidence, latency, pricing, tooling, reliability, and deployment risk.
Read More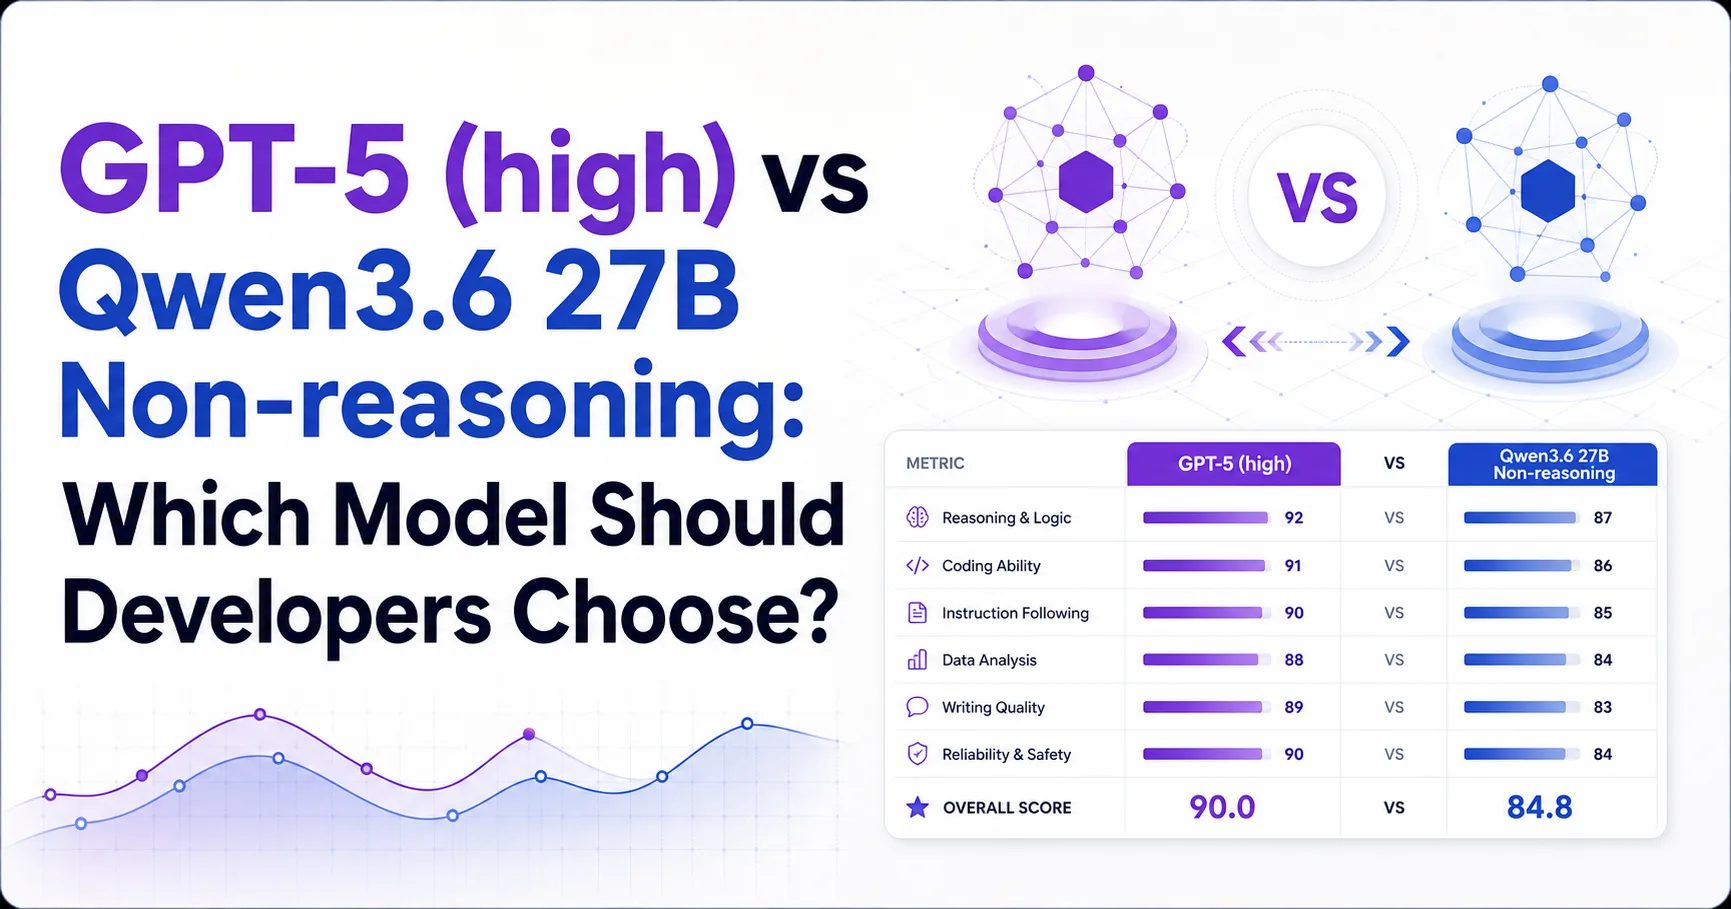
GPT-5 (high) vs Qwen3.6 27B Non-reasoning: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.6 27B Non-reasoning across coding, reasoning, speed, cost, API readiness, and evidence quality.
Read More
GPT-5 (high) vs Qwen3.6 27B (Reasoning): Which Model Should Developers Choose?
GPT-5 offers documented reasoning, tooling, and mathematical performance, while Qwen3.6 27B leads the available coding and cost metrics but lacks verifiable public documentation.
Read More
GPT-5 (high) vs Qwen3.6 35B A3B (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.6 35B A3B (Reasoning), covering coding quality, reasoning, latency, pricing, evidence quality, and production risk.
Read More
GPT-5 (high) vs Qwen3.6 Max Preview: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.6 Max Preview across capability evidence, pricing, latency, reliability, and deployment risk.
Read More
GPT-5 (high) vs Qwen3.6 Plus: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.6 Plus across coding quality, reasoning evidence, latency, pricing, version risk, and production fit.
Read More
GPT-5 (high) vs Qwen3.7 Max: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.7 Max across measured capability, speed, pricing, evidence quality, and production risk.
Read More
GPT-5 (high) vs Qwen3.7 Plus: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3.7 Plus across capability evidence, coding performance, speed, cost, operational risk, and model-selection fit.
Read More
GPT-5 (high) vs Qwen3 Max Thinking: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Qwen3 Max Thinking across evidence, capability, latency, pricing, and production risk.
Read More
GPT-5 (high) vs Ring-2.6-1T: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Ring-2.6-1T across capability, coding, latency, cost, evidence quality, and production risk.
Read More
GPT-5 (high) vs Step 3.7 Flash: Which Model Should Developers Choose?
A developer-focused comparison of GPT-5 (high) and Step 3.7 Flash across capability, coding, speed, cost, reliability, and deployment risk.
Read More
Grok-1 vs Kimi K3 (max): Which Model Should Developers Choose?
A source-aware comparison of Grok-1 and Kimi K3 (max) for developers evaluating capability, cost, speed, reliability, and production readiness.
Read More
Grok-1 vs Mi:dm K 2.5 Pro Preview: Which Model Should Developers Choose?
A developer-focused comparison of Grok-1 and Mi:dm K 2.5 Pro Preview, with emphasis on evidence quality, production readiness, measured capabilities, and selection risk.
Read More
Grok 4.20 0309 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Grok 4.20 0309 (Reasoning) and o3, covering measured capability, speed, pricing, availability uncertainty, and practical selection criteria.
Read More
Grok 4.20 0309 v2 (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Grok 4.20 0309 v2 (Reasoning) and o3, covering measured capability, speed evidence, pricing, availability uncertainty, and practical selection criteria.
Read More
Grok 4.3 (low) vs o3: A Developer-Focused Model Selection Guide
A data-led comparison of Grok 4.3 (low) and o3 covering intelligence scores, math evidence, speed, latency, pricing, availability uncertainty, and developer fit.
Read More
Grok 4.3 (medium) vs o3: Which Model Should Developers Choose?
A practical comparison of Grok 4.3 (medium) and o3 for developers weighing capability, speed, cost, availability, and evidence quality.
Read More
Grok 4.3 (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Grok 4.3 (high) and o3, covering measured capability, speed, cost, availability evidence, and selection risk.
Read More
Grok 4.5 (high) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Grok 4.5 (high) and o3 across intelligence, mathematics, coding, speed, cost, availability, and operational risk.
Read More
Grok 4 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Grok 4 and o3 across reasoning quality, mathematics, latency, pricing, availability evidence, and production risk.
Read More
Grok Build 0.1 0616 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Grok Build 0.1 0616 and o3, covering measured quality, speed, cost, availability, and evidence gaps.
Read More
Hy3-preview (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Hy3-preview (Reasoning) and o3, covering measured intelligence, speed, pricing, availability, evidence quality, and selection risk.
Read More
Hy3 vs o3: Which Model Should Developers Choose?
A data-led comparison of Hy3 and o3 for developers choosing between lower cost, faster output, and stronger evidence for reasoning workloads.
Read More
Inkling Small vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Inkling Small and o3 across measured quality, speed, cost, and current product certainty.
Read More
Inkling (xhigh) vs o3: A Developer Model Selection Guide
A source-aware comparison of Inkling (xhigh) and o3 for developers choosing between lower cost, faster output, stronger measured intelligence, and uncertain availability.
Read More
JT-4.1 Flash 236B A21B vs o3: Which Model Should Developers Choose?
A developer-focused comparison of JT-4.1 Flash 236B A21B and o3 across benchmark evidence, latency, cost, documentation, and production risk.
Read More
KAT Coder Pro V2 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of KAT Coder Pro V2 and o3 across coding evidence, general intelligence, speed, latency, cost, and availability risk.
Read More
Kimi K2.5 (Reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Kimi K2.5 (Reasoning) and o3 covering measured capability, pricing, availability evidence, and the risks of choosing a model with incomplete documentation.
Read More
Kimi K2.6 (Non-reasoning) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Kimi K2.6 (Non-reasoning) and o3 across intelligence, mathematics, speed, latency, cost, and current availability evidence.
Read More
Kimi K2.6 vs o3: Which Model Should Developers Choose?
A data-grounded comparison of Kimi K2.6 and o3 for developer model selection, covering capability evidence, speed, cost, availability, and uncertainty.
Read More
Kimi K2.7 Code vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Kimi K2.7 Code and o3 across coding evidence, reasoning signals, speed, pricing, and model availability.
Read More
Kimi K2 Thinking vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Kimi K2 Thinking and o3 across reasoning results, cost, speed evidence, availability, and production risk.
Read More
Kimi K3 (low) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Kimi K3 (low) and o3 across measured quality, speed, cost, and production-readiness evidence.
Read More
Kimi K3 (max) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Kimi K3 (max) and o3 across capability evidence, speed, cost, availability, and production risk.
Read More
LongCat 2.0 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of LongCat 2.0 and o3 across measured intelligence, speed, pricing, availability, and evidence quality.
Read More
MiMo-V2-Flash (Feb 2026) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiMo-V2-Flash (Feb 2026) and o3 across intelligence, mathematics, latency, speed, pricing, and production readiness.
Read More
MiMo-V2.5 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiMo-V2.5 and o3 across measured quality, speed, cost, availability evidence, and selection risk.
Read More
MiMo-V2.5-Pro vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiMo-V2.5-Pro and o3 across intelligence, mathematics, coding evidence, speed, cost, availability, and deployment risk.
Read More
MiMo-V2-Omni-0327 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiMo-V2-Omni-0327 and o3 across measured intelligence, mathematics, latency, output speed, pricing, and model availability evidence.
Read More
MiMo-V2-Omni vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiMo-V2-Omni and o3 across intelligence, mathematics, latency, speed, pricing, availability, and evidence quality.
Read More
MiMo-V2-Pro vs o3: Which Model Should Developers Choose?
A practical comparison of MiMo-V2-Pro and o3 for developers choosing between measured capability, cost, speed, and production availability.
Read More
MiniMax-M2.5 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiniMax-M2.5 and o3 across measured intelligence, math coverage, speed, pricing, and current availability evidence.
Read More
MiniMax-M2.7 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiniMax-M2.7 and o3, covering benchmark evidence, pricing, operational uncertainty, and model-selection risk.
Read More
MiniMax-M3 vs o3: Which Model Should Developers Choose?
A developer-focused comparison of MiniMax-M3 and o3 across benchmark evidence, speed, cost, availability signals, and decision risk.
Read More
Motif 3 (Beta) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Motif 3 (Beta) and o3 across measured intelligence, coding and math signals, latency, speed, pricing, and deployment confidence.
Read More
Muse Spark 1.1 (xhigh) vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Muse Spark 1.1 and o3 across intelligence, speed, pricing, API availability, and production risk.
Read More
Muse Spark vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Muse Spark and o3 covering measured capability, speed, pricing, documentation, and production risk.
Read More
Nex-N2-Pro vs o3: Which Model Should Developers Choose?
Nex-N2-Pro is faster, substantially cheaper, and scores higher on the available general intelligence index, while o3 has the only reported math score. The larger decision is evidence quality: neither model has a fully verified current capability and availability profile in the supplied research.
Read More
Nemotron 3 Ultra 550B A55B vs o3: Which Model Should Developers Choose?
A developer-focused comparison of Nemotron 3 Ultra 550B A55B and o3 across measured quality, coding evidence, speed, latency, pricing, and deployment confidence.
Read More
o3 vs o3-pro: Which OpenAI Reasoning Model Should Developers Choose?
A developer-focused comparison of o3 and o3-pro covering reasoning quality, speed, pricing, API clarity, evidence gaps, and practical model selection.
Read Moreo3 vs Qwen3.5 122B A10B (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of o3 and Qwen3.5 122B A10B (Reasoning), covering benchmark evidence, speed, pricing, model availability, and selection risk.
Read More
o3 vs Qwen3.5 397B A17B (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of o3 and Qwen3.5 397B A17B (Reasoning), covering benchmark evidence, speed, pricing, availability uncertainty, and practical selection criteria.
Read More
o3 vs Qwen3.6 27B (Reasoning): Which Model Should Developers Choose?
A developer-focused comparison of o3 and Qwen3.6 27B (Reasoning), covering measured intelligence, speed, pricing, availability evidence, and selection risks.
Read More
o3 vs Qwen3.6 Max Preview: Which Model Should Developers Choose?
A developer-focused comparison of o3 and Qwen3.6 Max Preview across measured intelligence, mathematics, speed, latency, pricing, and deployment certainty.
Read More
o3 vs Qwen3.6 Plus: Which Model Should Developers Choose?
A developer-focused comparison of o3 and Qwen3.6 Plus across measured intelligence, mathematics, coding evidence, speed, latency, cost, and deployment certainty.
Read More
o3 vs Qwen3.7 Max: Which Model Should Developers Choose?
A developer-focused comparison of o3 and Qwen3.7 Max across measured quality, speed, cost, availability evidence, and practical selection risk.
Read More
o3 vs Qwen3.7 Plus: Which Model Should Developers Choose?
A data-driven comparison of o3 and Qwen3.7 Plus covering measured quality, speed, cost, availability evidence, and developer selection risks.
Read More